Working with multiple endpoints
2026-09-18
Source:vignettes/multiple-endpoints.Rmd
multiple-endpoints.Rmd
Multiple endpoints
Joint PK/PD models, or PK/PD models where you fix certain components are common in pharmacometrics. A classic example, (provided by Tomoo Funaki and Nick Holford) is Warfarin.
In this example, we have a transit-compartment (from depot to gut to central volume) PK model and an effect compartment for the PCA measurement.
Below is an illustrated example of a model that can be applied to the data:
pk.turnover.emax <- function() {
  ini({
    tktr <- log(1)
    tka <- log(1)
    tcl <- log(0.1)
    tv <- log(10)
    ##
    eta.ktr ~ 1
    eta.ka ~ 1
    eta.cl ~ 2
    eta.v ~ 1
    prop.err <- 0.1
    pkadd.err <- 0.1
    ##
    temax <- logit(0.8)
    #temax <- 7.5
    tec50 <- log(0.5)
    tkout <- log(0.05)
    te0 <- log(100)
    ##
    eta.emax ~ .5
    eta.ec50  ~ .5
    eta.kout ~ .5
    eta.e0 ~ .5
    ##
    pdadd.err <- 10
  })
  model({
    ktr <- exp(tktr + eta.ktr)
    ka <- exp(tka + eta.ka)
    cl <- exp(tcl + eta.cl)
    v <- exp(tv + eta.v)
    ##
    #poplogit = log(temax/(1-temax))
    emax=expit(temax+eta.emax)
    #logit=temax+eta.emax
    ec50 =  exp(tec50 + eta.ec50)
    kout = exp(tkout + eta.kout)
    e0 = exp(te0 + eta.e0)
    ##
    DCP = center/v
    PD=1-emax*DCP/(ec50+DCP)
    ##
    effect(0) = e0
    kin = e0*kout
    ##
    d/dt(depot) = -ktr * depot
    d/dt(gut) =  ktr * depot -ka * gut
    d/dt(center) =  ka * gut - cl / v * center
    d/dt(effect) = kin*PD -kout*effect
    ##
    cp = center / v
    cp ~ prop(prop.err) + add(pkadd.err)
    effect ~ add(pdadd.err)
  })
}
Notice there are two endpoints in the model cp and
effect. Both are modeled in nlmixr using the ~
“modeled by” specification.
To see more about how nlmixr will handle the multiple compartment model, it is quite informative to parse the model and print the information about that model. In this case an initial parsing would give:
ui <- nlmixr(pk.turnover.emax)
uiIn the middle of the printout, it shows how the data must be
formatted (using the cmt and dvid data items)
to allow nlmixr to model the multiple endpoint appropriately.
Of course, if you are interested you can directly access the
information in ui$multipleEndpoint.
ui$multipleEndpoint
#>     variable                   cmt                   dvid*
#> 1     cp ~ …     cmt='cp' or cmt=5     dvid='cp' or dvid=1
#> 2 effect ~ … cmt='effect' or cmt=4 dvid='effect' or dvid=2
Notice that the cmt and dvid items can use
the named variables directly as either the cmt or
dvid specification. This flexible notation makes it so you
do not have to rename your compartments to run nlmixr model
functions.
The other thing to note is that the cp is specified by
an ODE compartment above the number of compartments defined in the
rxode2 part of the nlmixr model. This is
because cp is not a defined compartment, but a related
variable cp.
The last thing to notice that the cmt items are numbered
cmt=5 for cp or cmt=4 for
effect even though they were specified in the model first
by cp and cmt. This ordering is because
effect is a compartment in the rxode2 system.
Of course cp is related to the compartment
center, and it may make more sense to pair cp
with the center compartment.
If this is something you want to have you can specify the compartment
to relate the effect to by the | operator. In this case you
would change
cp ~ prop(prop.err) + add(pkadd.err)to
cp ~ prop(prop.err) + add(pkadd.err) | centerWith this change, the model could be updated to:
pk.turnover.emax2 <- function() {
  ini({
    tktr <- log(1)
    tka <- log(1)
    tcl <- log(0.1)
    tv <- log(10)
    ##
    eta.ktr ~ 1
    eta.ka ~ 1
    eta.cl ~ 2
    eta.v ~ 1
    prop.err <- 0.1
    pkadd.err <- 0.1
    ##
    temax <- logit(0.8)
    tec50 <- log(0.5)
    tkout <- log(0.05)
    te0 <- log(100)
    ##
    eta.emax ~ .5
    eta.ec50  ~ .5
    eta.kout ~ .5
    eta.e0 ~ .5
    ##
    pdadd.err <- 10
  })
  model({
    ktr <- exp(tktr + eta.ktr)
    ka <- exp(tka + eta.ka)
    cl <- exp(tcl + eta.cl)
    v <- exp(tv + eta.v)
    ##
    emax=expit(temax+eta.emax)
    ec50 =  exp(tec50 + eta.ec50)
    kout = exp(tkout + eta.kout)
    e0 = exp(te0 + eta.e0)
    ##
    DCP = center/v
    PD=1-emax*DCP/(ec50+DCP)
    ##
    effect(0) = e0
    kin = e0*kout
    ##
    d/dt(depot) = -ktr * depot
    d/dt(gut) =  ktr * depot -ka * gut
    d/dt(center) =  ka * gut - cl / v * center
    d/dt(effect) = kin*PD -kout*effect
    ##
    cp = center / v
    cp ~ prop(prop.err) + add(pkadd.err) | center
    effect ~ add(pdadd.err)
  })
}
ui2 <- nlmixr(pk.turnover.emax2)
ui2$multipleEndpoint
#>     variable                   cmt                   dvid*
#> 1     cp ~ … cmt='center' or cmt=3 dvid='center' or dvid=1
#> 2 effect ~ … cmt='effect' or cmt=4 dvid='effect' or dvid=2
Notice in this case the cmt variables are numbered
sequentially and the cp variable matches the
center compartment.
DVID vs CMT, which one is used
When dvid and cmt are combined in the same
dataset, the cmt data item is always used on the event
information and the dvid is used on the observations.
nlmixr expects the cmt data item to match the
dvid item for observations OR to be either zero or one for
the dvid to replace the cmt information.
If you do not wish to use dvid items to define multiple
endpoints in nlmixr, you can set the following option:
options(rxode2.combine.dvid=FALSE)
ui2$multipleEndpoint
#>     variable                   cmt
#> 1     cp ~ … cmt='center' or cmt=3
#> 2 effect ~ … cmt='effect' or cmt=4
Then only cmt items are used for the multiple endpoint
models. Of course you can turn it on or off for different models if you
wish:
options(rxode2.combine.dvid=TRUE)
ui2$multipleEndpoint
#>     variable                   cmt                   dvid*
#> 1     cp ~ … cmt='center' or cmt=3 dvid='center' or dvid=1
#> 2 effect ~ … cmt='effect' or cmt=4 dvid='effect' or dvid=2
Running a multiple endpoint model
With this information, we can use the built-in warfarin dataset in
nlmixr2:
summary(warfarin)
#>        id             time             amt                dv          dvid
#>  Min.   : 1.00   Min.   :  0.00   Min.   :  0.000   Min.   :  0.00   cp :283
#>  1st Qu.: 8.00   1st Qu.: 24.00   1st Qu.:  0.000   1st Qu.:  4.50   pca:232
#>  Median :15.00   Median : 48.00   Median :  0.000   Median : 11.40
#>  Mean   :16.08   Mean   : 52.08   Mean   :  6.524   Mean   : 20.02
#>  3rd Qu.:24.00   3rd Qu.: 96.00   3rd Qu.:  0.000   3rd Qu.: 26.00
#>  Max.   :33.00   Max.   :144.00   Max.   :153.000   Max.   :100.00
#>       evid               wt              age            sex
#>  Min.   :0.00000   Min.   : 40.00   Min.   :21.00   female:101
#>  1st Qu.:0.00000   1st Qu.: 60.00   1st Qu.:23.00   male  :414
#>  Median :0.00000   Median : 70.00   Median :28.00
#>  Mean   :0.06214   Mean   : 69.27   Mean   :31.85
#>  3rd Qu.:0.00000   3rd Qu.: 78.00   3rd Qu.:36.00
#>  Max.   :1.00000   Max.   :102.00   Max.   :63.00
Since dvid specifies pca as the effect endpoint, you can
update the model to be more explicit making one last change:
cp ~ prop(prop.err) + add(pkadd.err)
effect ~ add(pdadd.err)
to
cp ~ prop(prop.err) + add(pkadd.err)
effect ~ add(pdadd.err)  | pca
pk.turnover.emax3 <- function() {
  ini({
    tktr <- log(1)
    tka <- log(1)
    tcl <- log(0.1)
    tv <- log(10)
    ##
    eta.ktr ~ 1
    eta.ka ~ 1
    eta.cl ~ 2
    eta.v ~ 1
    prop.err <- 0.1
    pkadd.err <- 0.1
    ##
    temax <- logit(0.8)
    tec50 <- log(0.5)
    tkout <- log(0.05)
    te0 <- log(100)
    ##
    eta.emax ~ .5
    eta.ec50  ~ .5
    eta.kout ~ .5
    eta.e0 ~ .5
    ##
    pdadd.err <- 10
  })
  model({
    ktr <- exp(tktr + eta.ktr)
    ka <- exp(tka + eta.ka)
    cl <- exp(tcl + eta.cl)
    v <- exp(tv + eta.v)
    emax = expit(temax+eta.emax)
    ec50 =  exp(tec50 + eta.ec50)
    kout = exp(tkout + eta.kout)
    e0 = exp(te0 + eta.e0)
    ##
    DCP = center/v
    PD=1-emax*DCP/(ec50+DCP)
    ##
    effect(0) = e0
    kin = e0*kout
    ##
    d/dt(depot) = -ktr * depot
    d/dt(gut) =  ktr * depot -ka * gut
    d/dt(center) =  ka * gut - cl / v * center
    d/dt(effect) = kin*PD -kout*effect
    ##
    cp = center / v
    cp ~ prop(prop.err) + add(pkadd.err)
    effect ~ add(pdadd.err) | pca
  })
}
Run the models with SAEM
fit.TOS := nlmixr(pk.turnover.emax3, warfarin, "saem", control=list(print=0),
                  table=list(cwres=TRUE, npde=TRUE))

print(fit.TOS)
#> ── nlmixr² SAEM OBJF by FOCEi approximation ──
#>
#>           OBJF      AIC      BIC Log-likelihood Condition#(Cov) Condition#(Cor)
#> FOCEi 1392.341 2318.036 2397.456      -1140.018        275.3437        1.877299
#>
#> ── Time (sec $time): ──
#>
#>             setup   optimize covariance preprocess configure   saem postprocess
#> elapsed 0.8764073 3.4052e-05 0.06400701      0.045     1.546 71.933       0.016
#>          table compress
#> elapsed 14.805     0.19
#>
#> ── Population Parameters ($parFixed or $parFixedDf): ──
#>
#>              Est.        SE      %RSE Back-transformed(95%CI) BSV(CV% or SD)
#> tktr        0.151     0.162       107      1.16 (0.846, 1.60)           69.4
#> tka       -0.0724     0.134       184     0.930 (0.716, 1.21)           50.3
#> tcl         -1.97    0.0503      2.56    0.140 (0.127, 0.155)           26.9
#> tv           2.00    0.0413      2.07       7.40 (6.83, 8.03)           20.6
#> prop.err    0.126    0.0270      21.3   0.126 (0.0735, 0.179)
#> pkadd.err   0.784    0.0967      12.3    0.784 (0.594, 0.973)
#> temax        2.75    0.0152     0.554    0.940 (0.938, 0.941)         0.0761
#> tec50      -0.241    0.0103      4.26    0.786 (0.770, 0.802)           50.5
#> tkout       -2.89 5.46e-310 1.89e-308 0.0556 (0.0556, 0.0556)           5.05
#> te0          4.57 9.88e-324         0       96.6 (96.6, 96.6)           4.89
#> pdadd.err    3.84 6.24e-310 1.62e-308       3.84 (3.84, 3.84)
#>           Shrink(SD)%
#> tktr            55.2
#> tka             58.9
#> tcl             6.65
#> tv              16.8
#> prop.err
#> pkadd.err
#> temax           88.9
#> tec50           8.55
#> tkout           53.4
#> te0             18.0
#> pdadd.err
#>
#>   Covariance Type ($covMethod): sa
#>   Fixed parameter correlations in $cor
#>   No correlations in between subject variability (BSV) matrix
#>   Full BSV covariance ($omega) or correlation ($omegaR; diagonals=SDs)
#>   Distribution stats (mean/skewness/kurtosis/p-value) available in $shrink
#>   Censoring ($censInformation): No censoring
#>
#> ── Fit Data (object is a modified tibble): ──
#> # A tibble: 483 × 44
#>   ID     TIME CMT      DV EPRED  ERES  NPDE    NPD    PDE     PD  PRED   RES
#>   <fct> <dbl> <chr> <dbl> <dbl> <dbl> <dbl>  <dbl>  <dbl>  <dbl> <dbl> <dbl>
#> 1 1       0.5 cp      0    1.71 -1.71 -1.71 -1.43  0.0433 0.0767  1.29 -1.29
#> 2 1       1   cp      1.9  4.05 -2.15  1.88 -0.915 0.97   0.18    3.73 -1.83
#> 3 1       2   cp      3.3  7.97 -4.67 -2.05 -1.61  0.02   0.0533  8.13 -4.83
#> # ℹ 480 more rows
#> # ℹ 32 more variables: WRES <dbl>, IPRED <dbl>, IRES <dbl>, IWRES <dbl>,
#> #   CPRED <dbl>, CRES <dbl>, CWRES <dbl>, eta.ktr <dbl>, eta.ka <dbl>,
#> #   eta.cl <dbl>, eta.v <dbl>, eta.emax <dbl>, eta.ec50 <dbl>, eta.kout <dbl>,
#> #   eta.e0 <dbl>, depot <dbl>, gut <dbl>, center <dbl>, effect <dbl>,
#> #   ktr <dbl>, ka <dbl>, cl <dbl>, v <dbl>, emax <dbl>, ec50 <dbl>, kout <dbl>,
#> #   e0 <dbl>, DCP <dbl>, PD.1 <dbl>, kin <dbl>, tad <dbl>, dosenum <int>
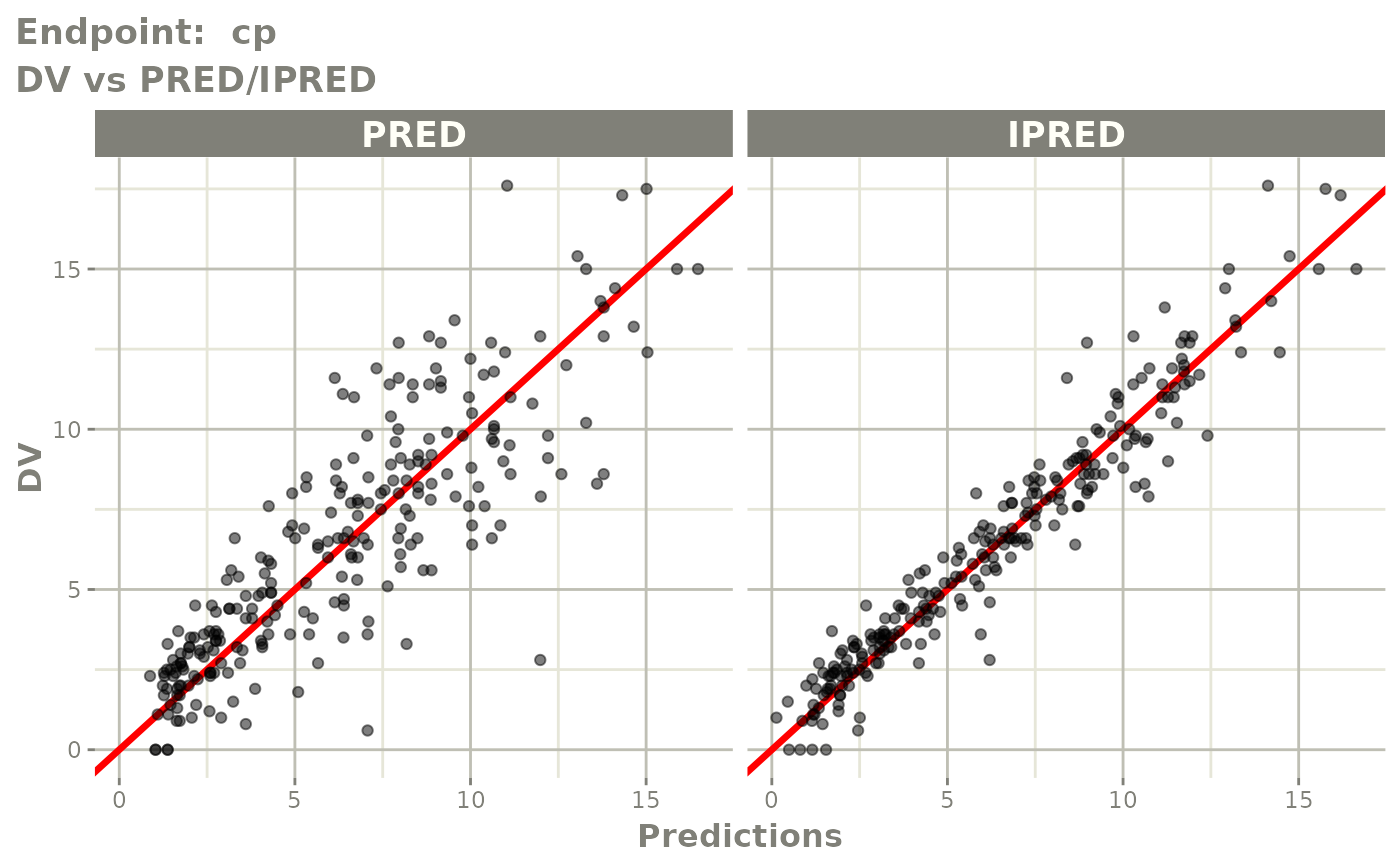
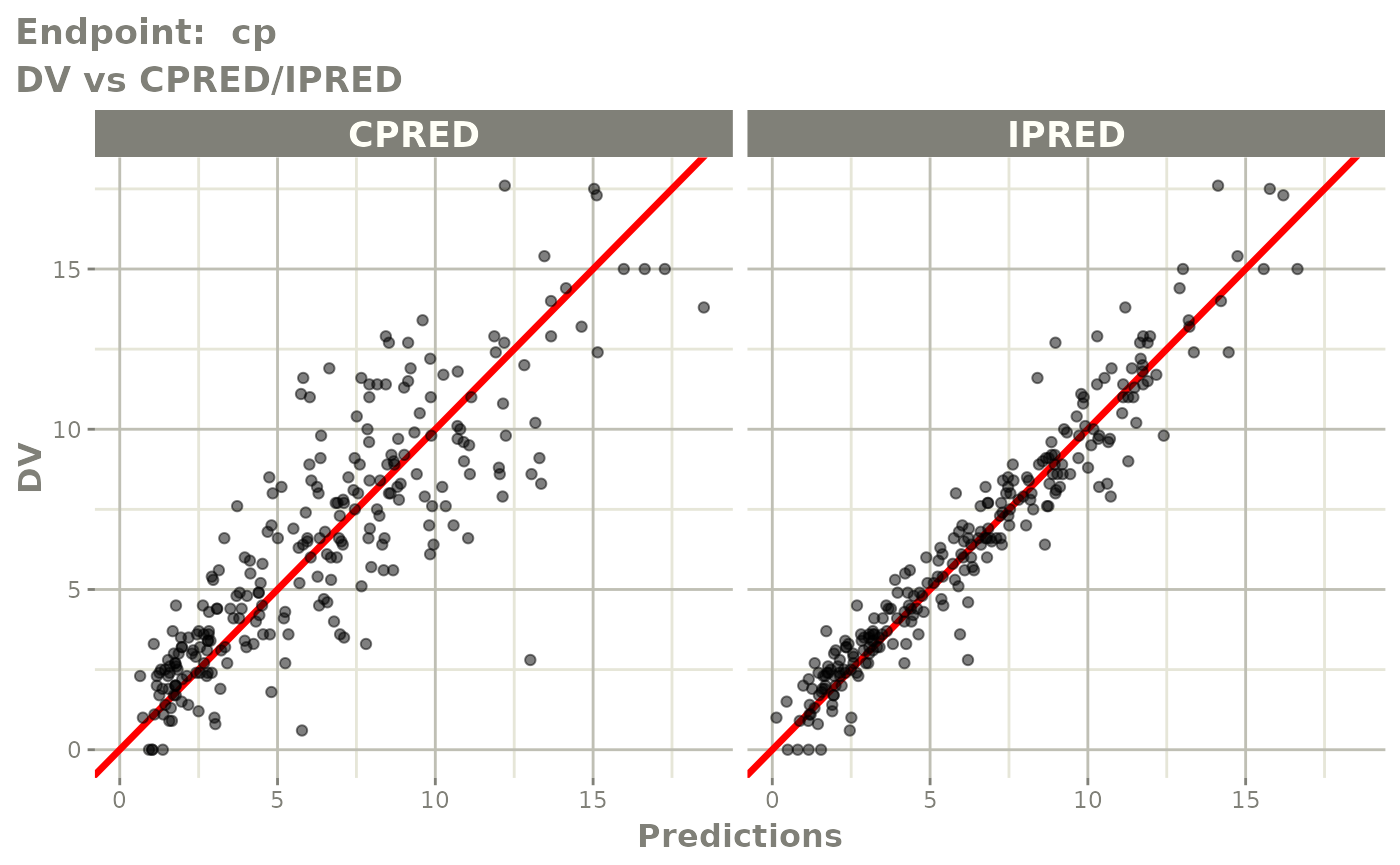
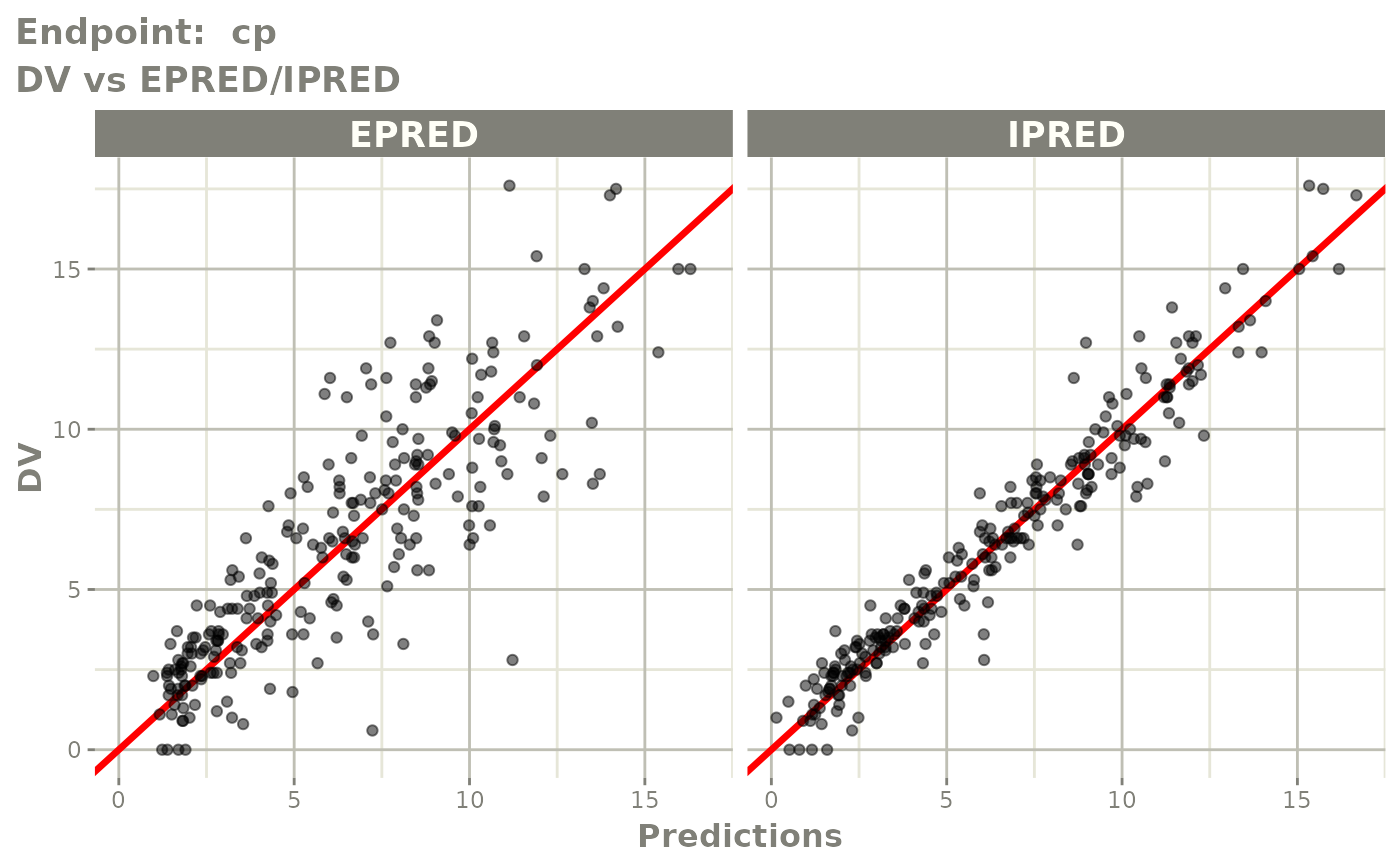
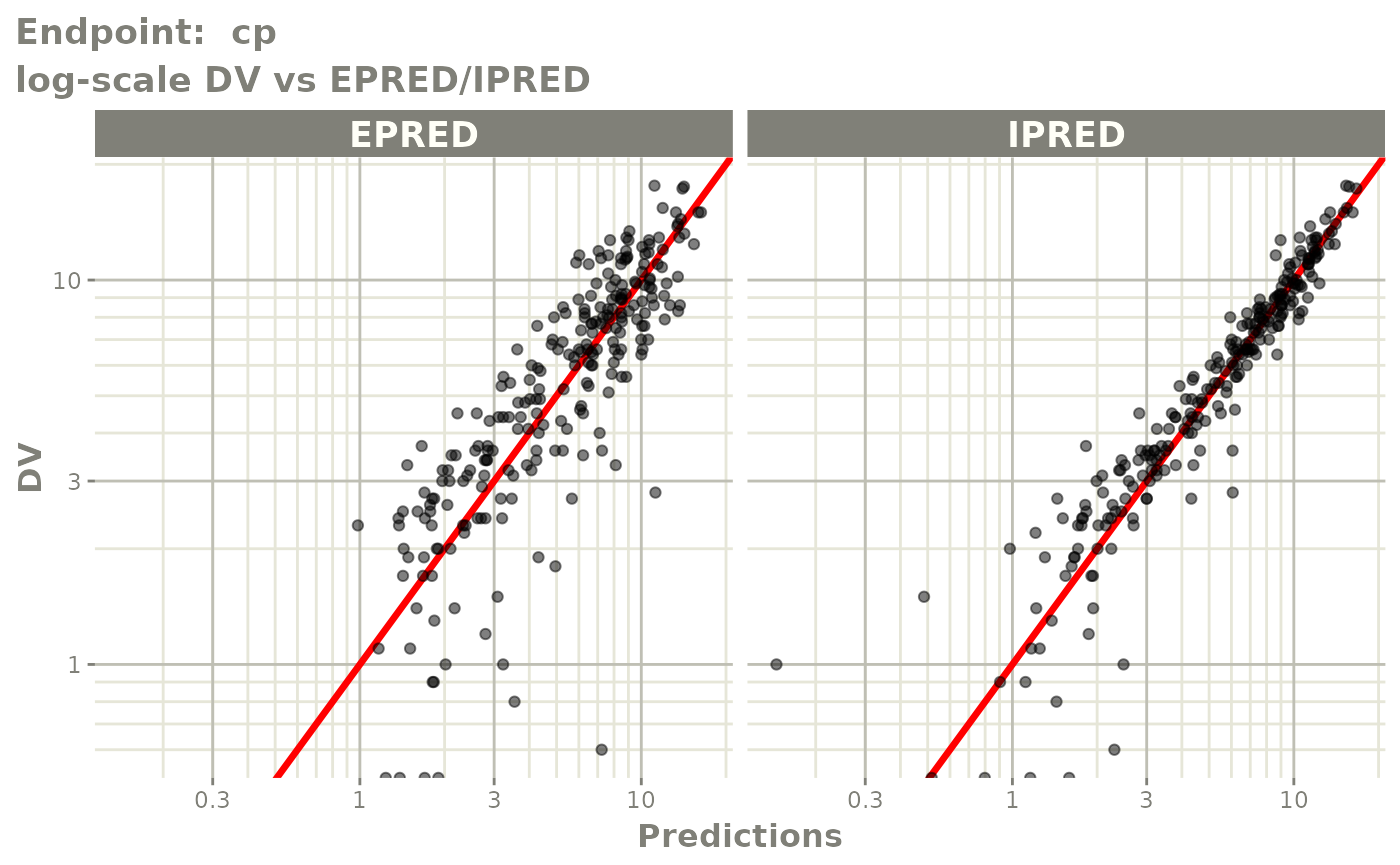
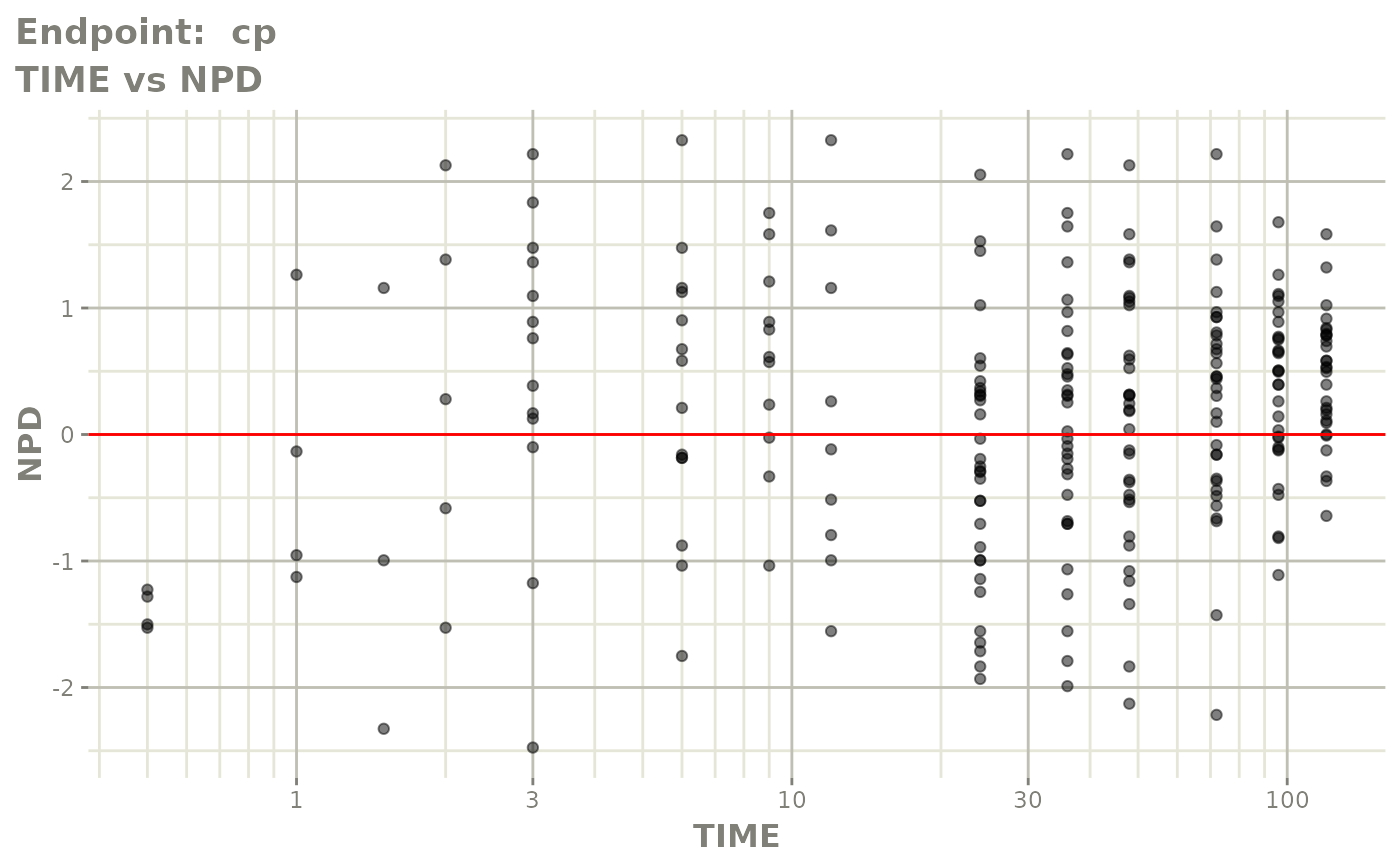
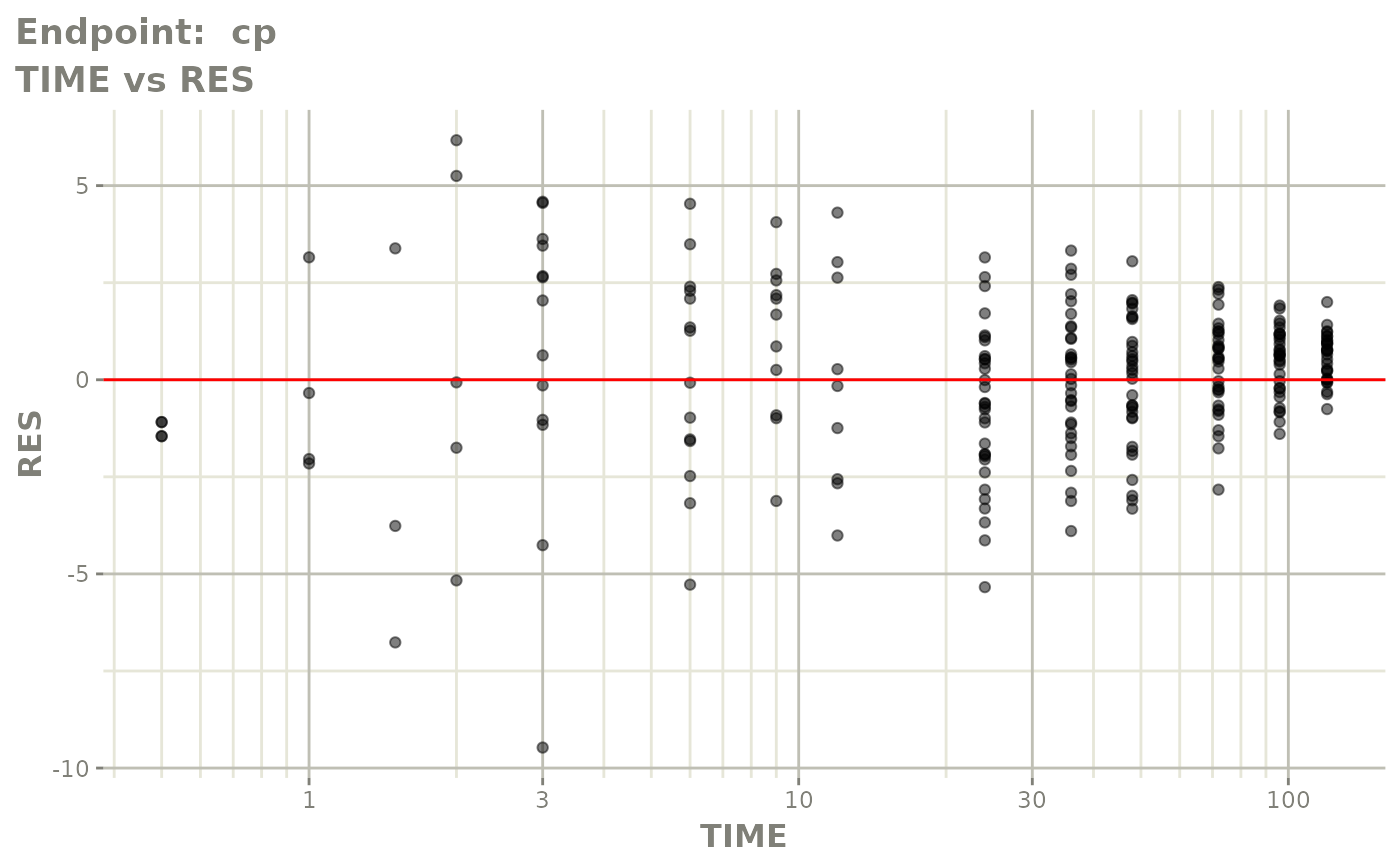
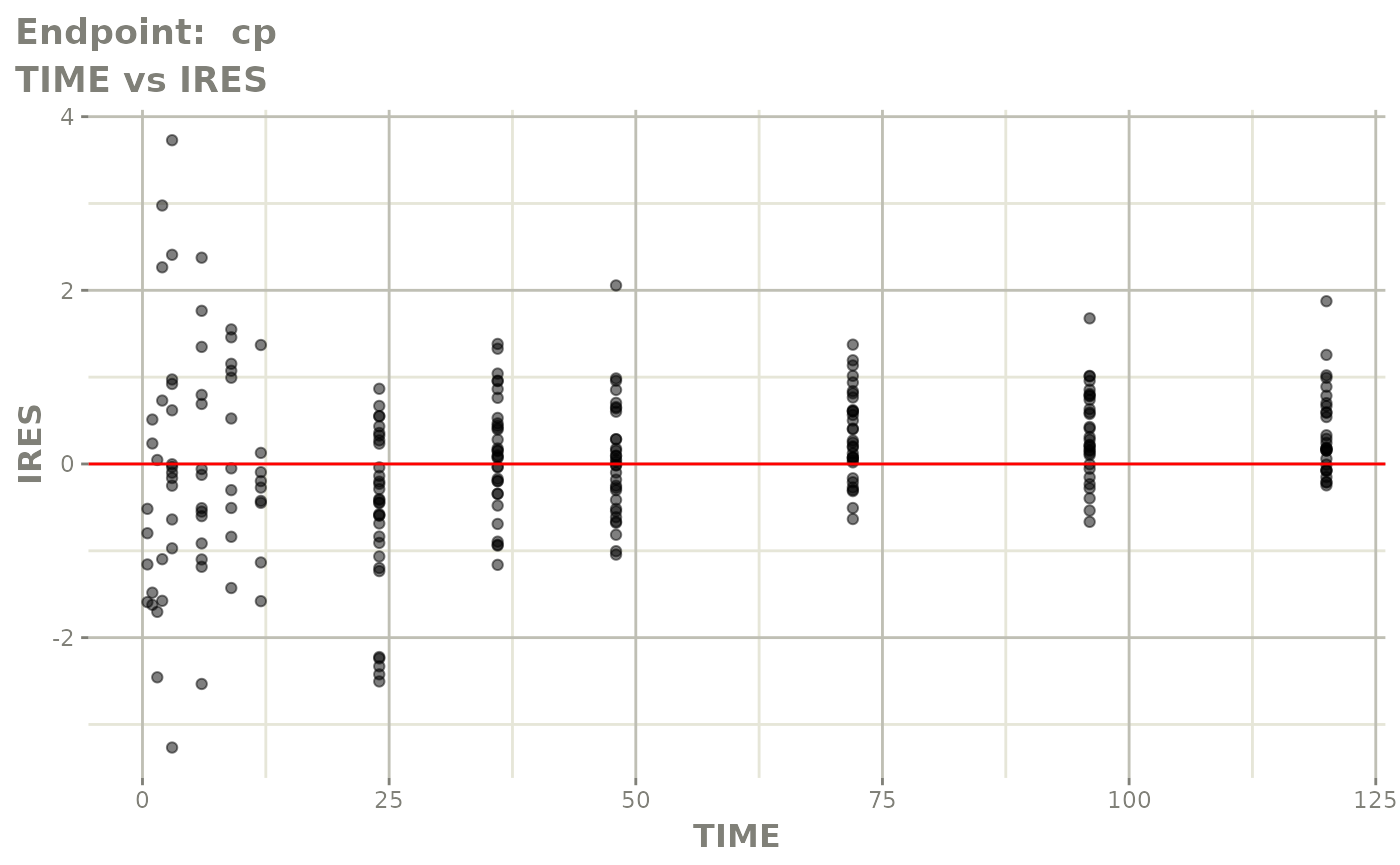
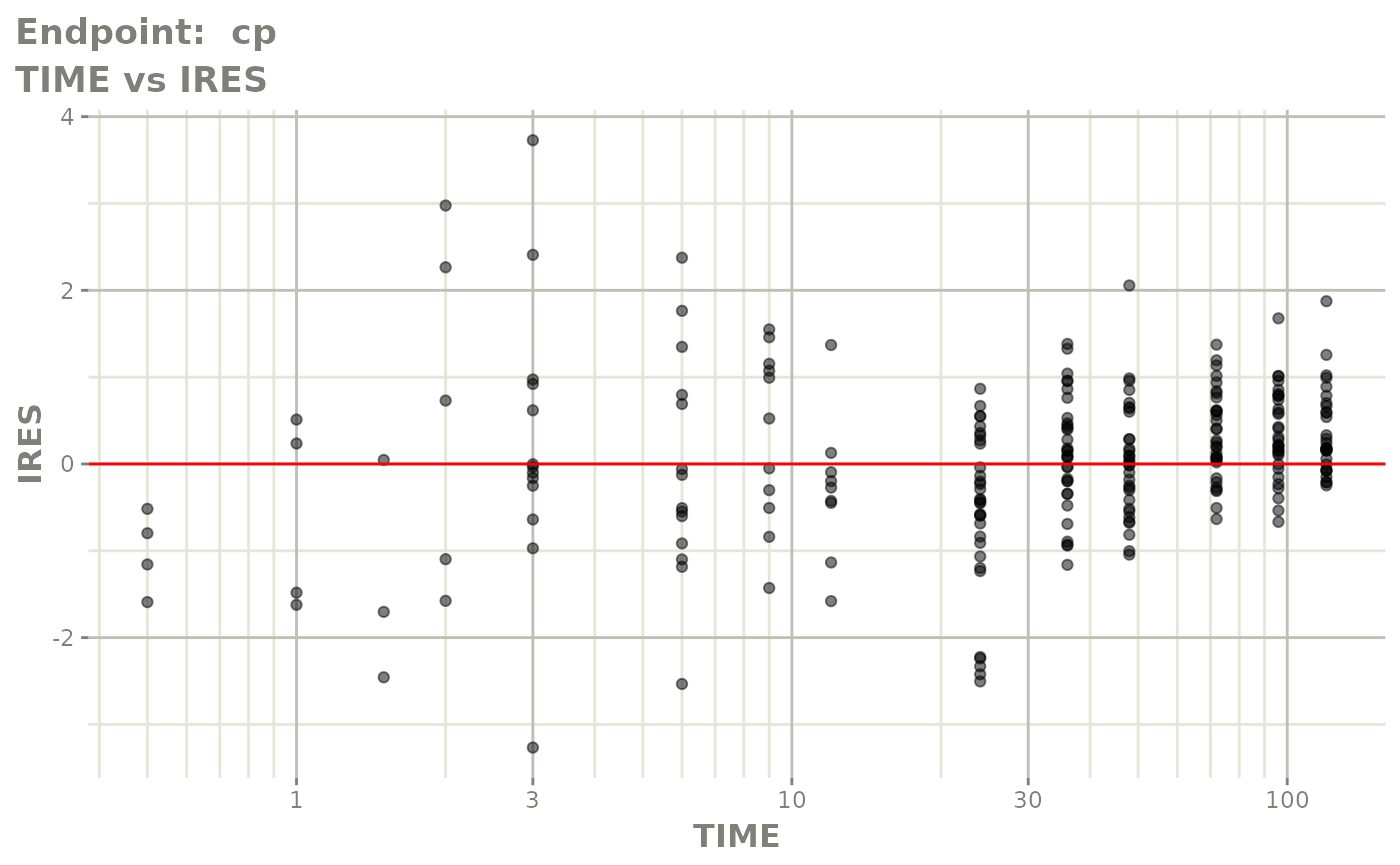
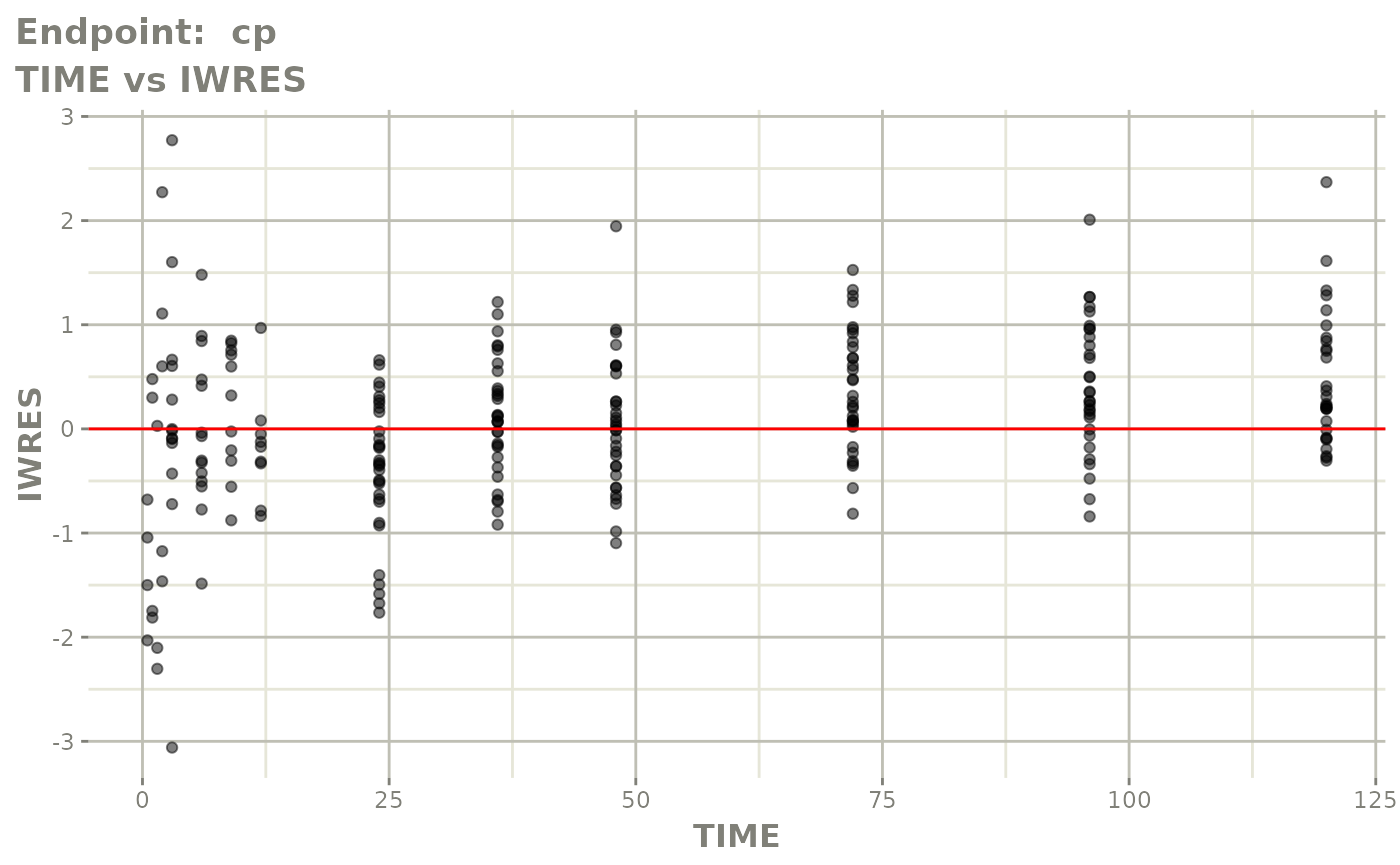
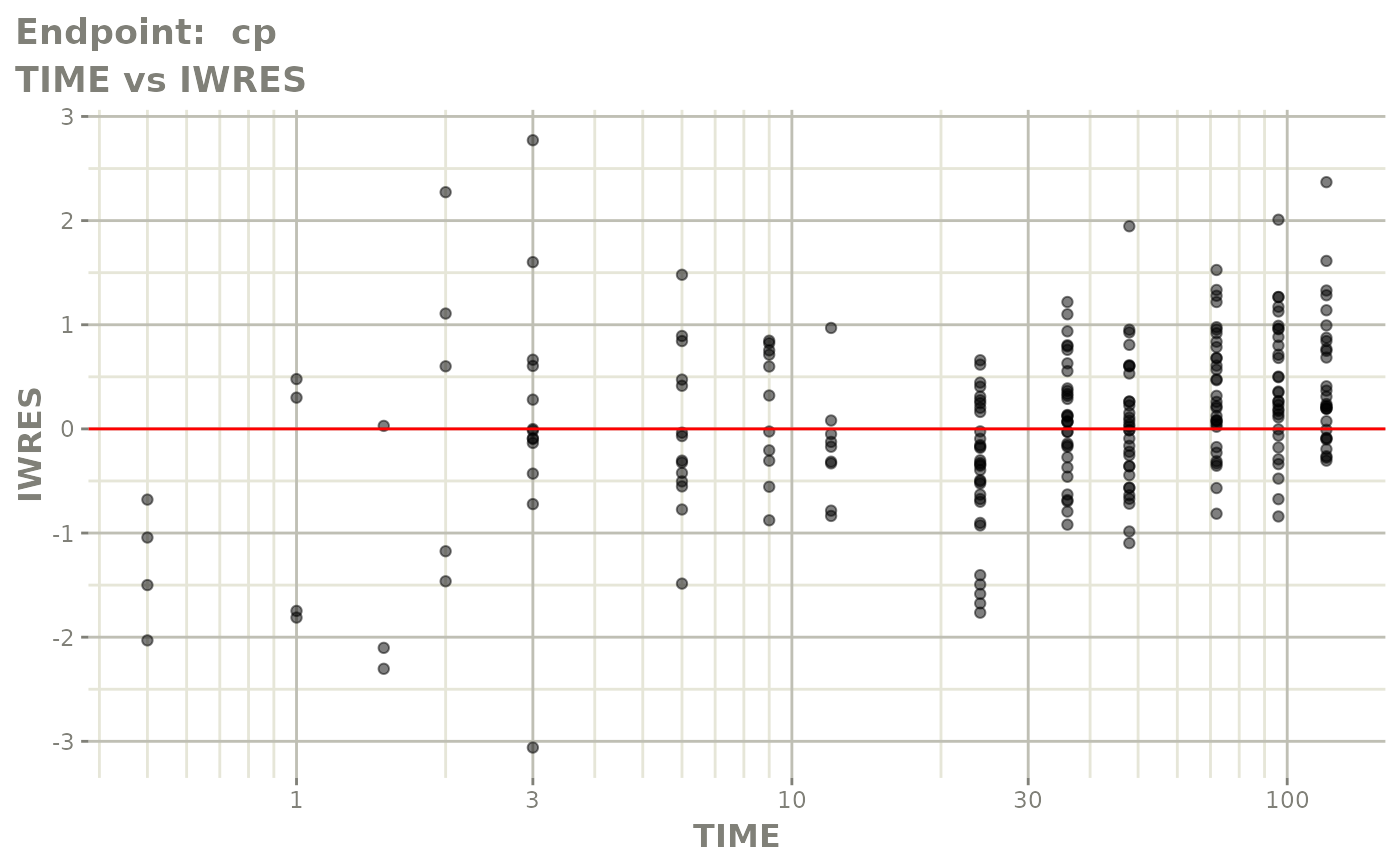
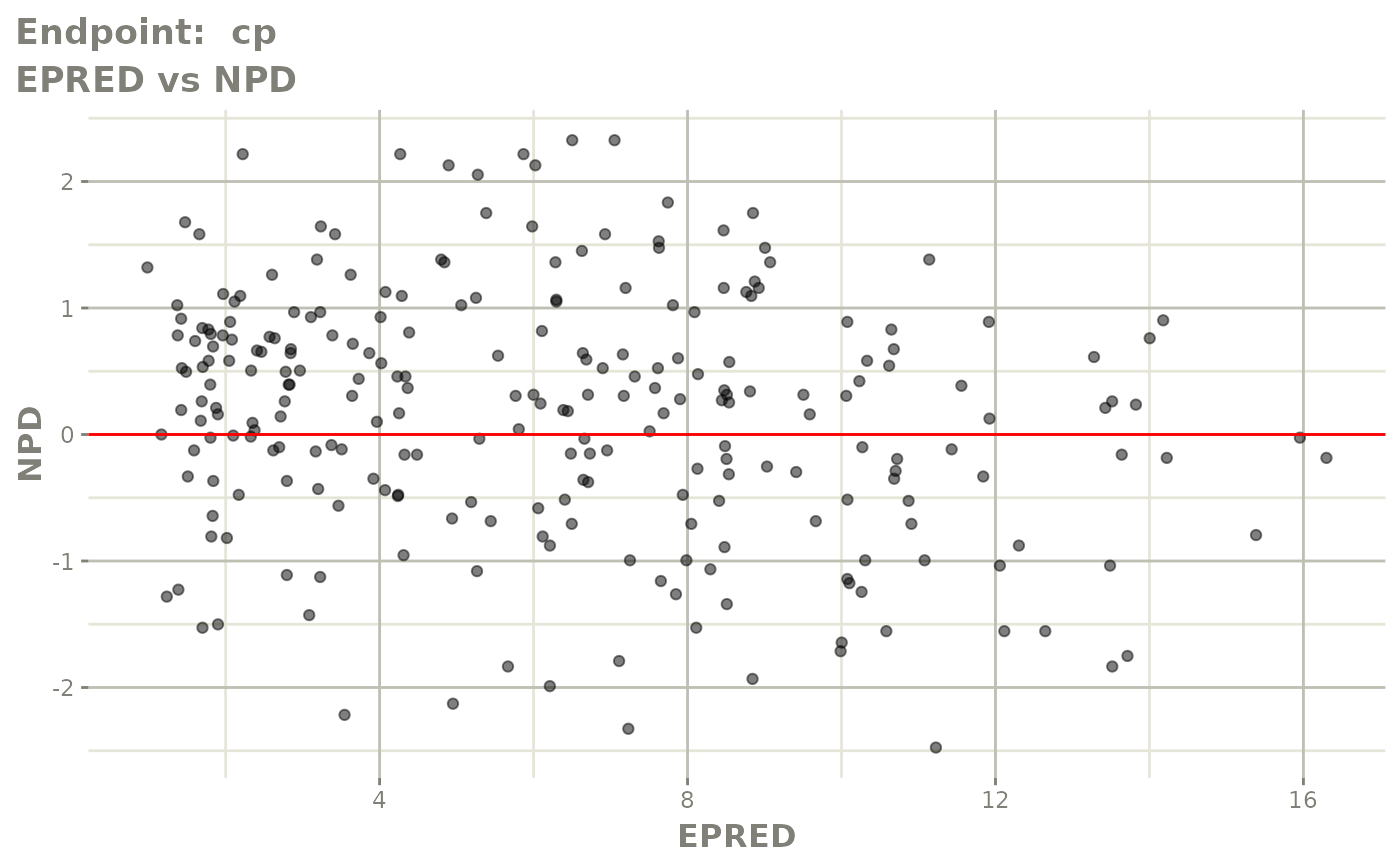
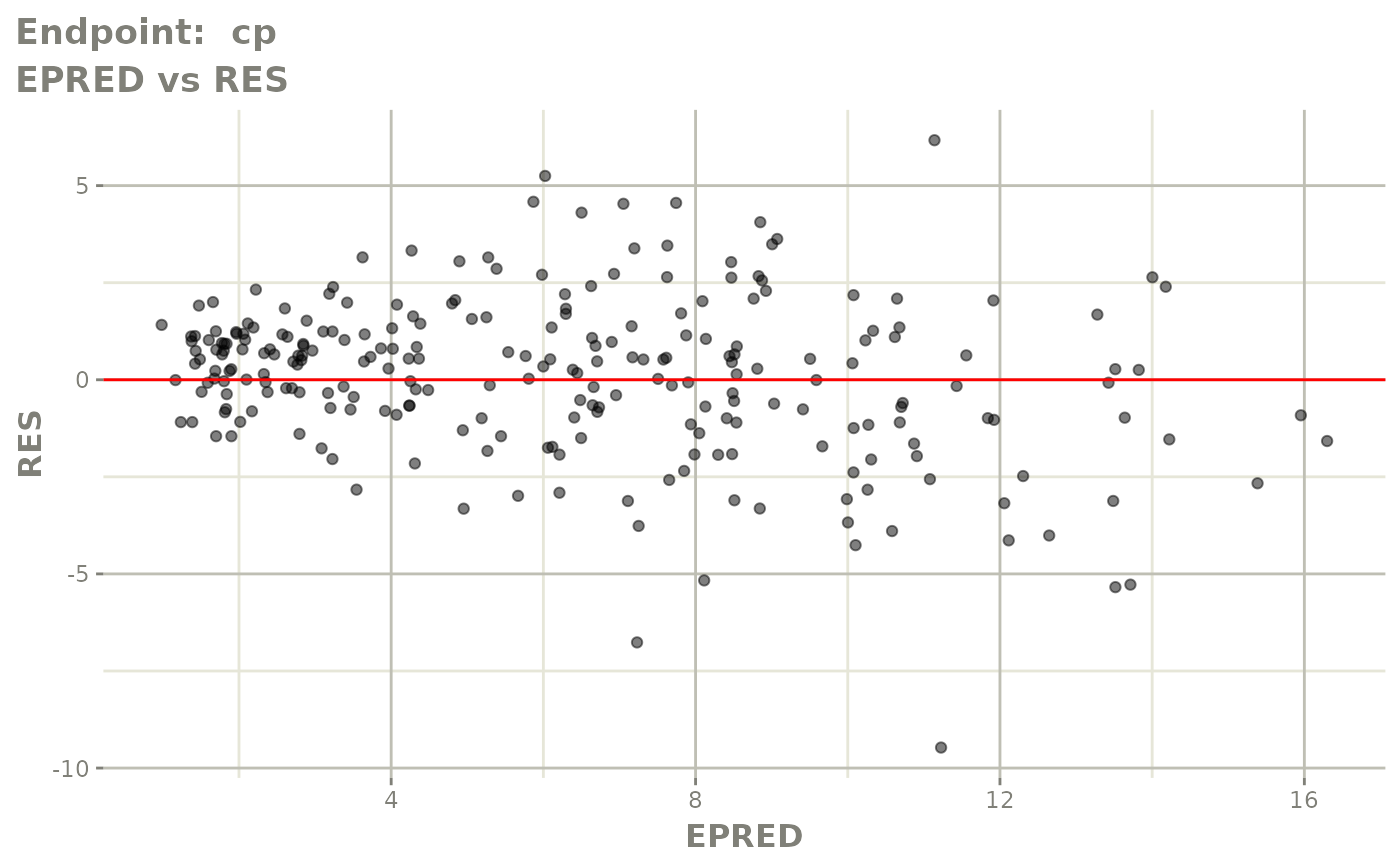
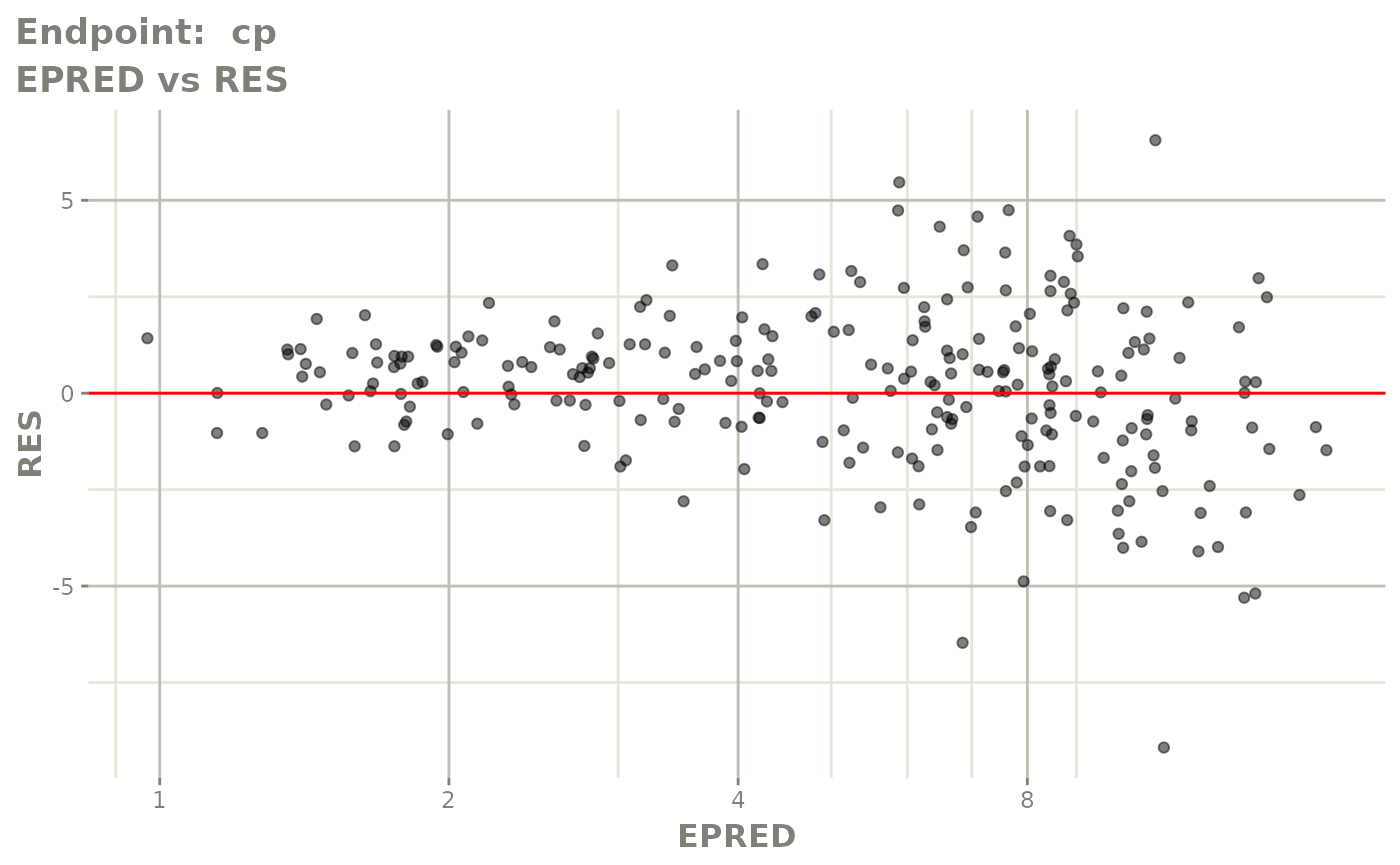
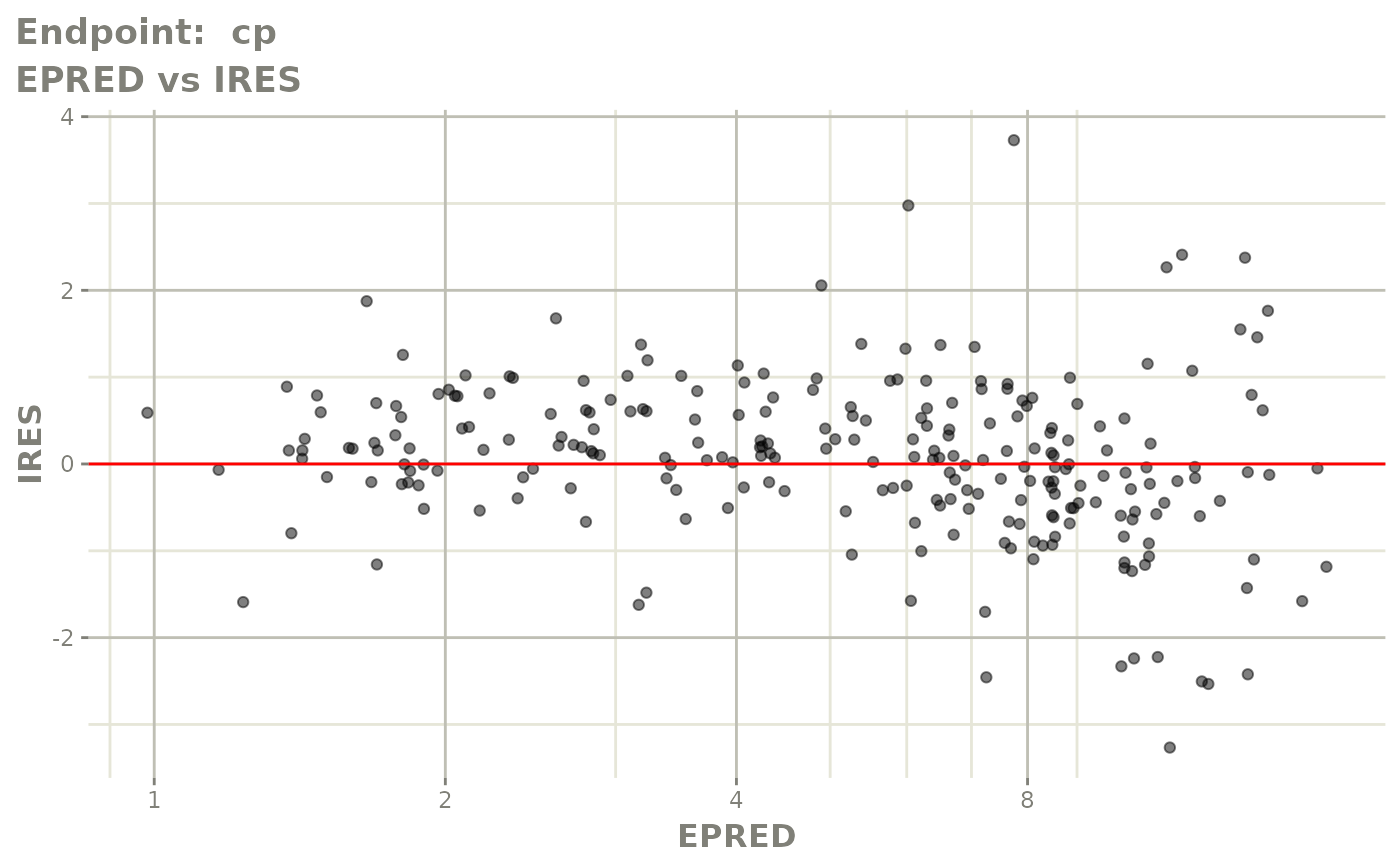
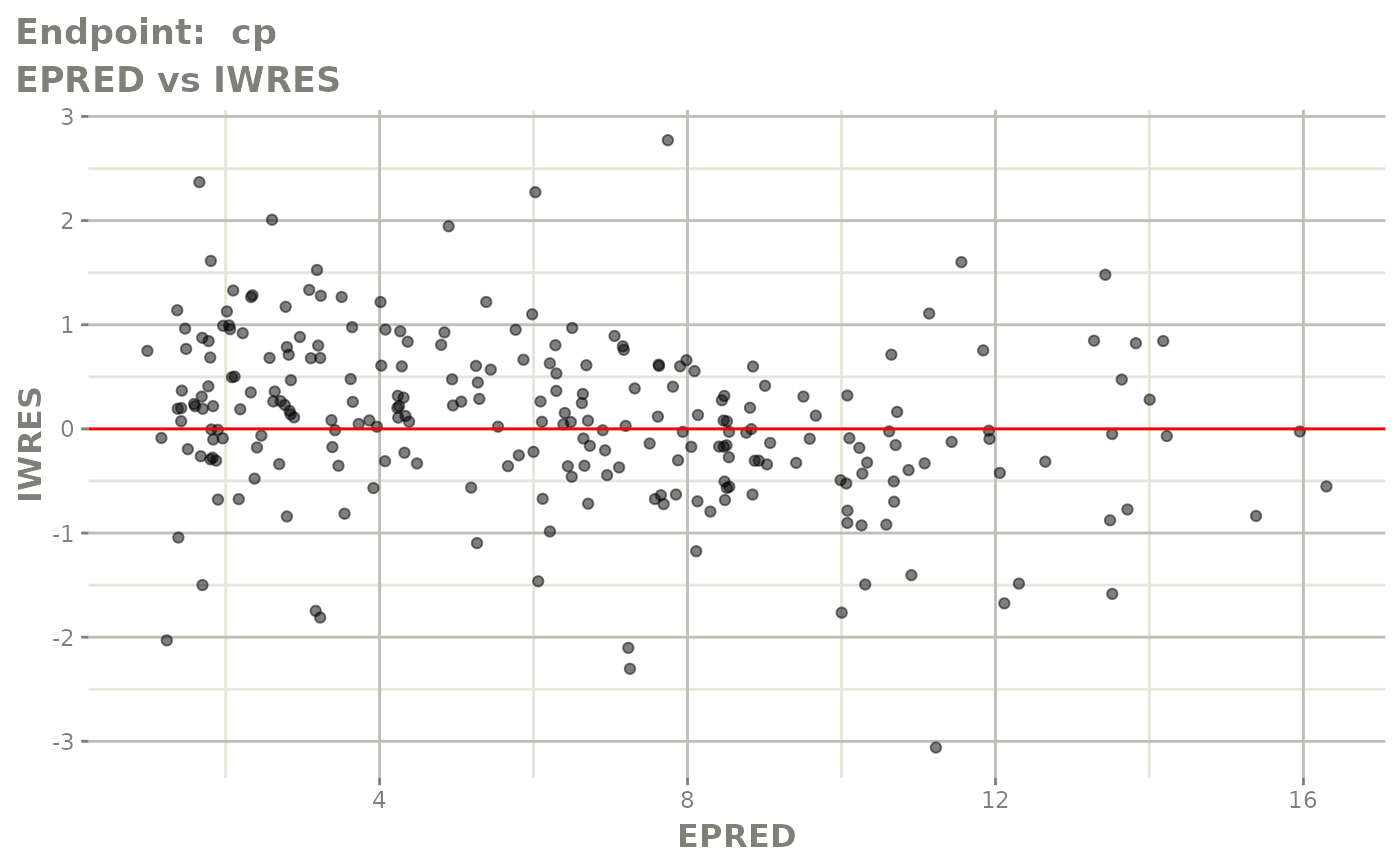
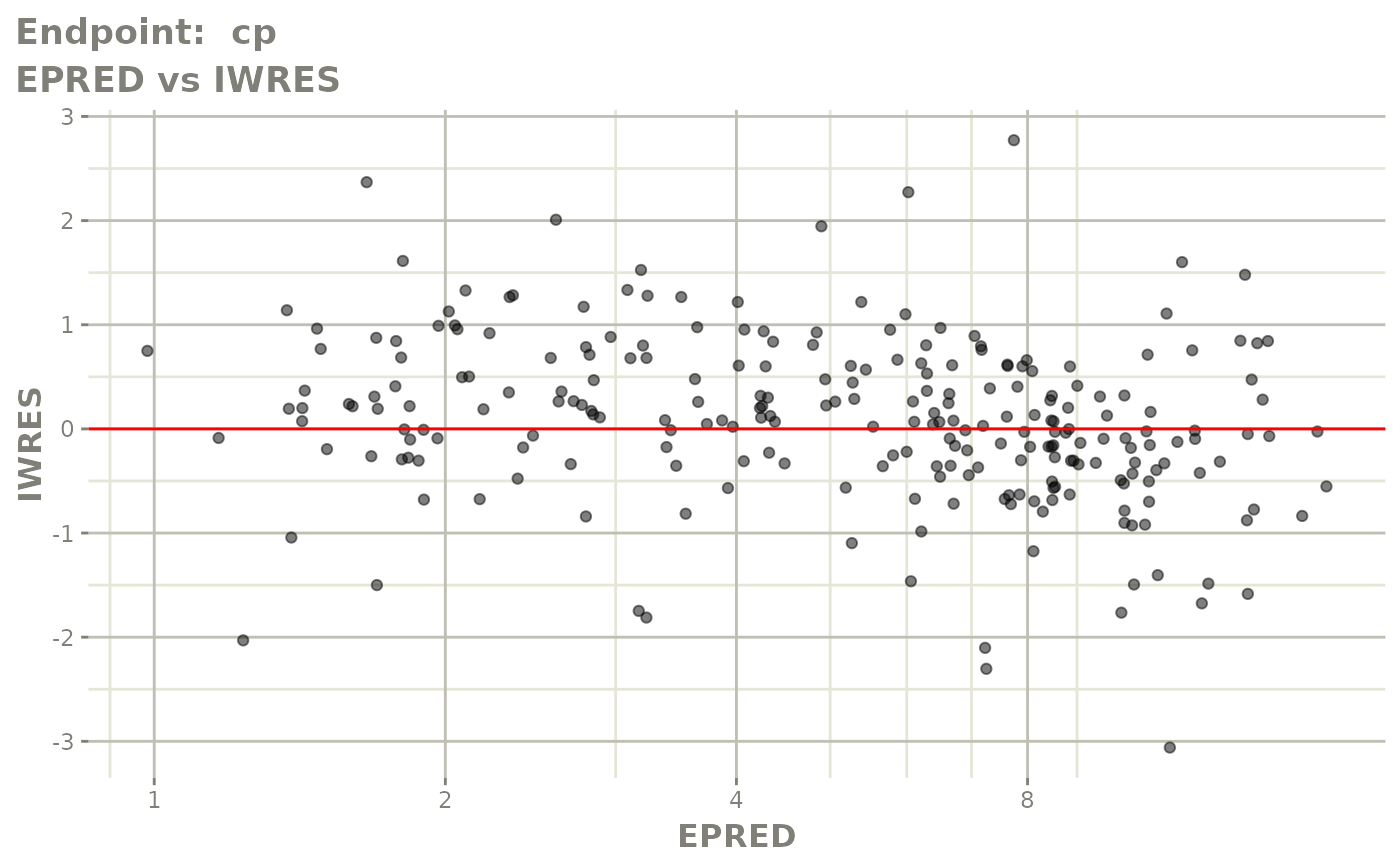
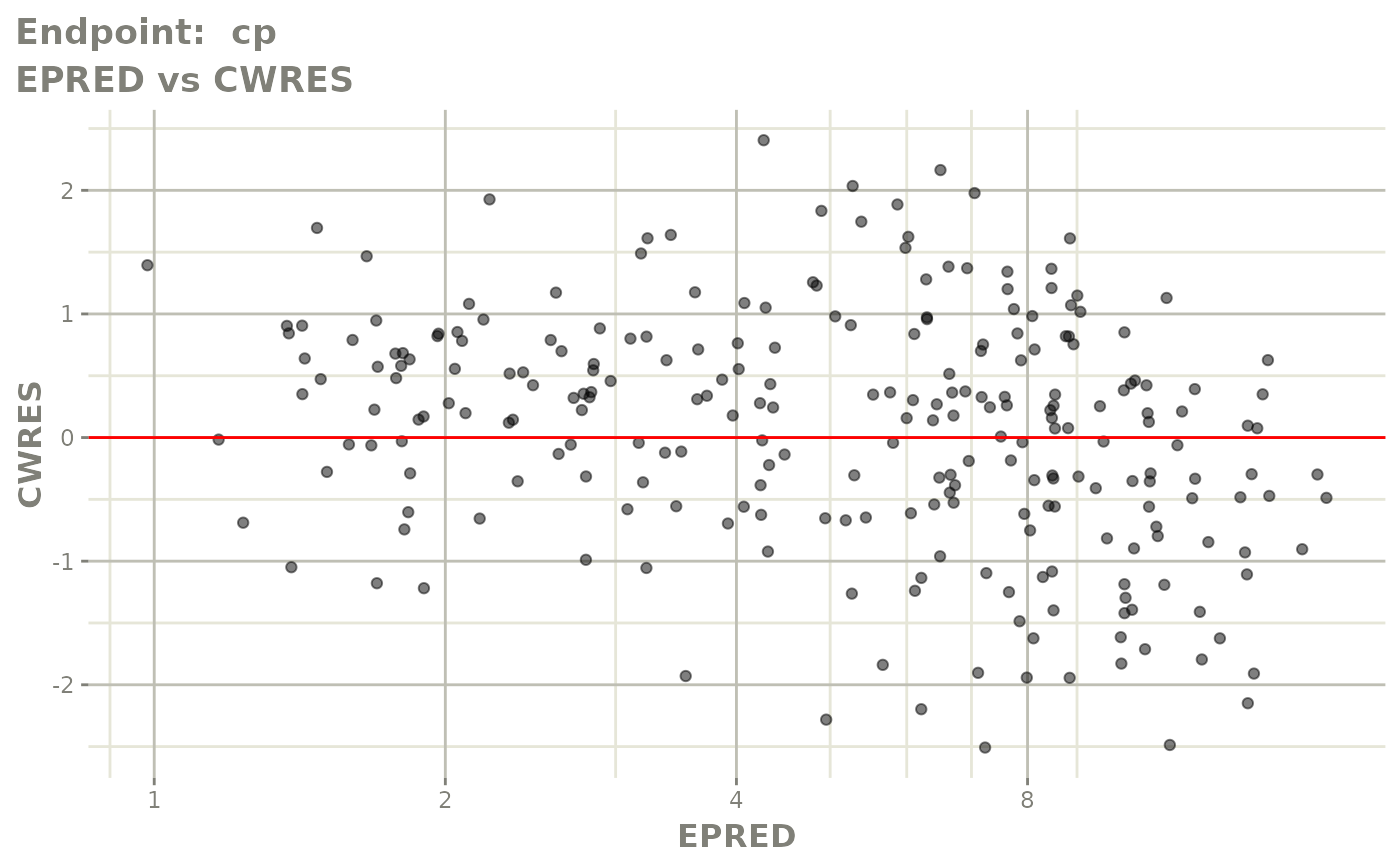
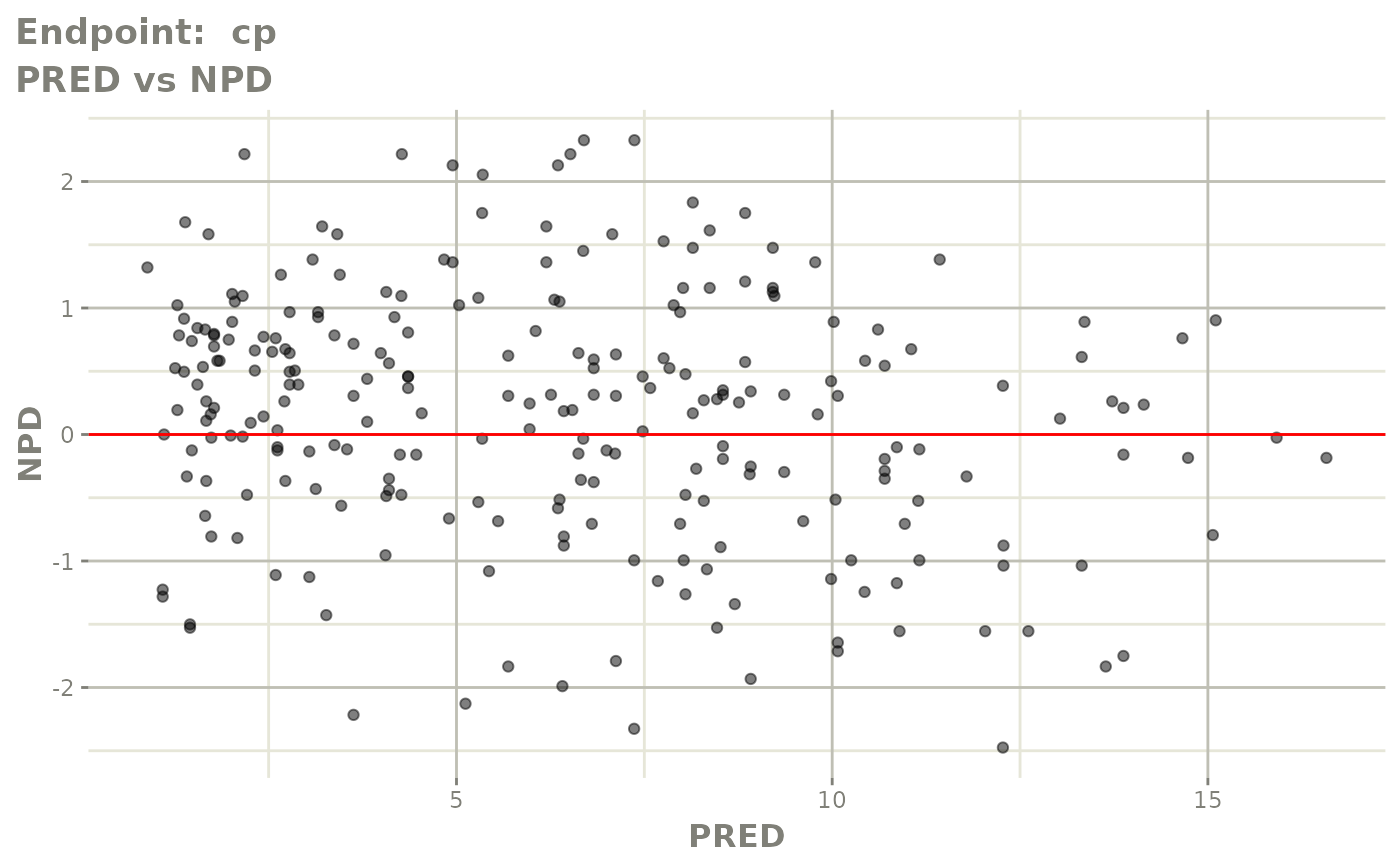
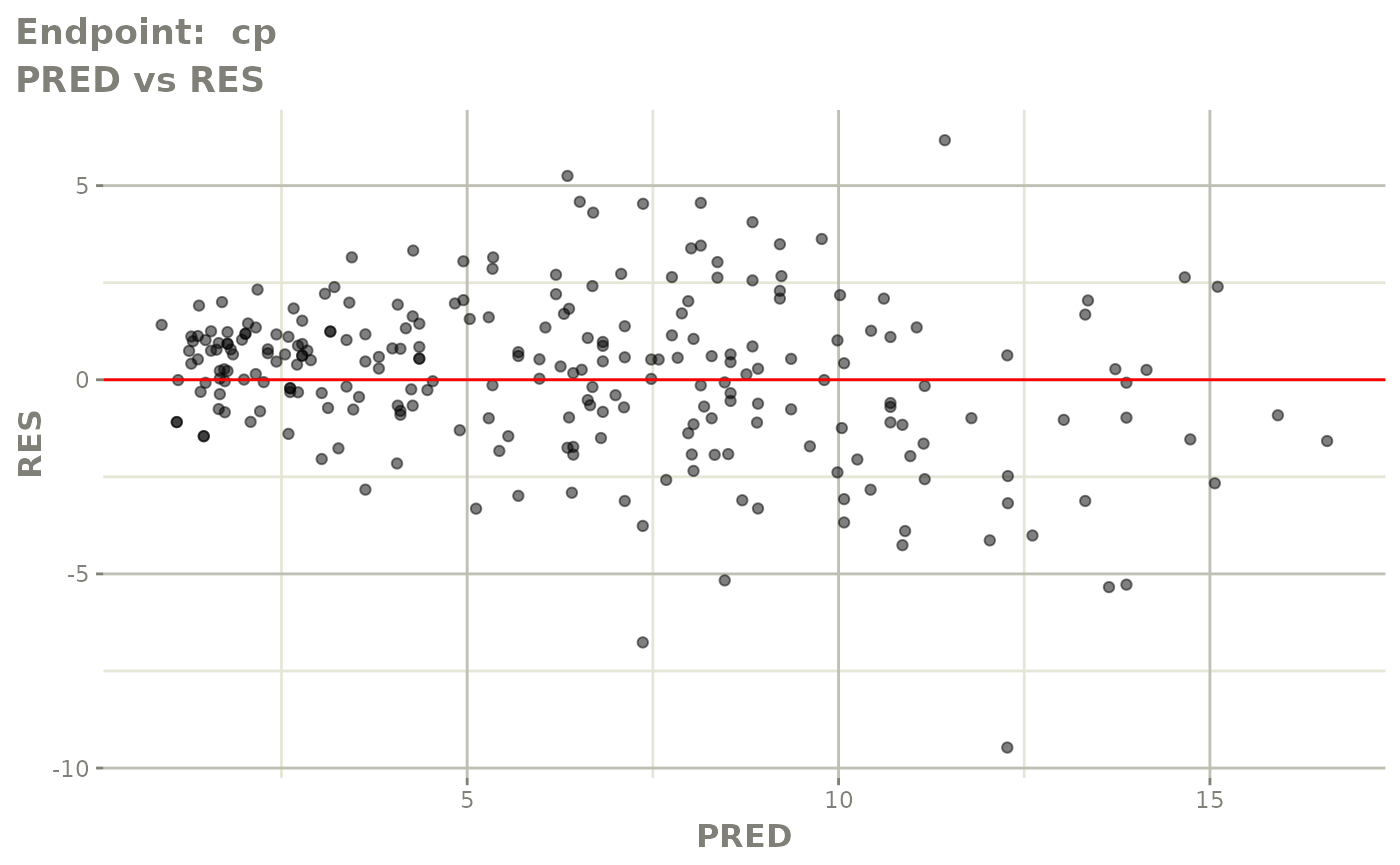
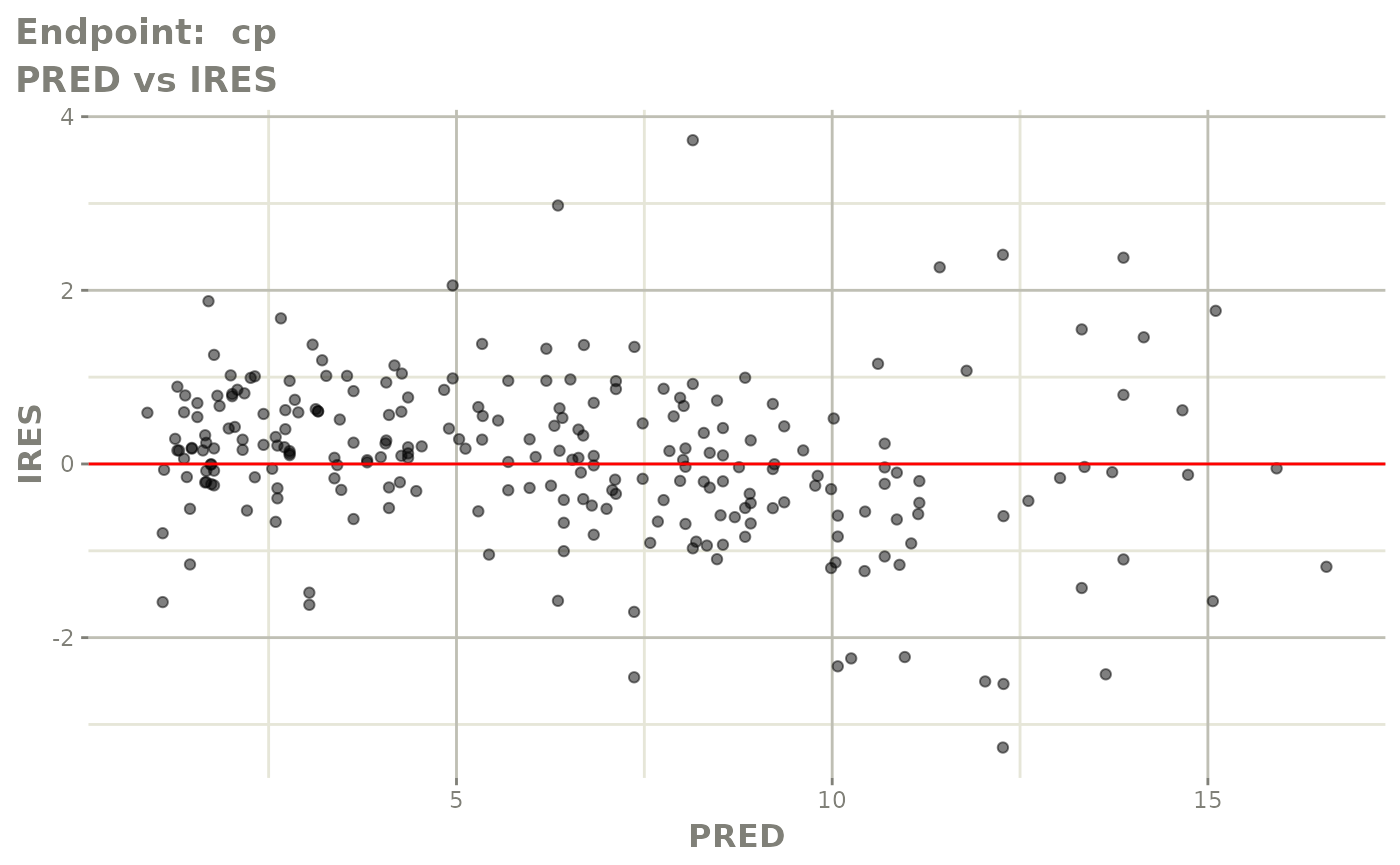
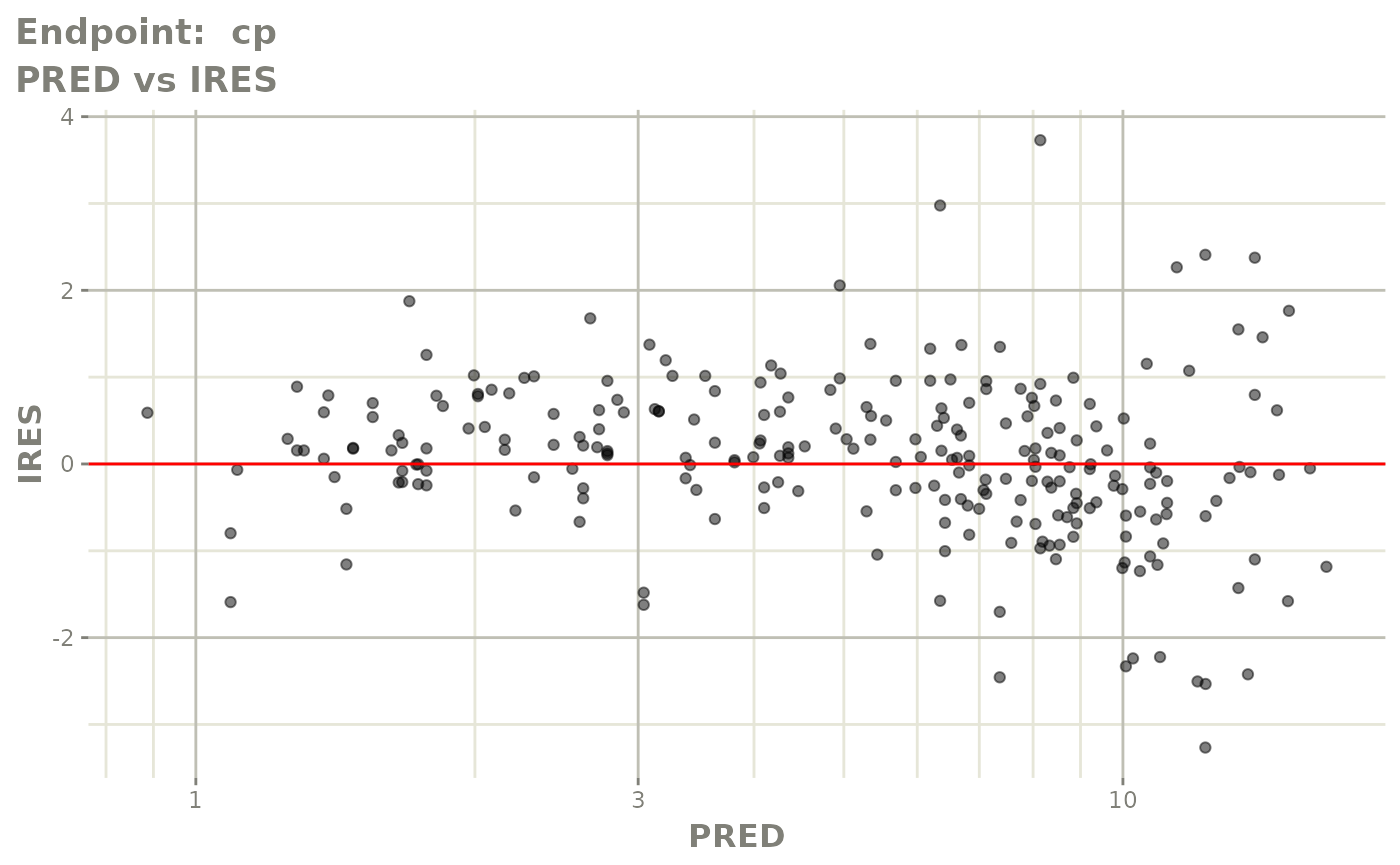
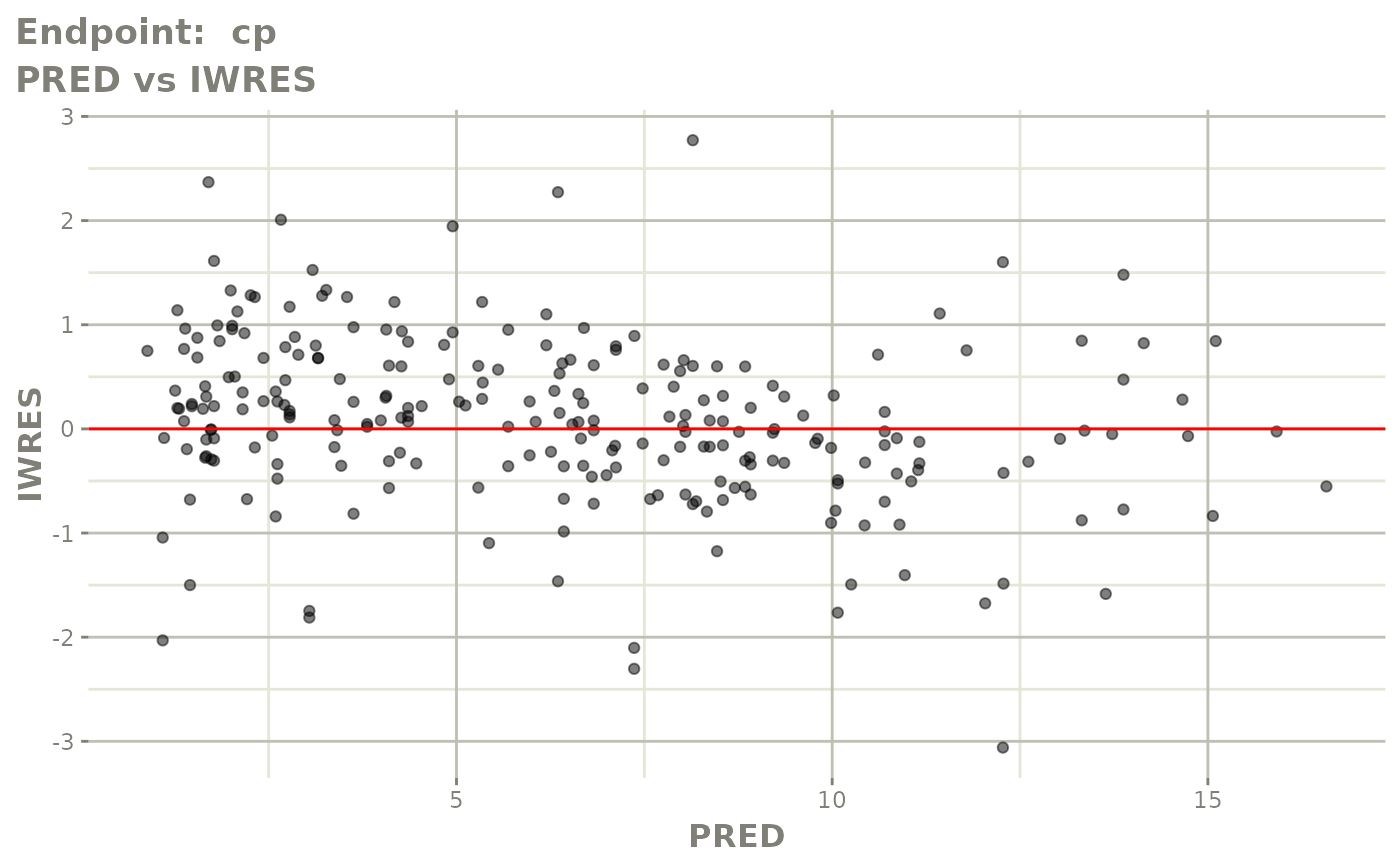
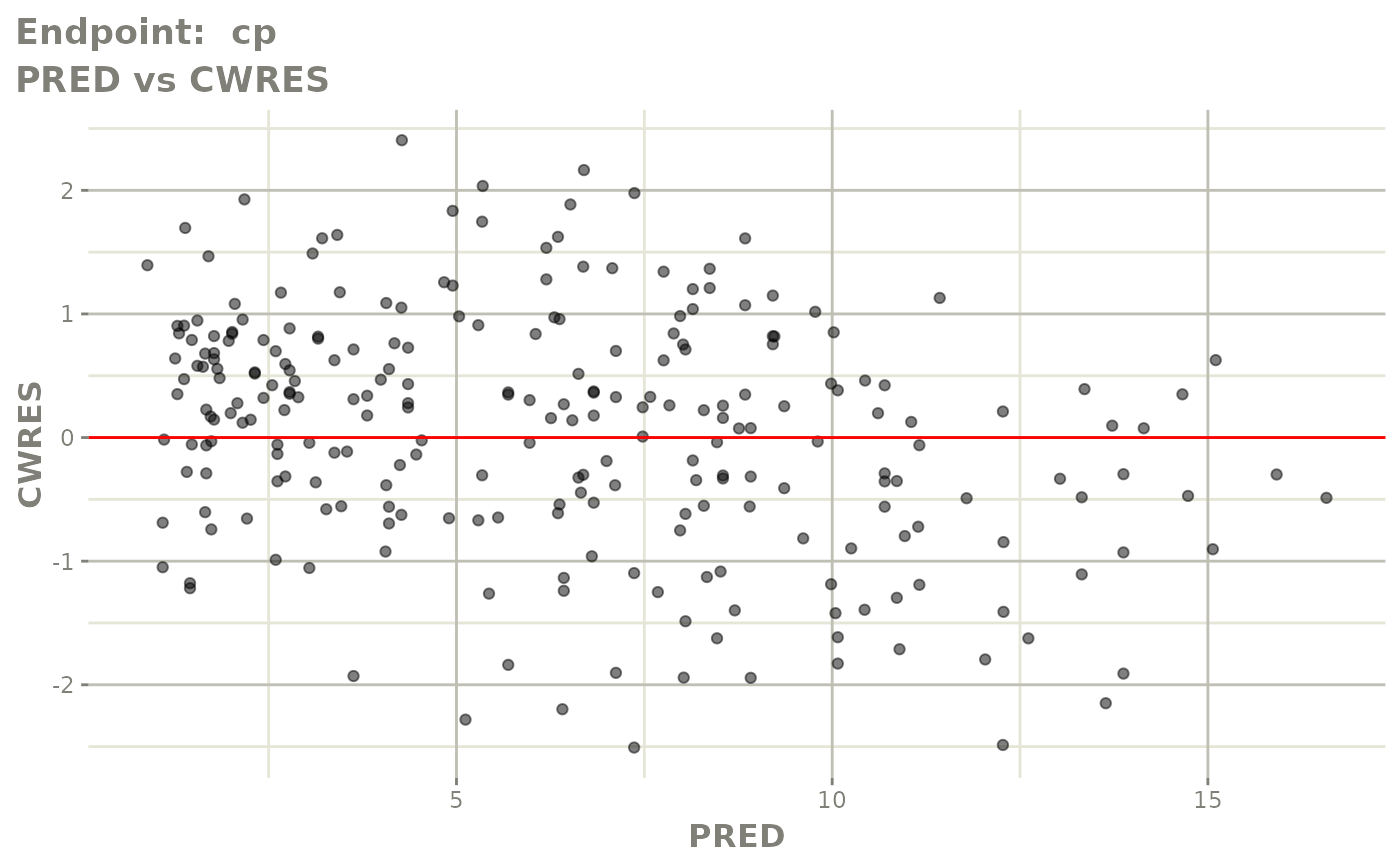
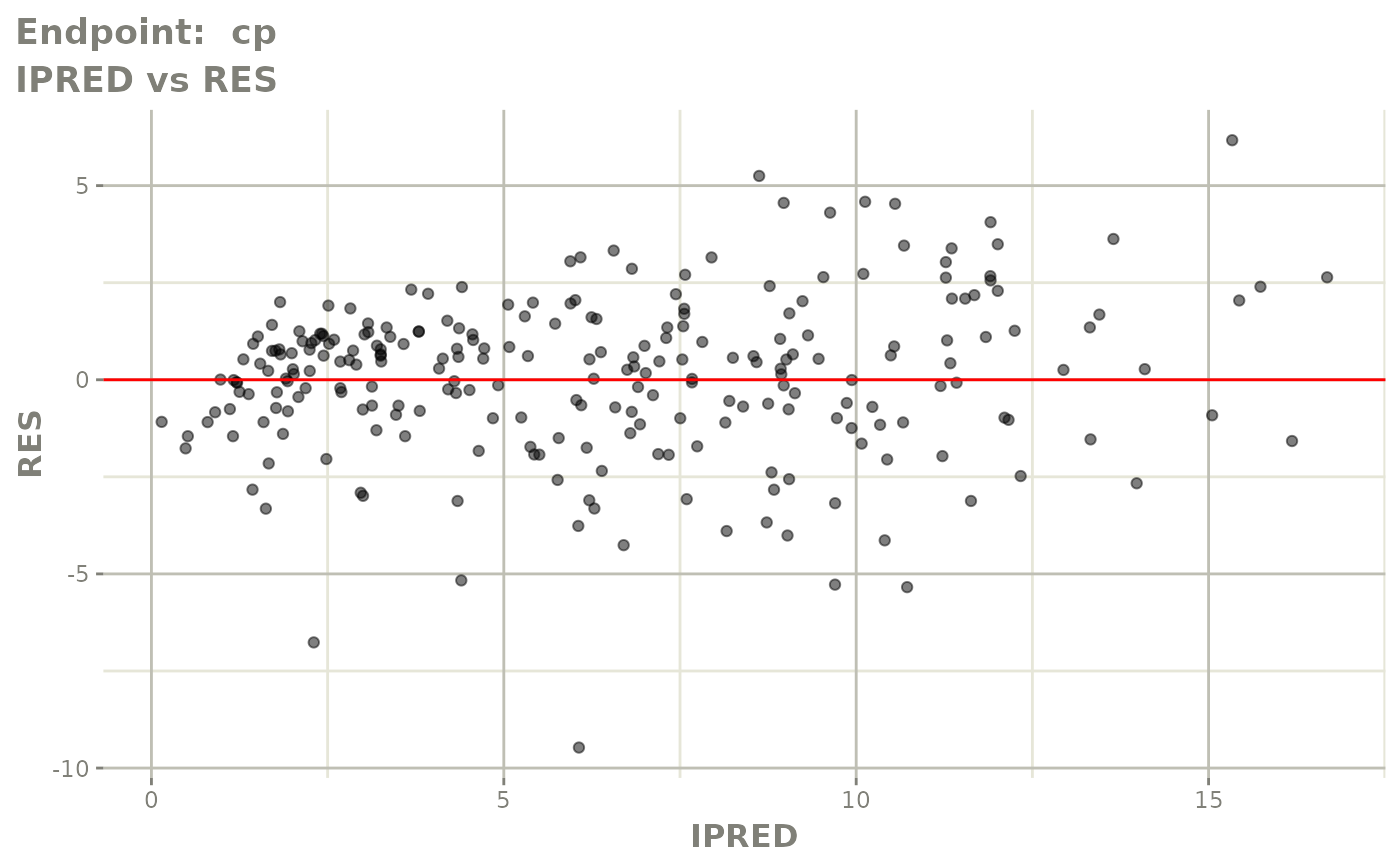
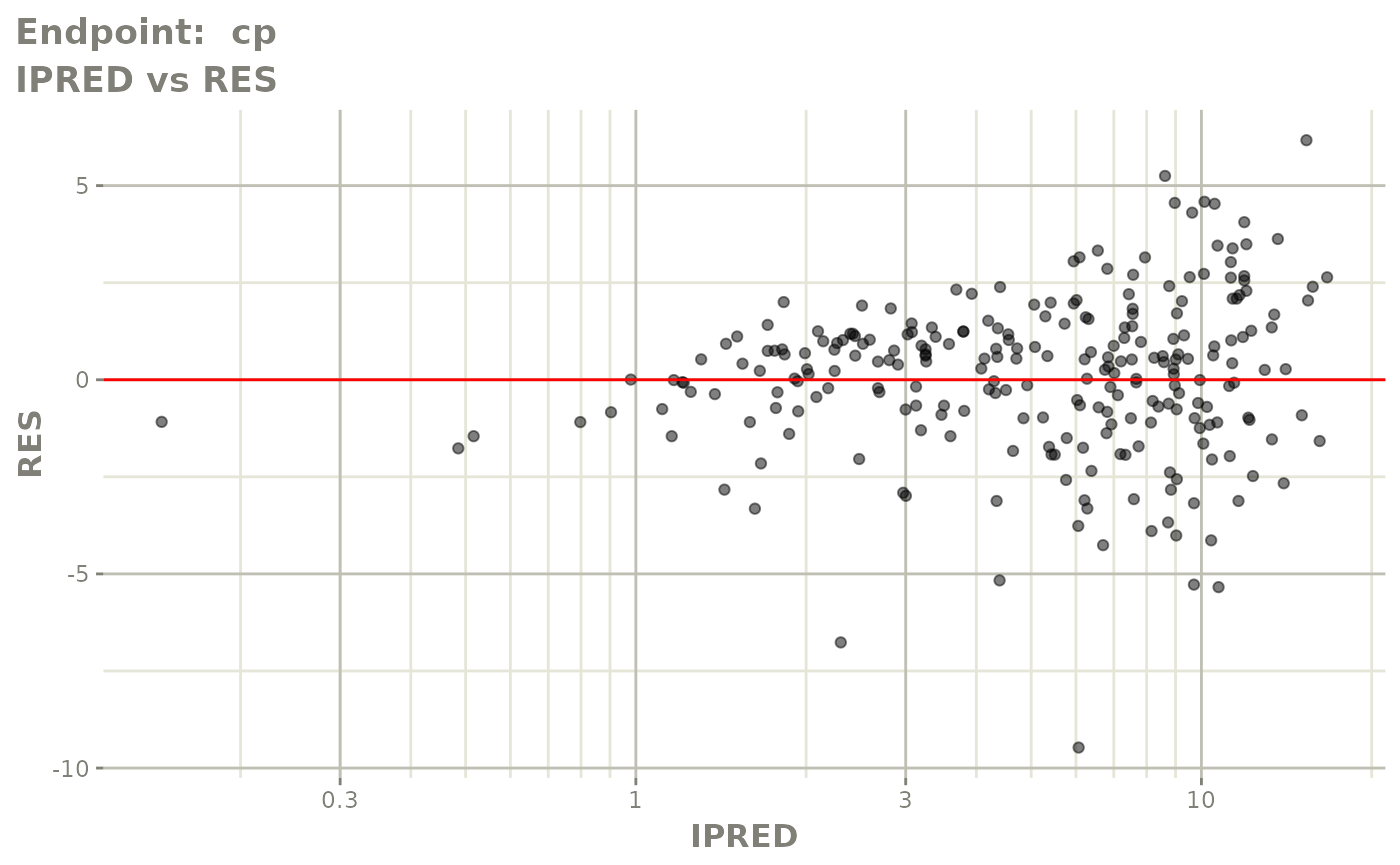
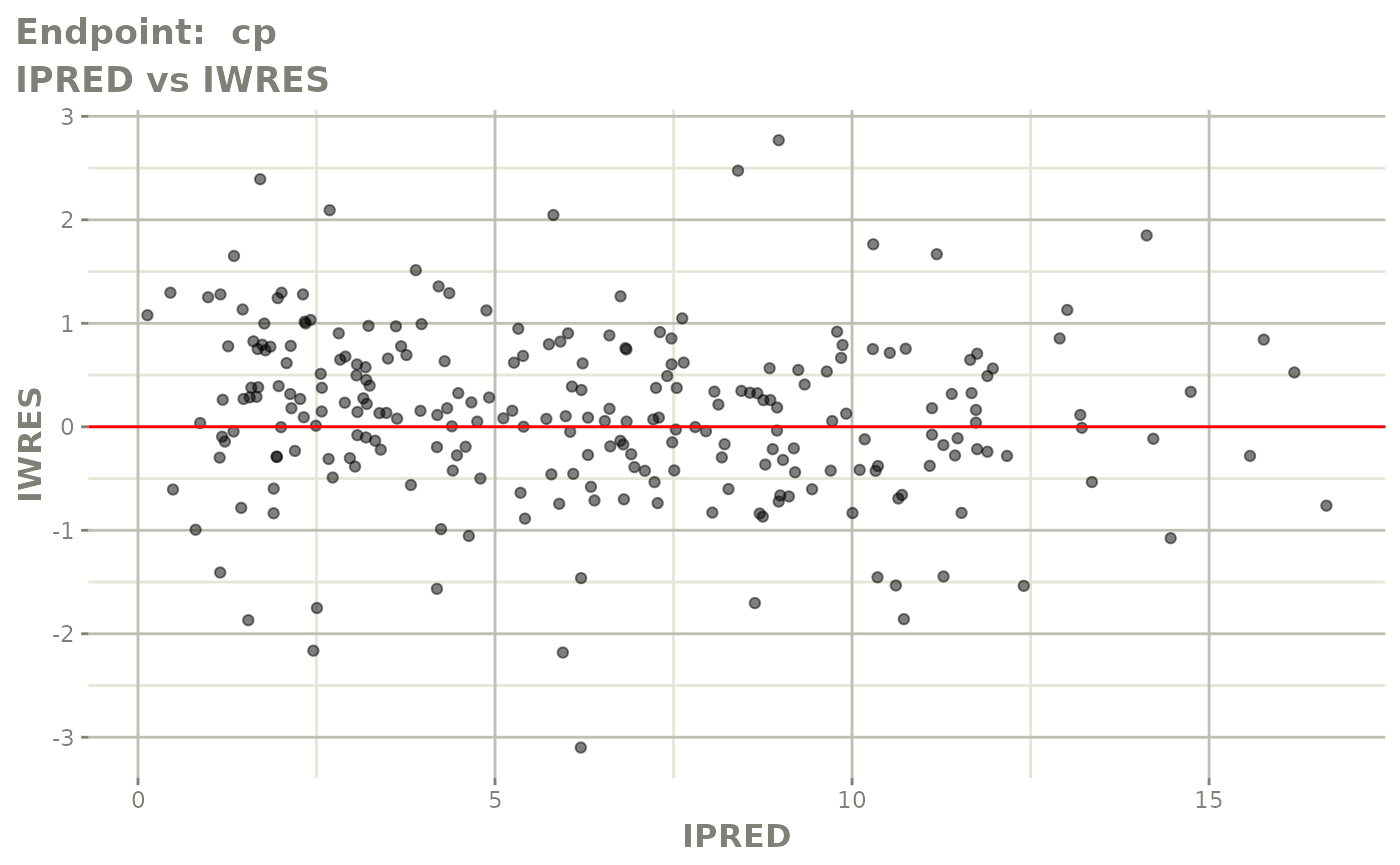
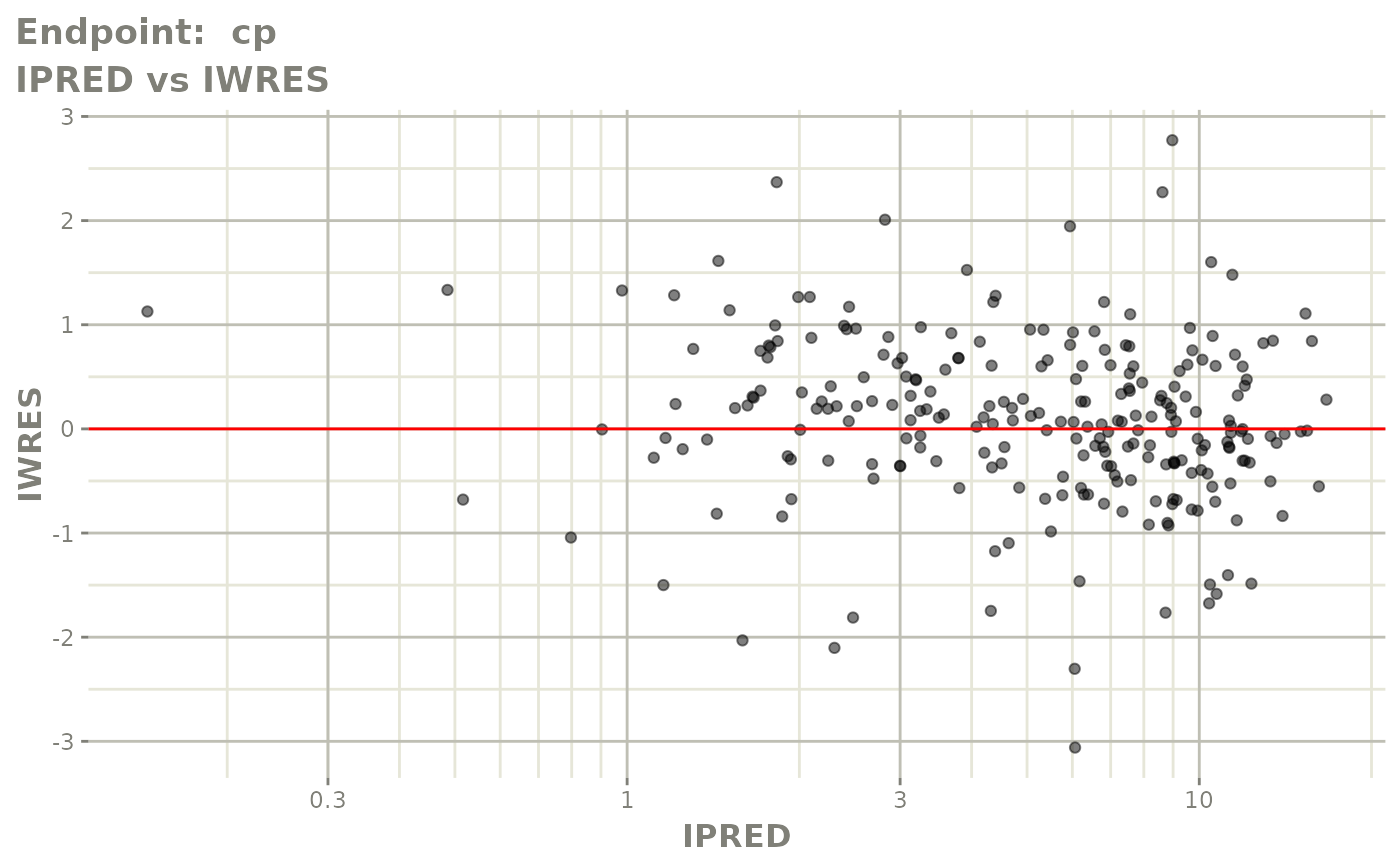
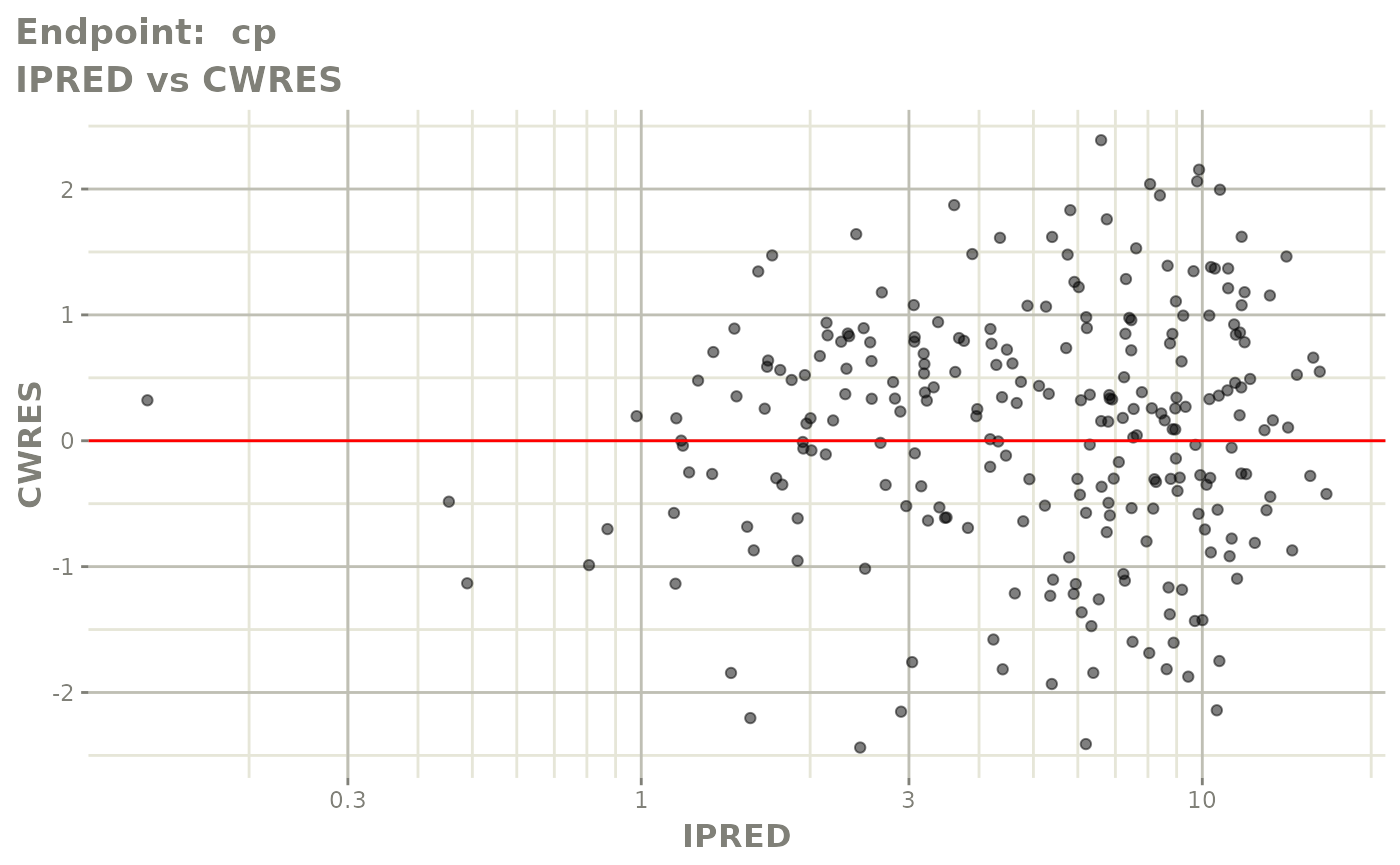
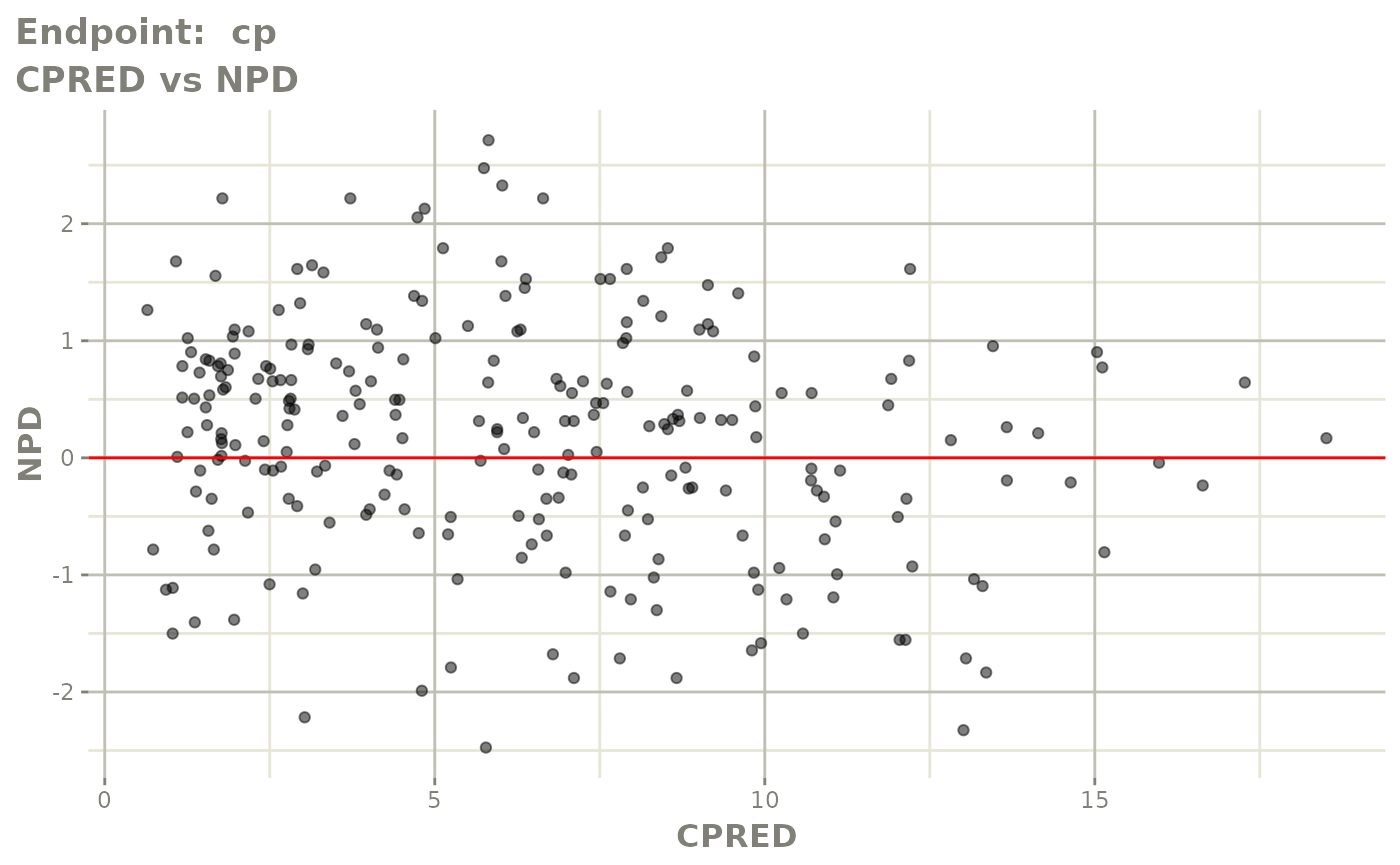
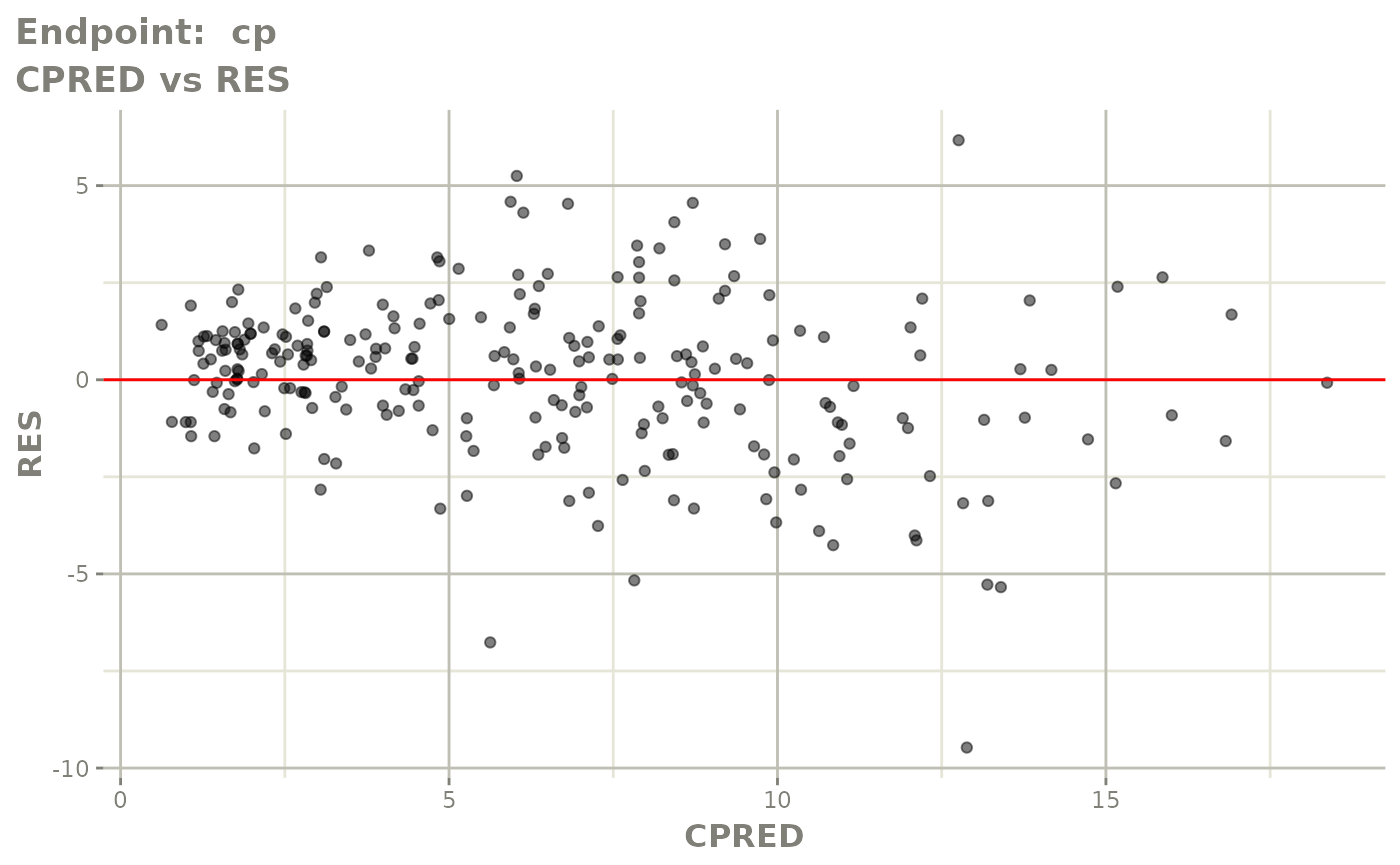
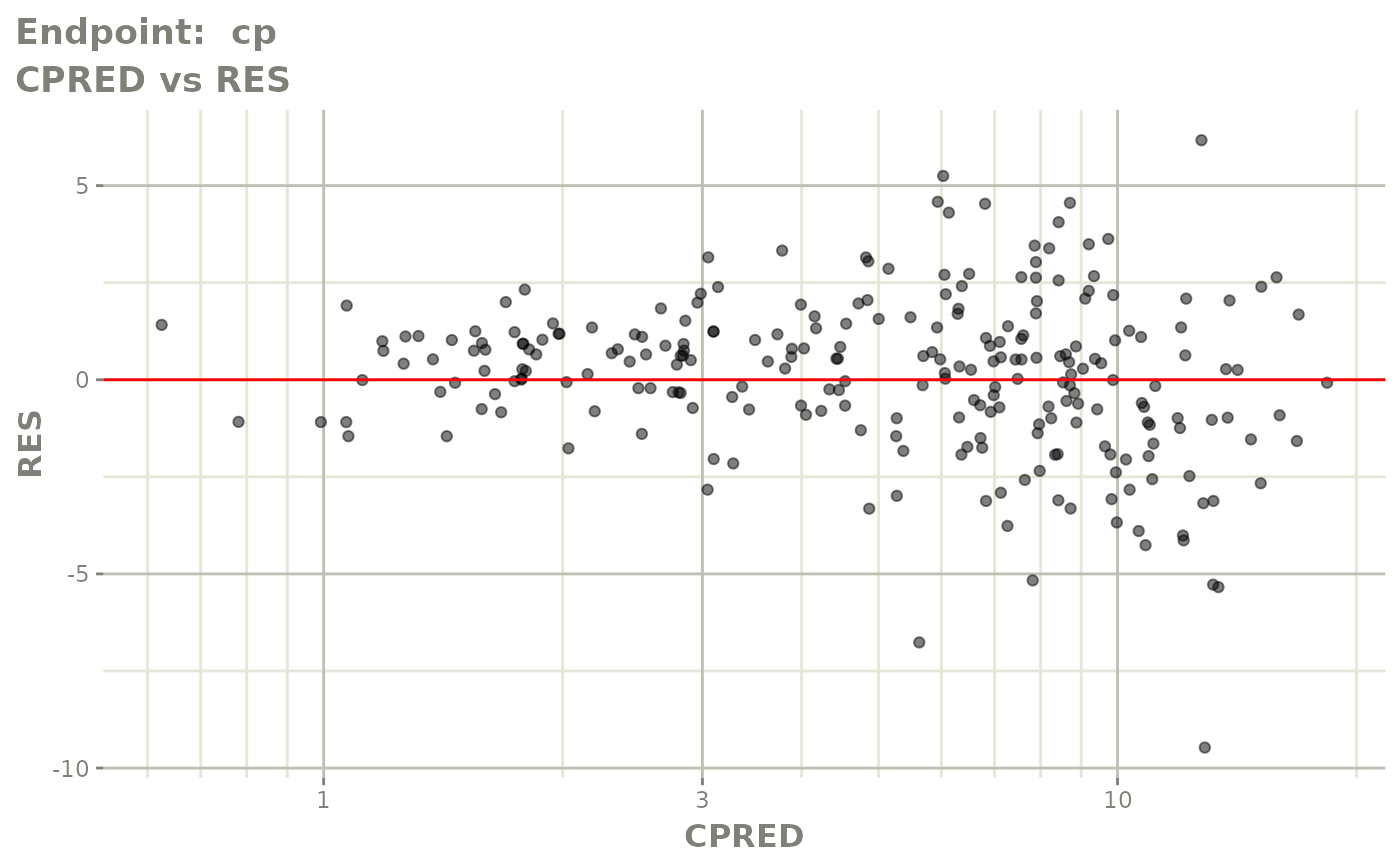
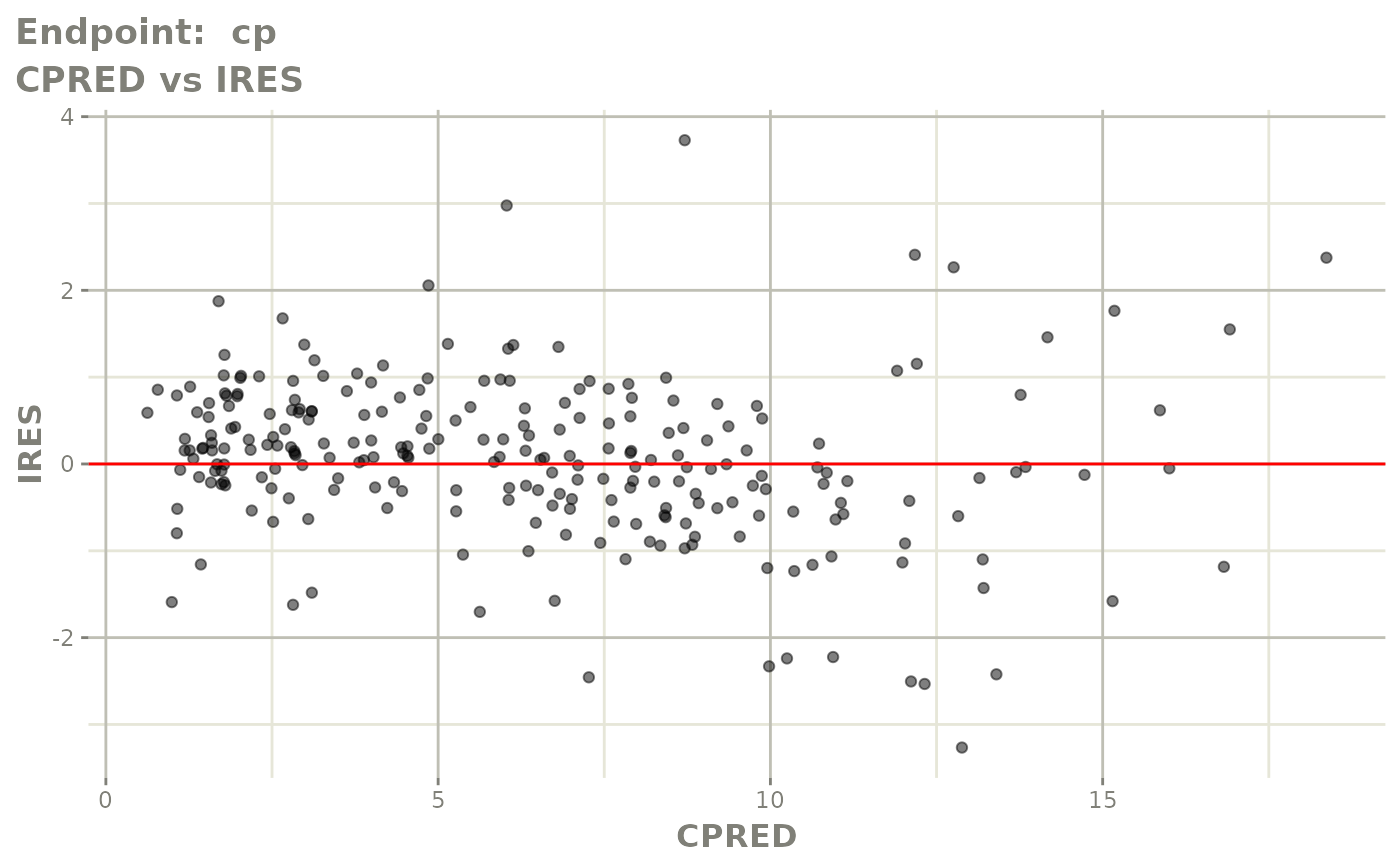
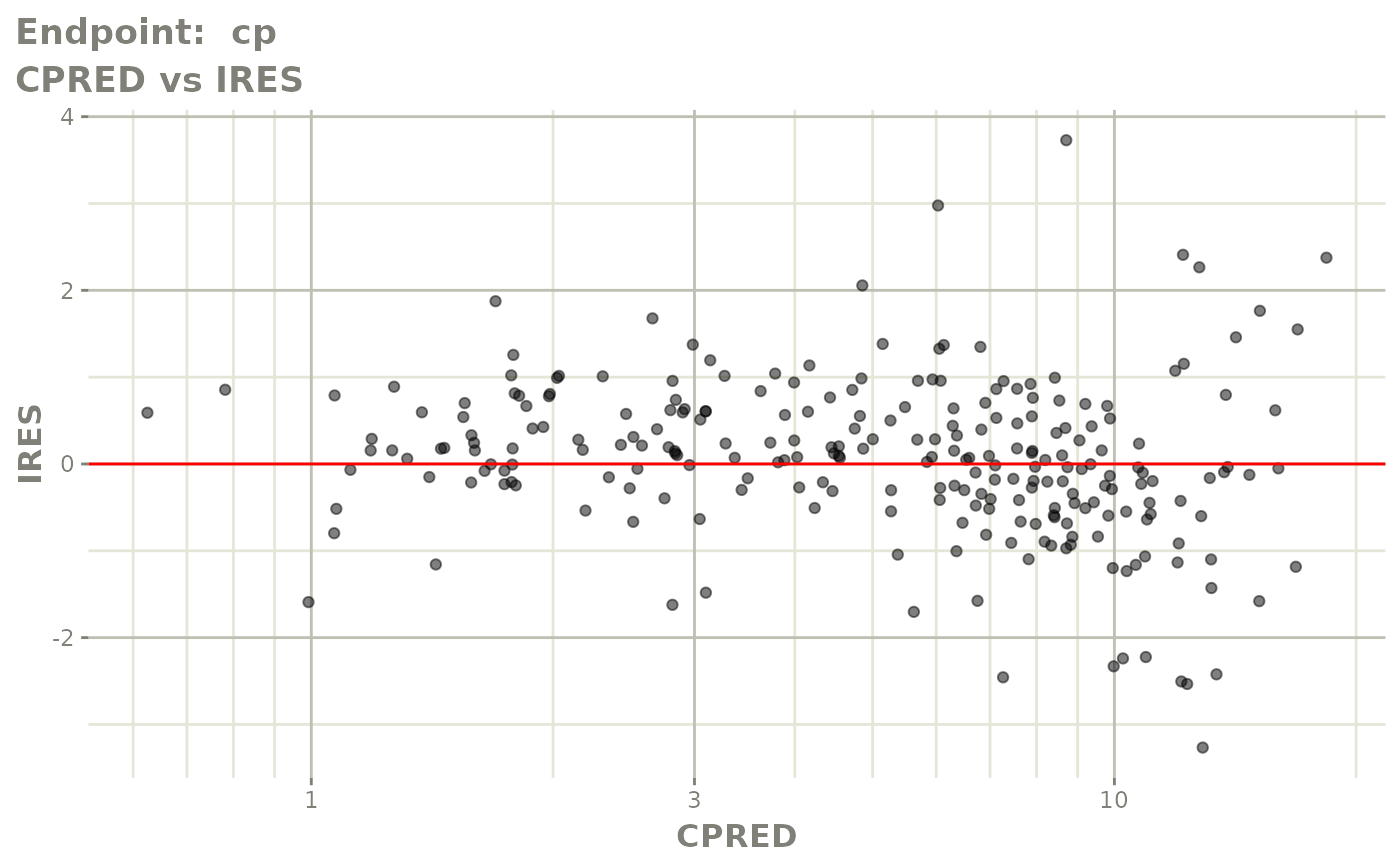
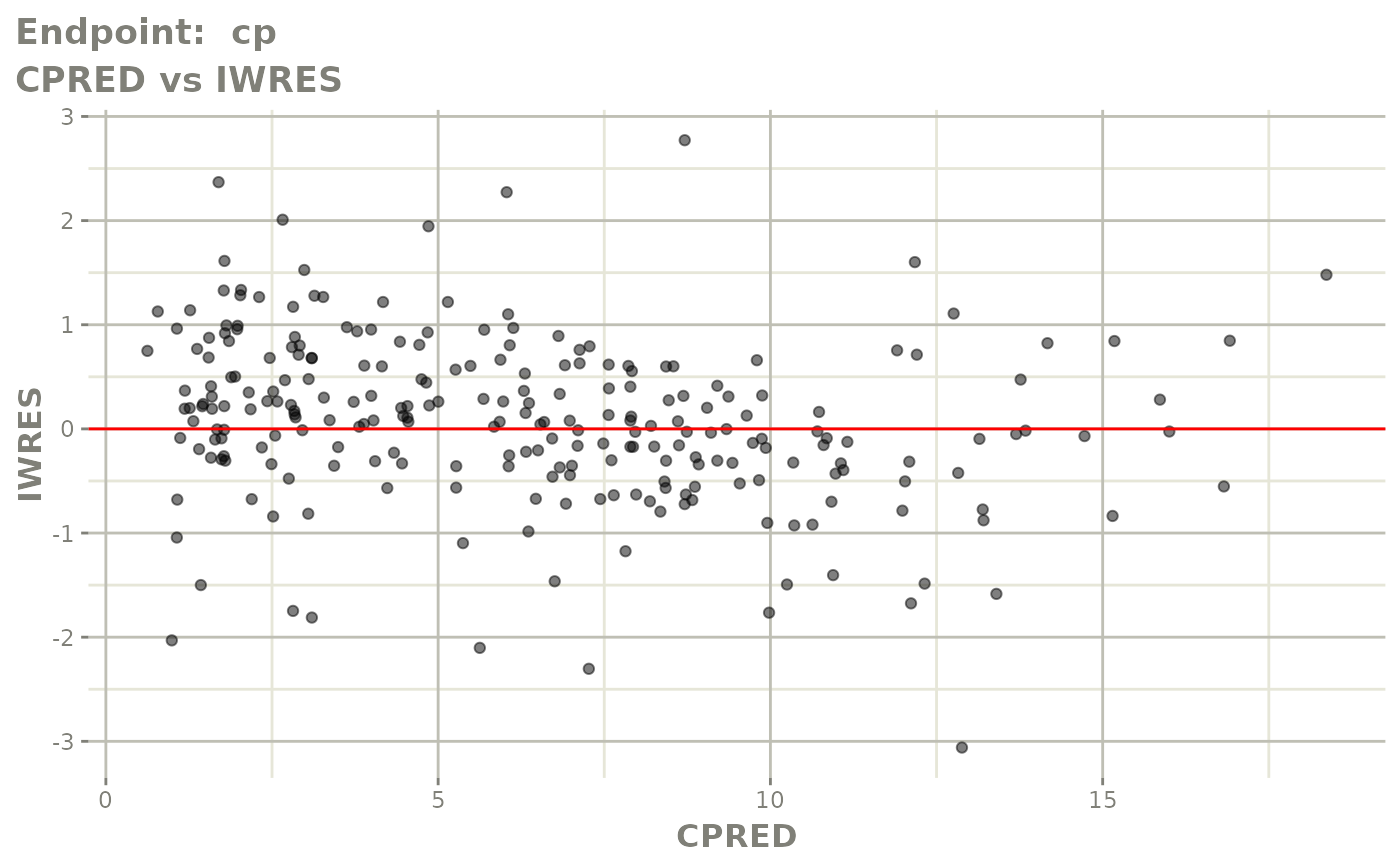
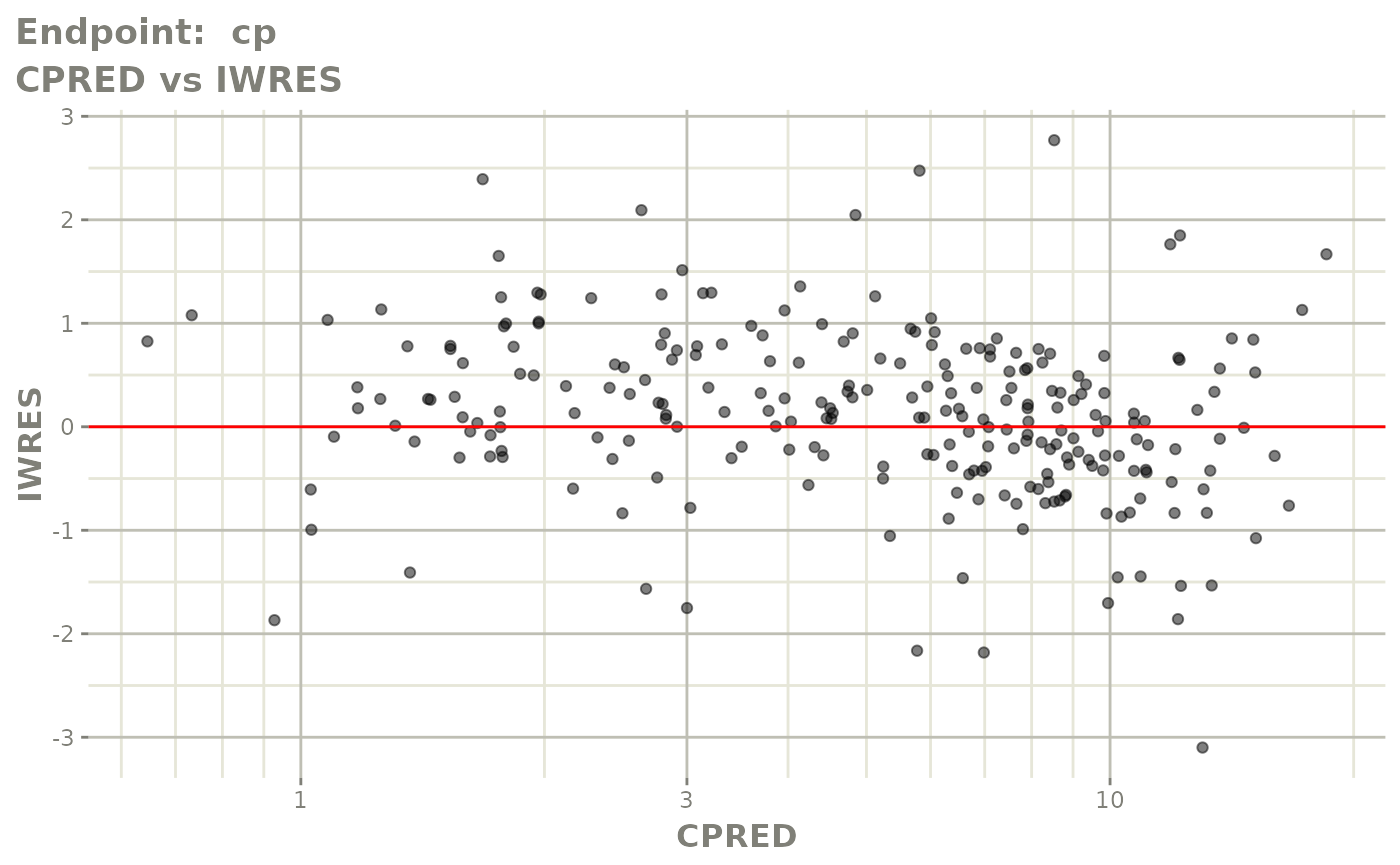
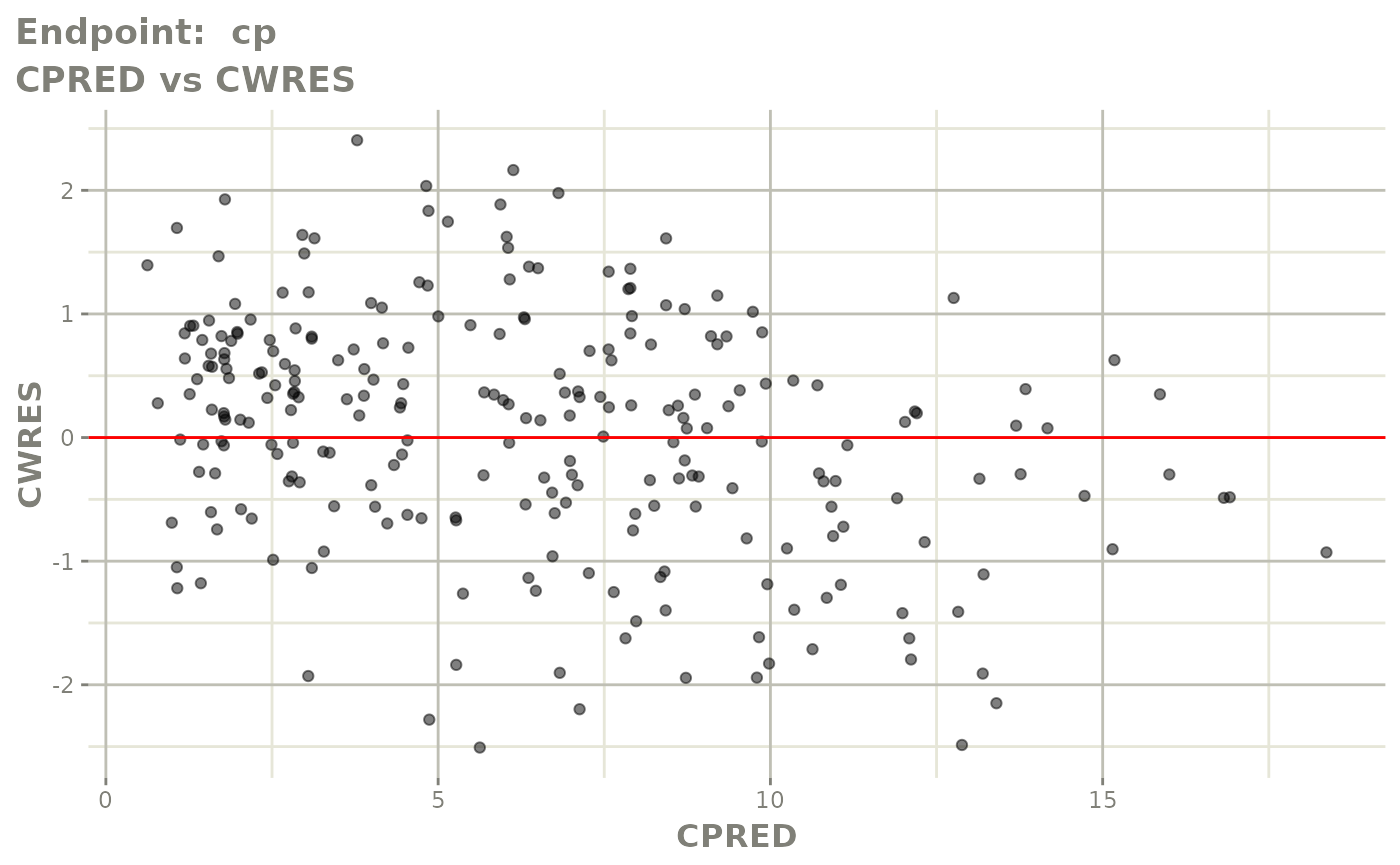
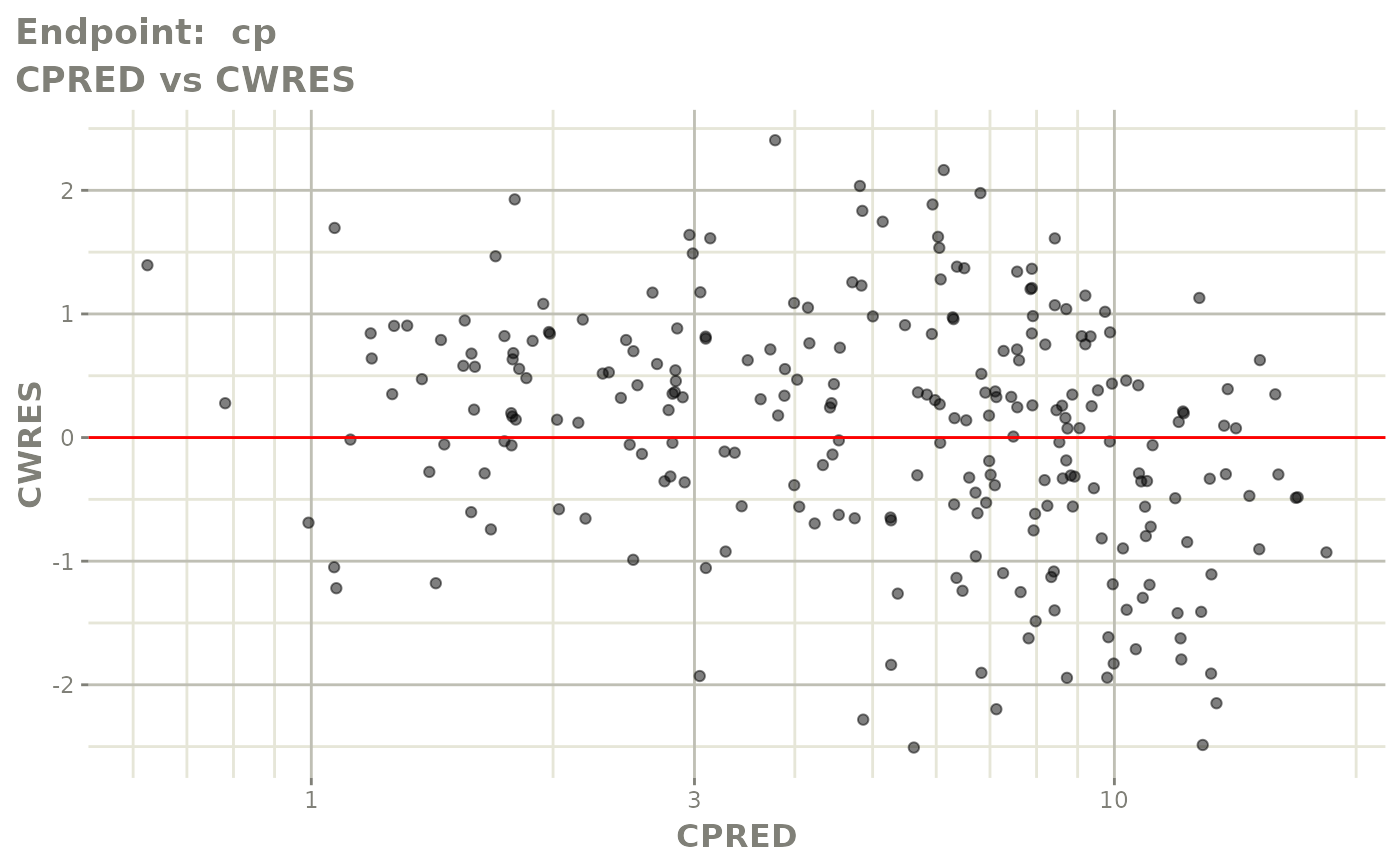
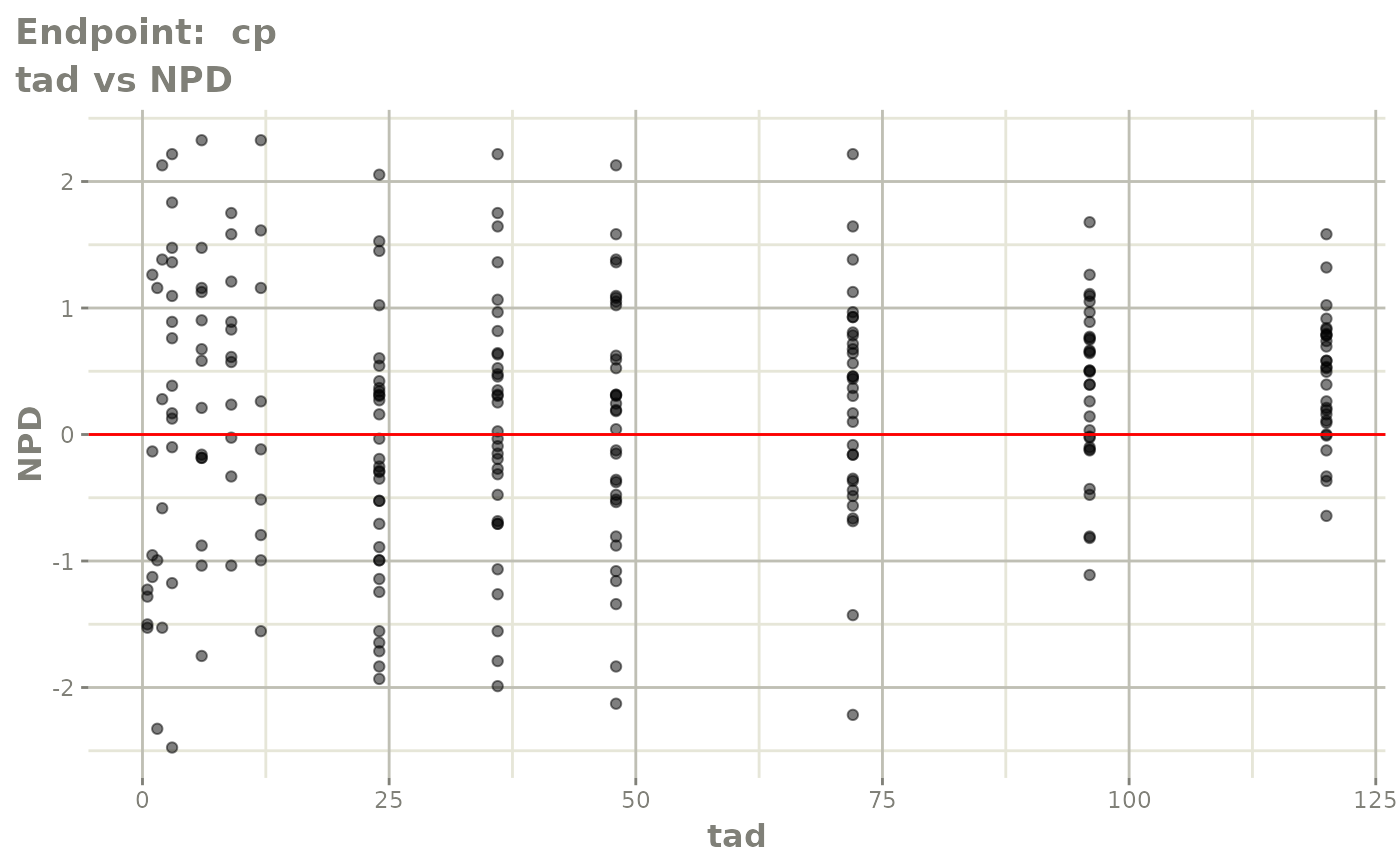
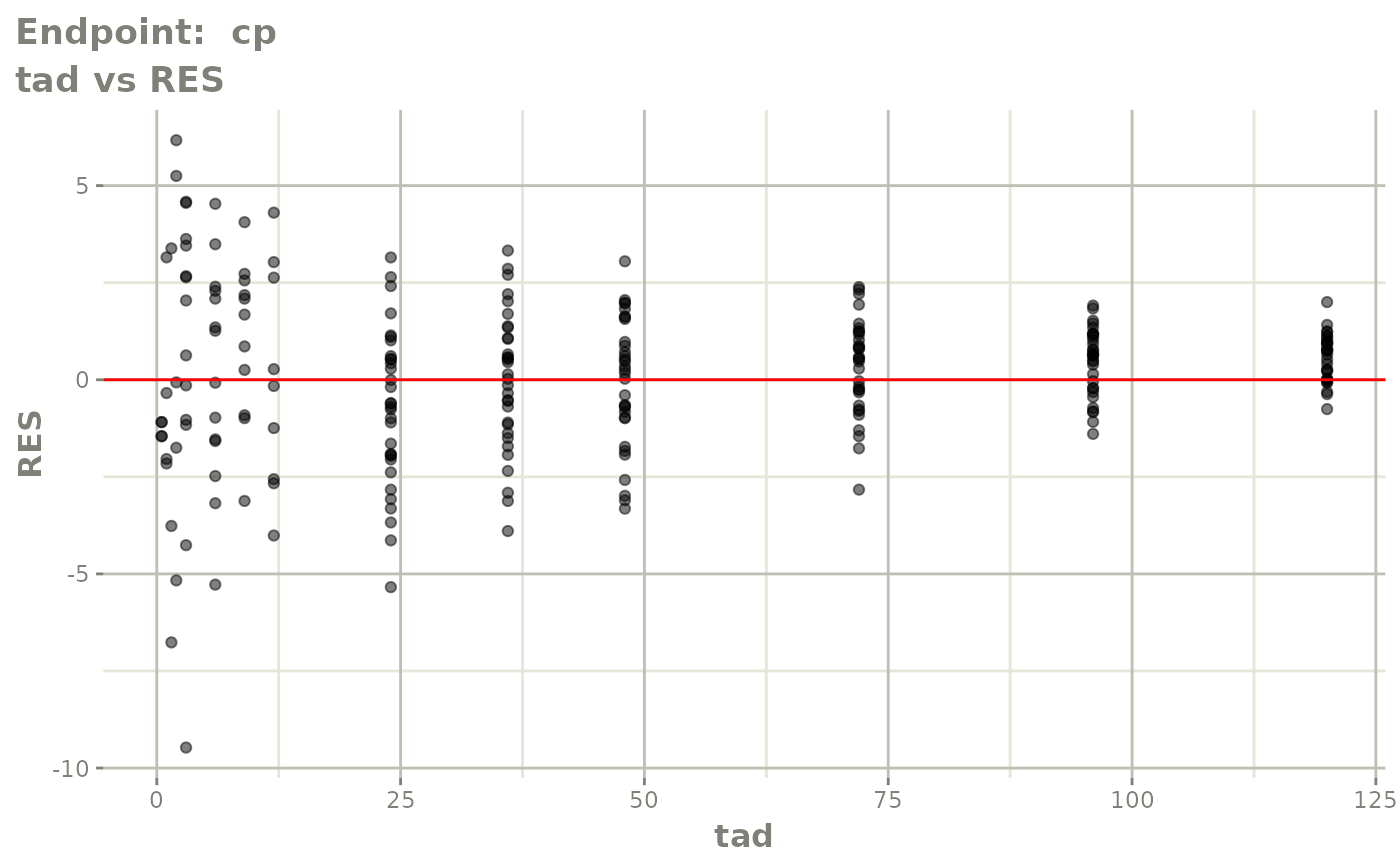
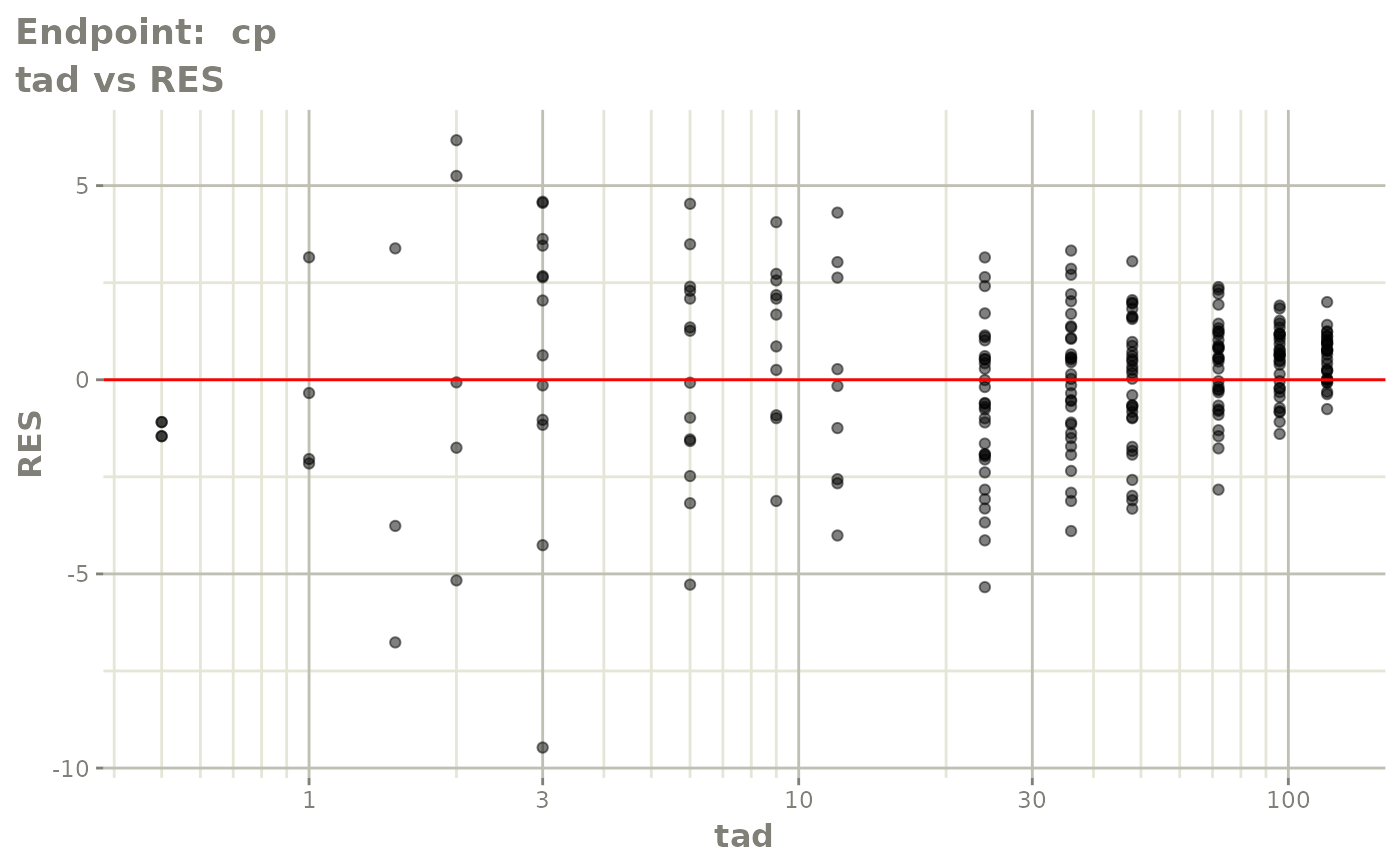
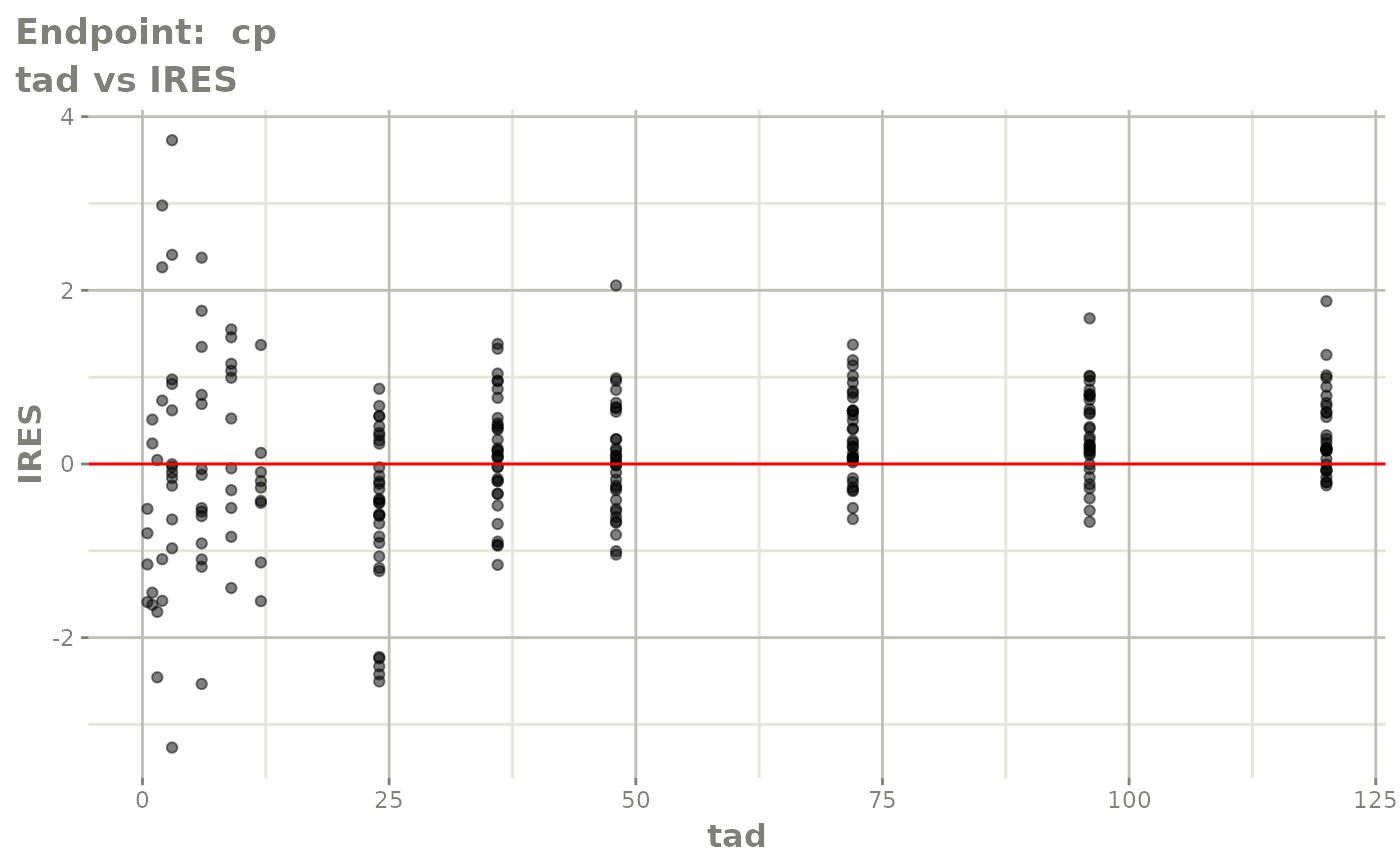
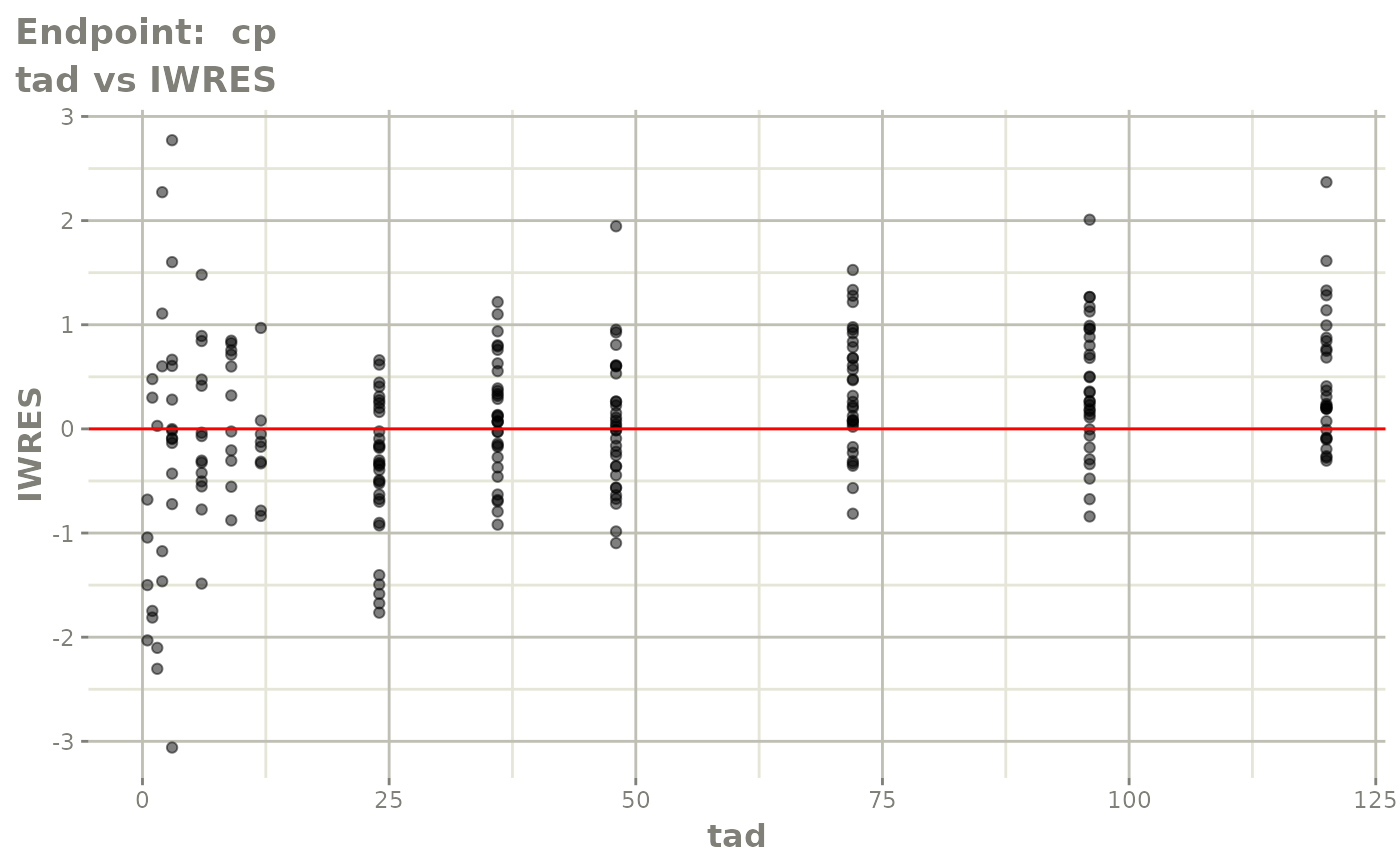
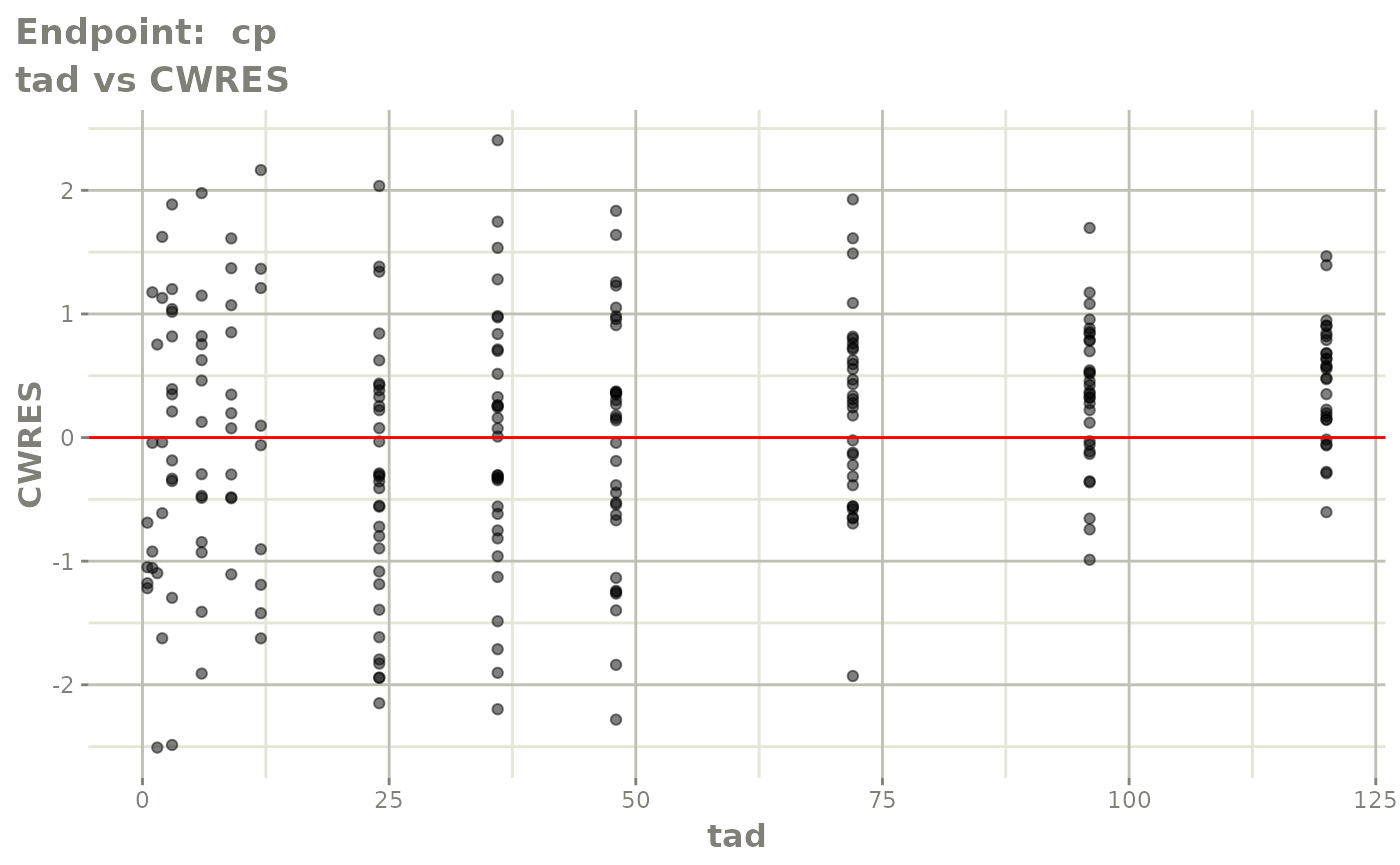
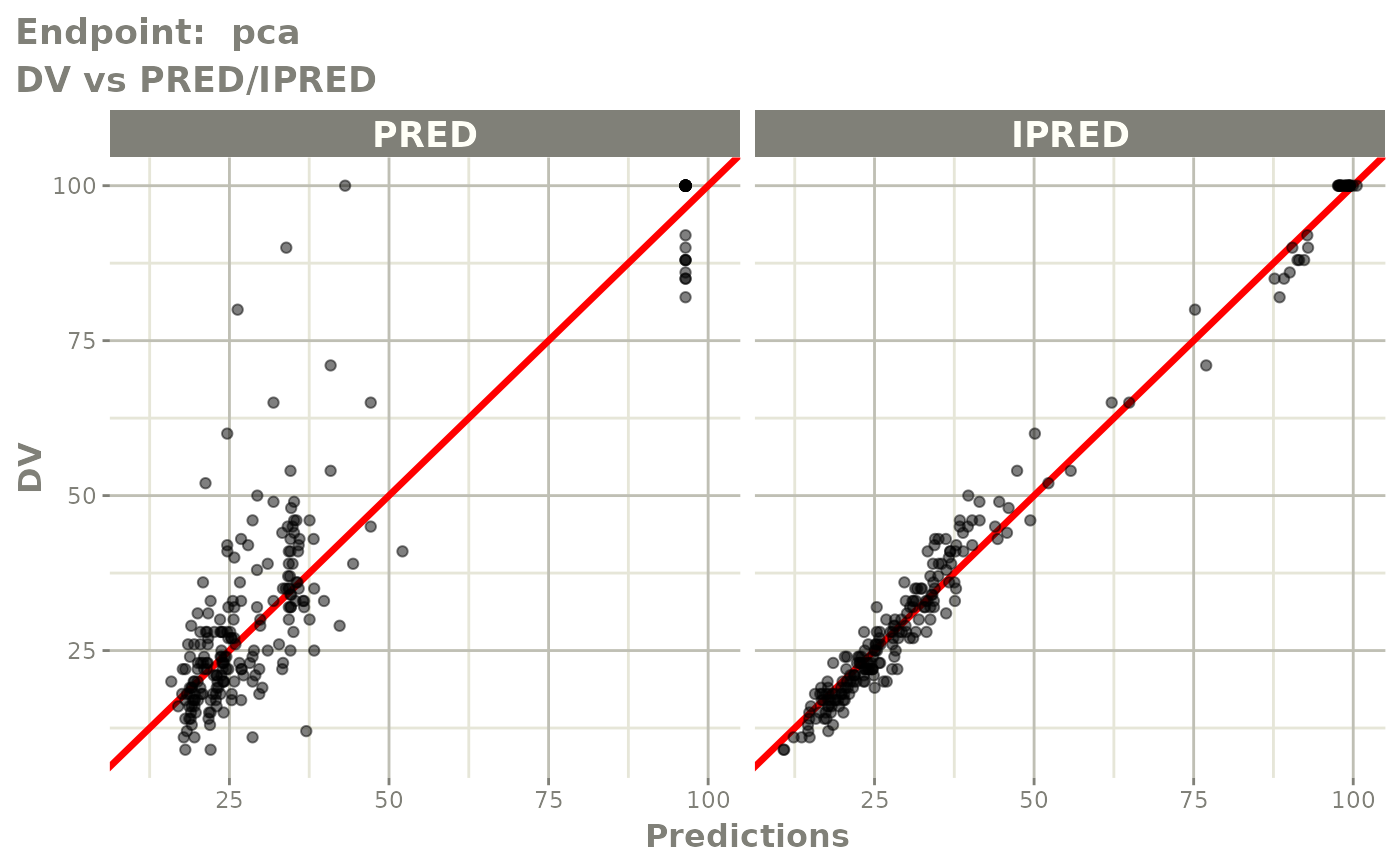
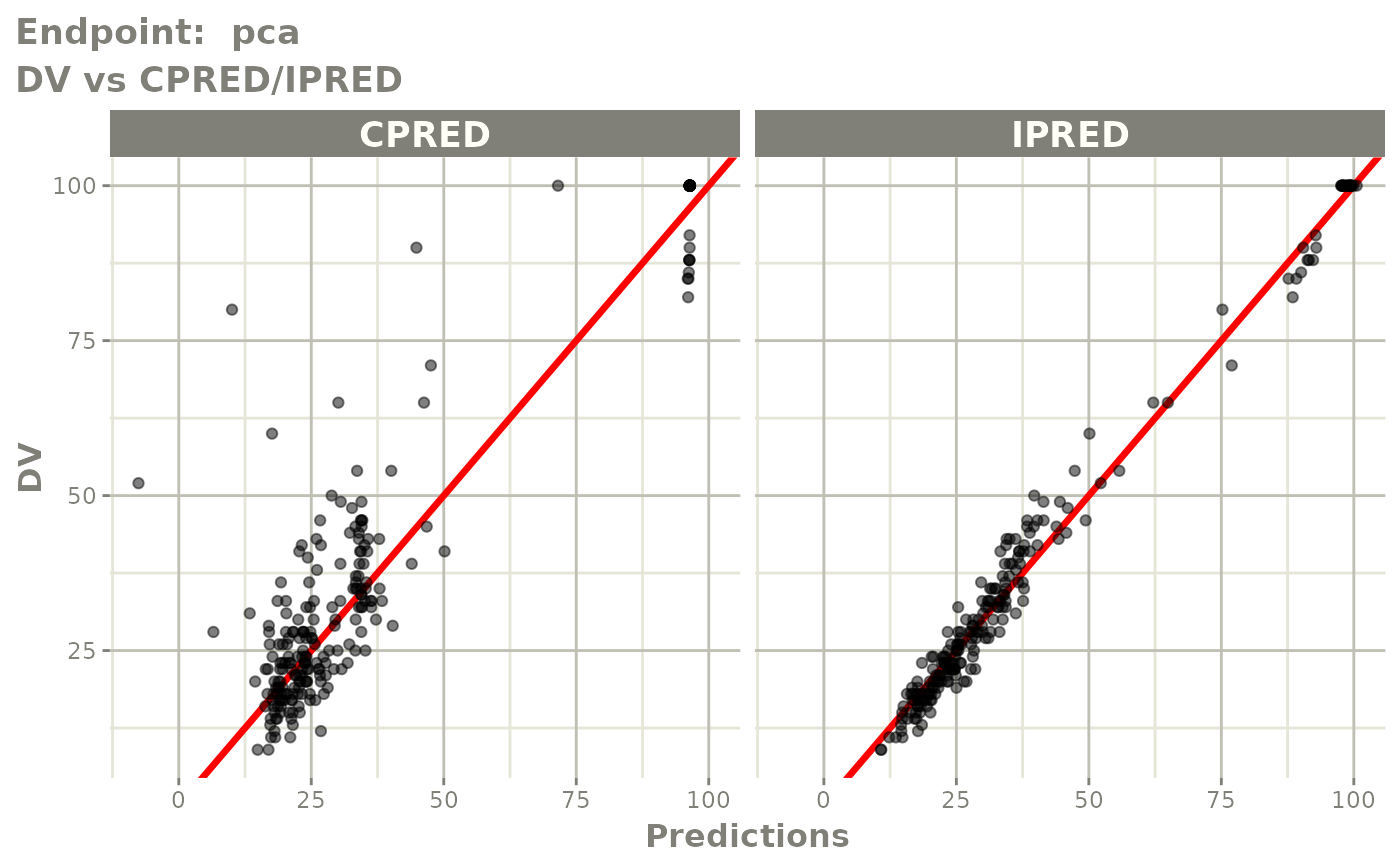
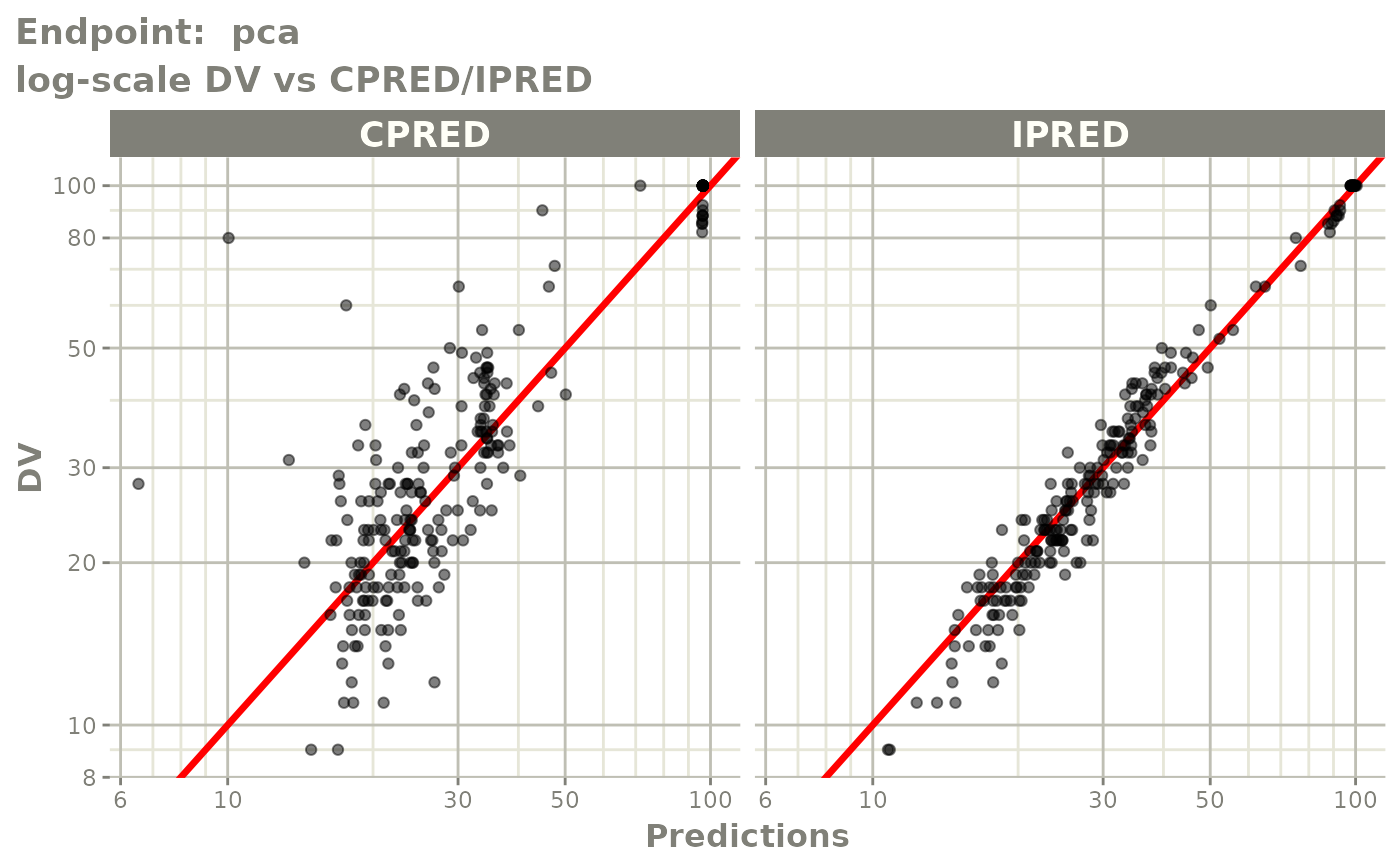
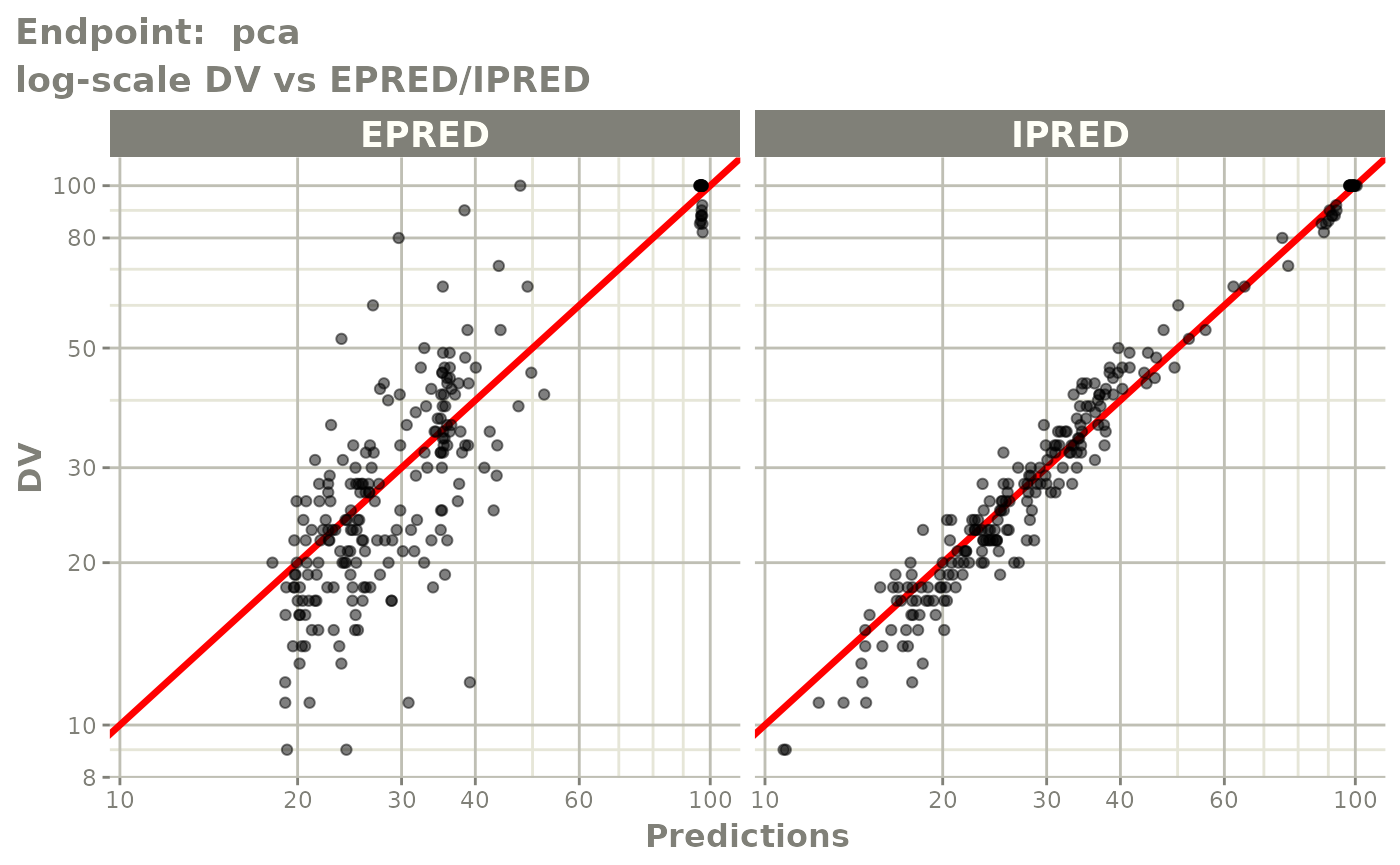
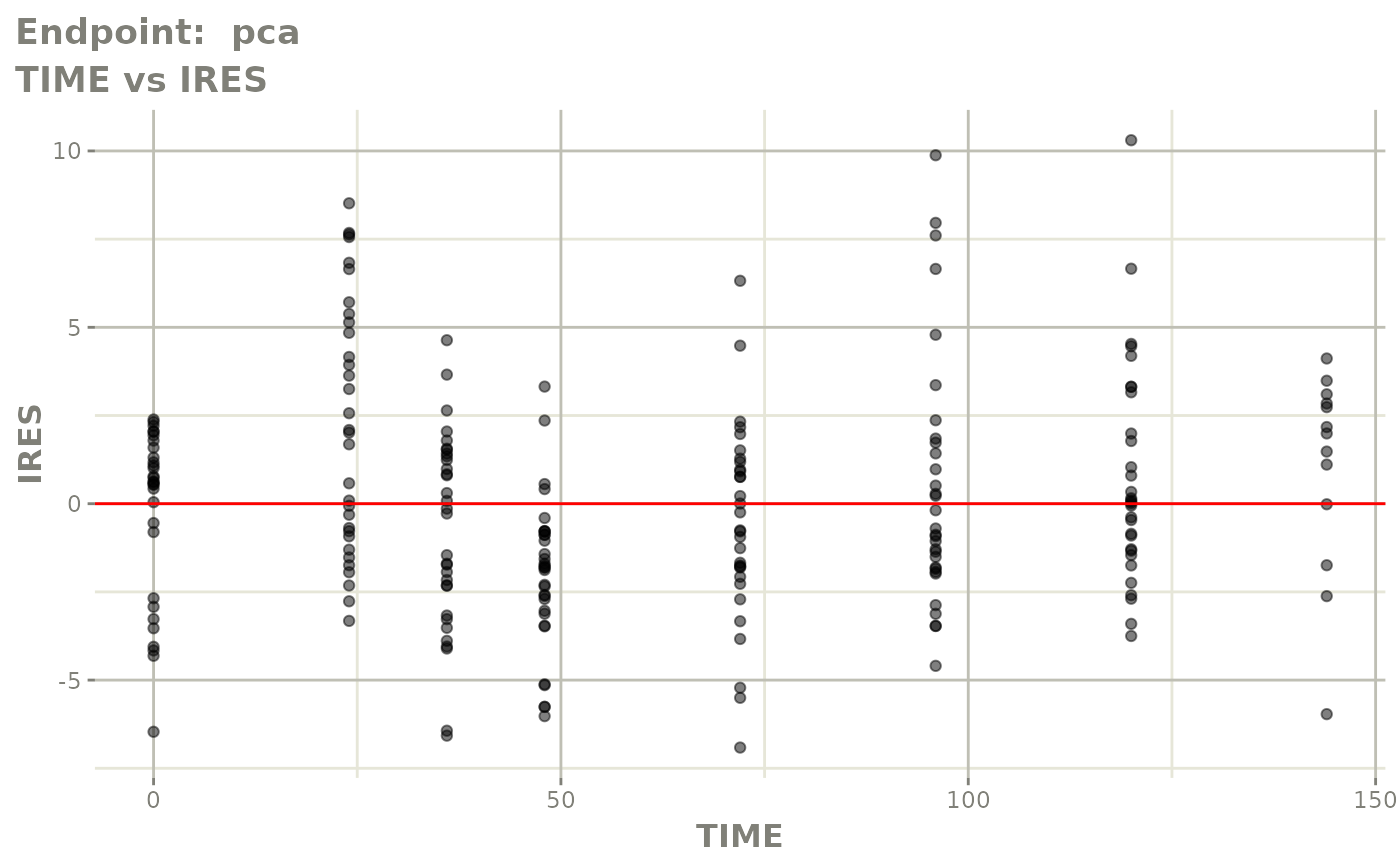
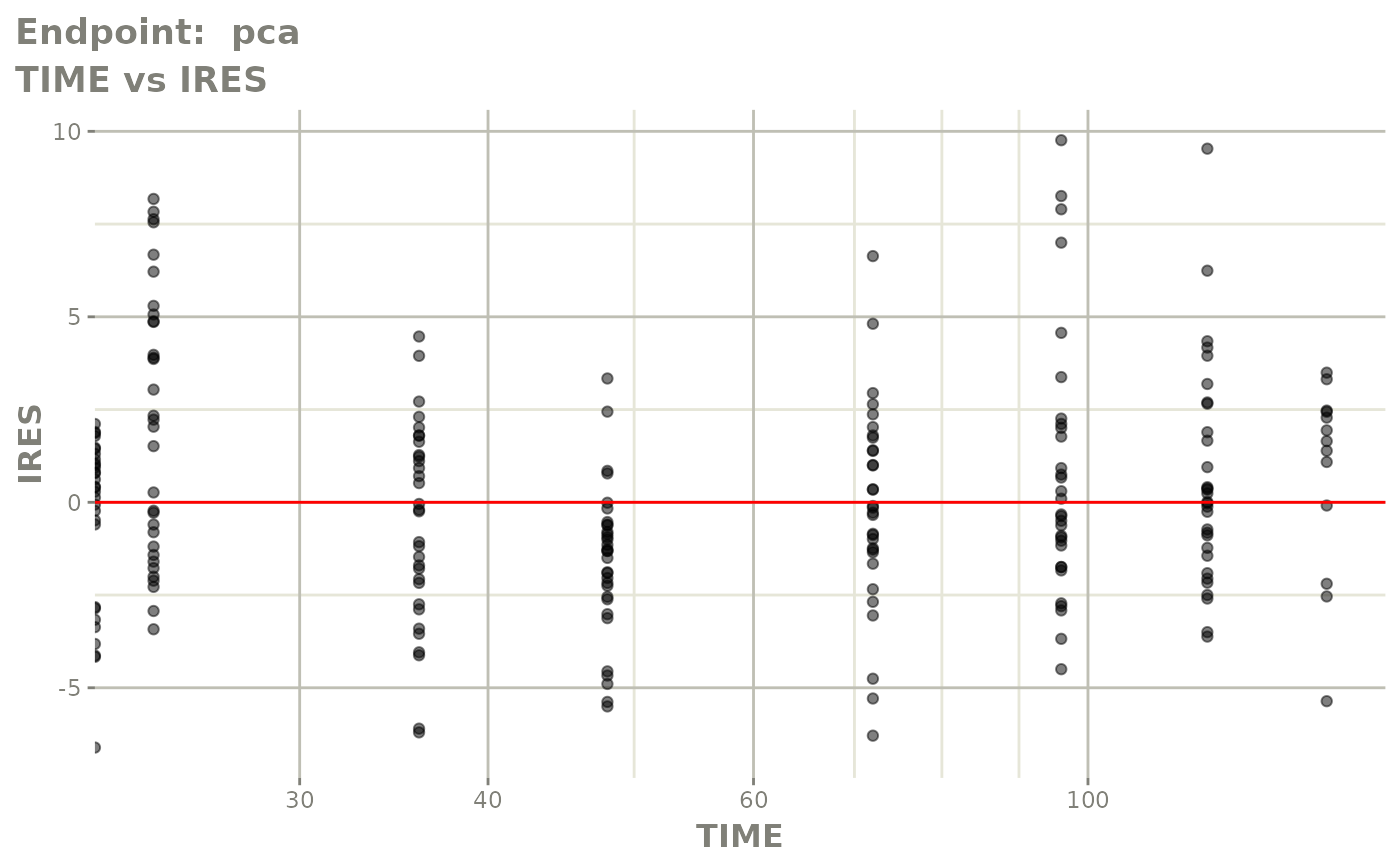
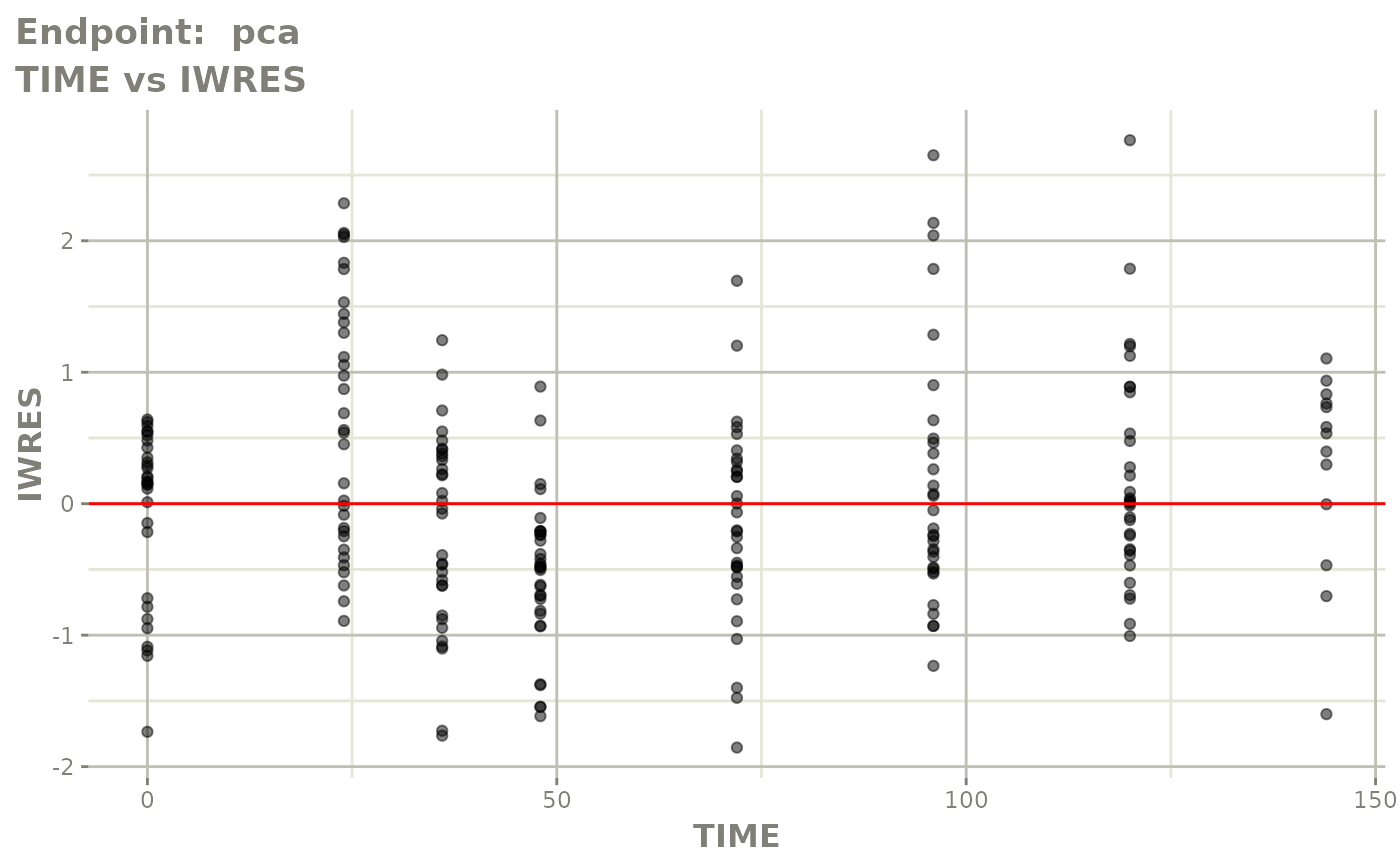
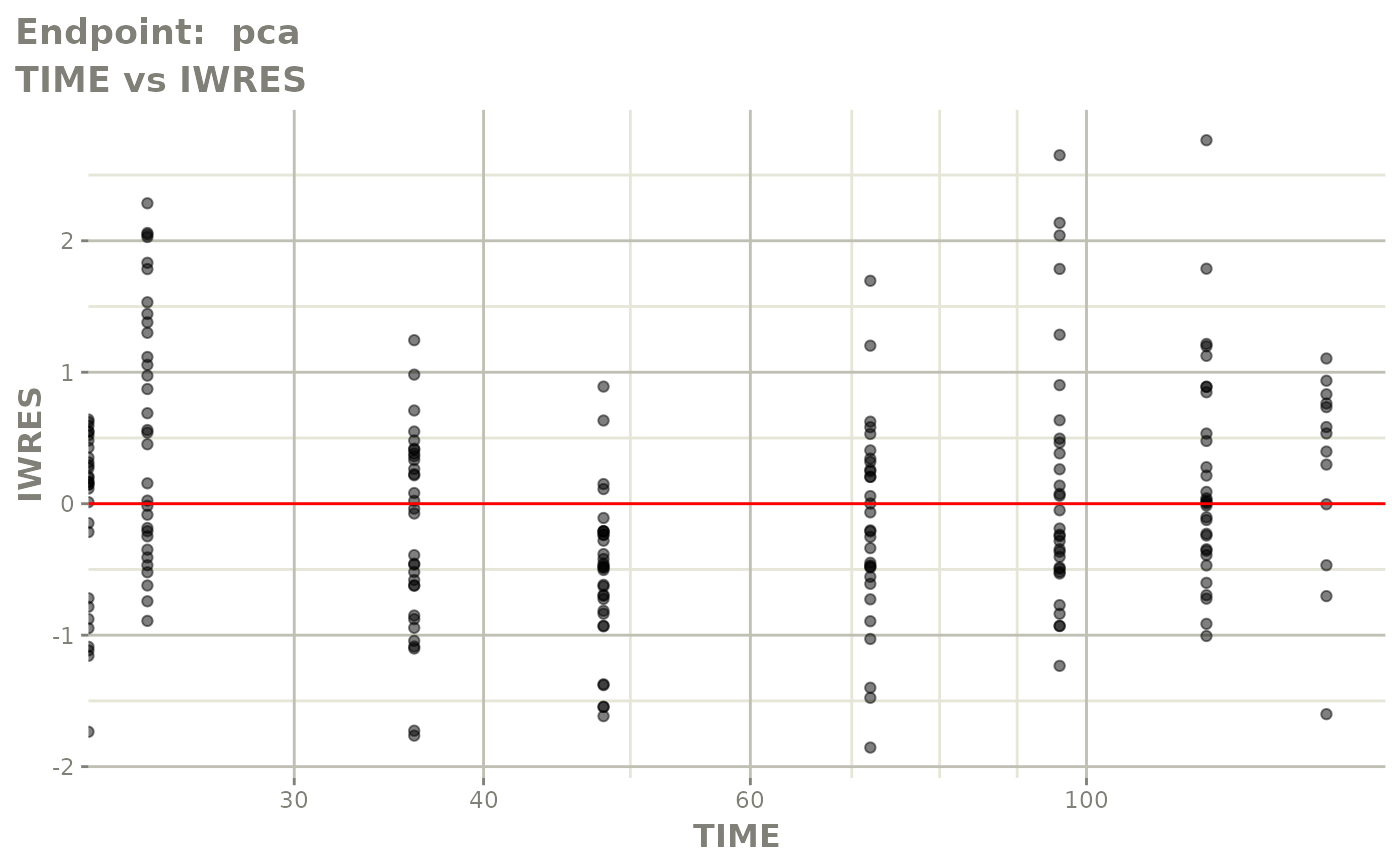
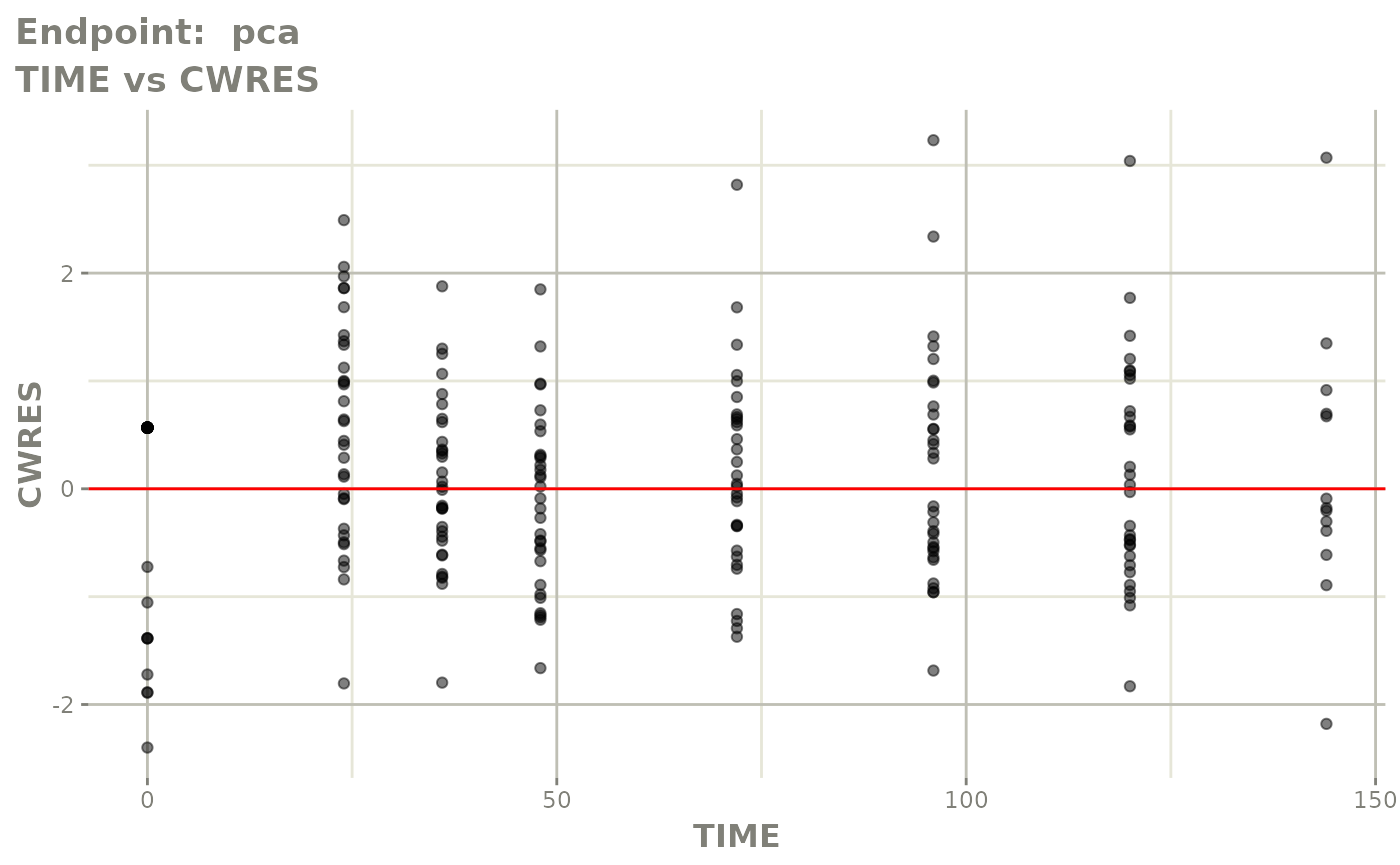
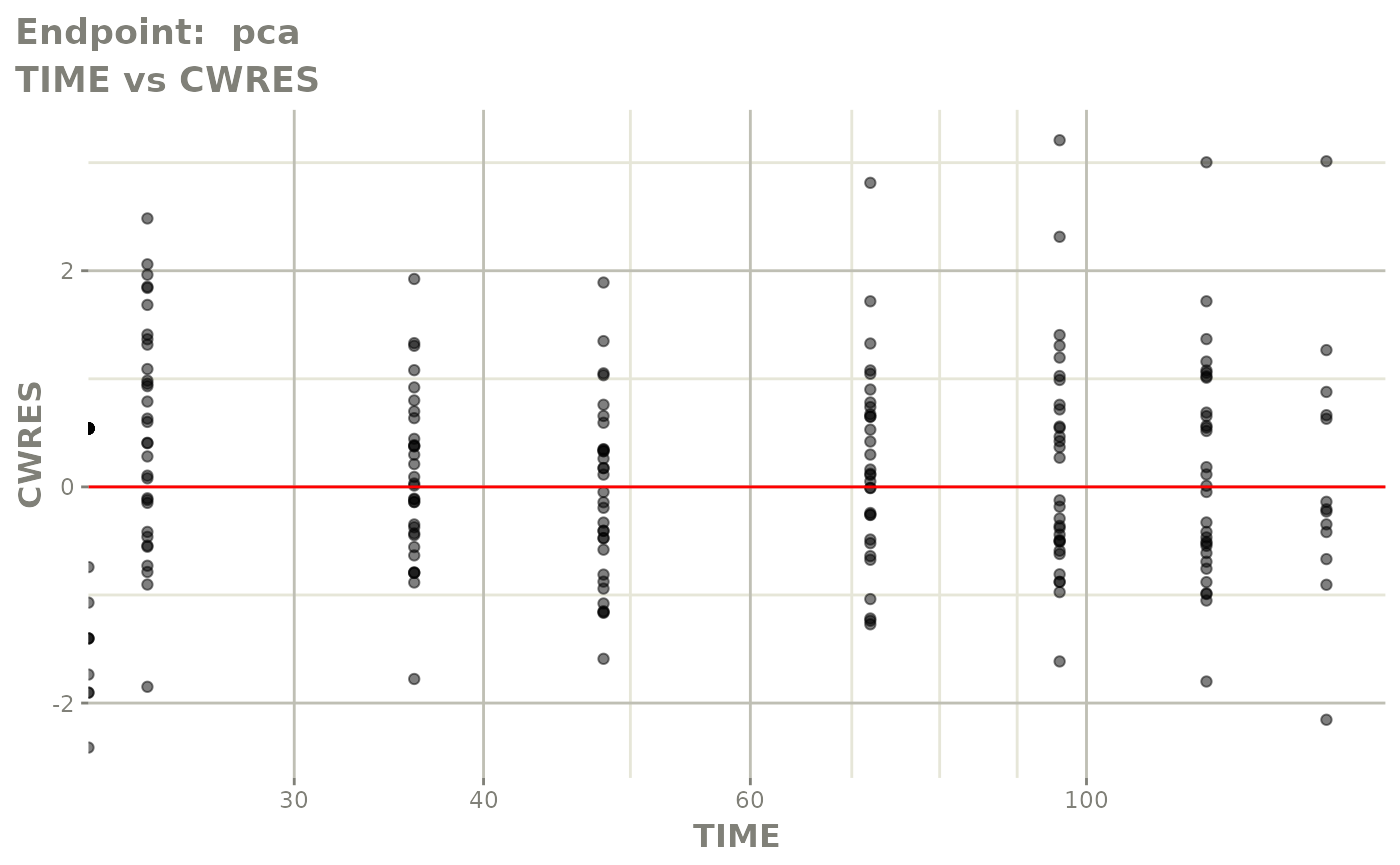
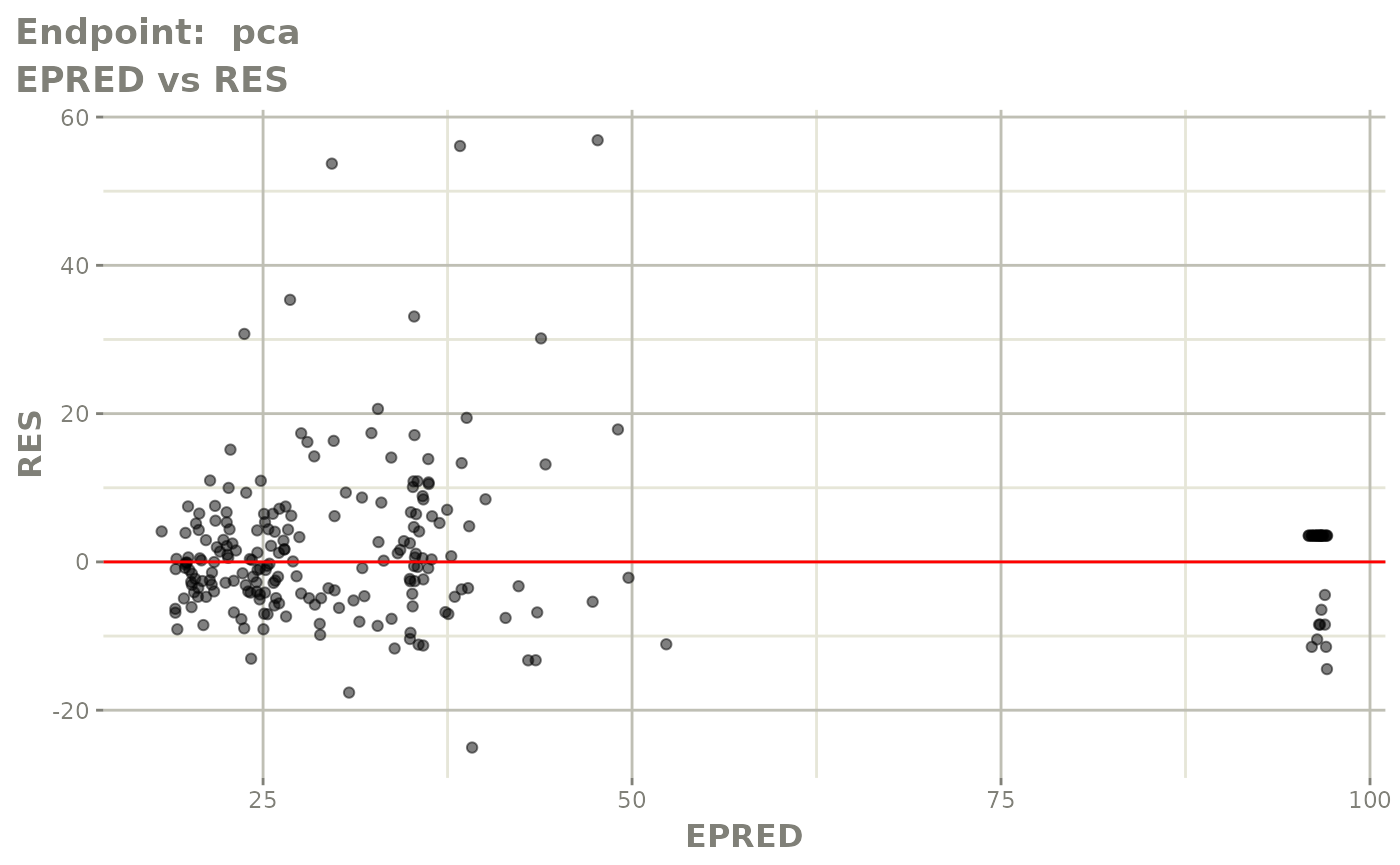
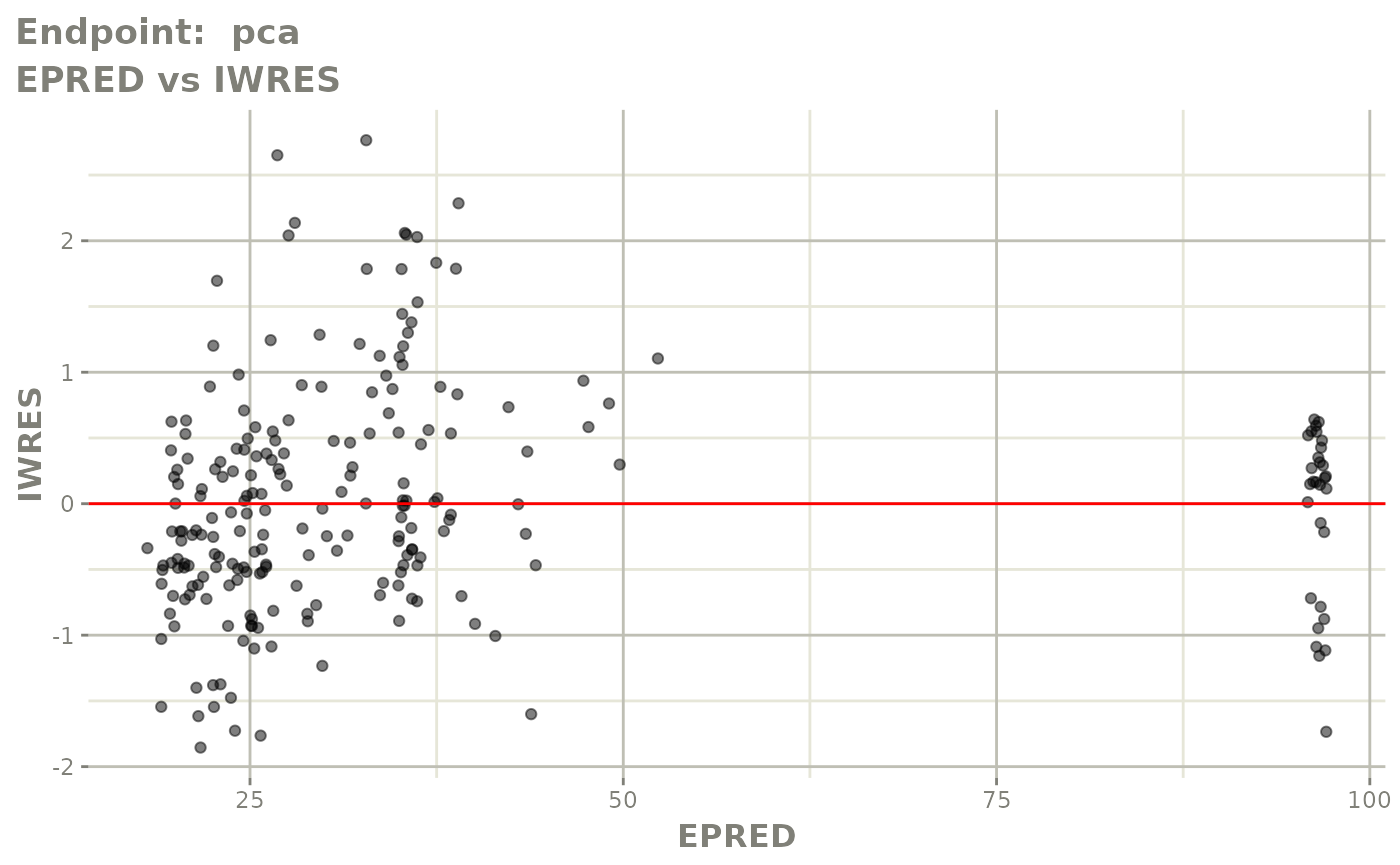
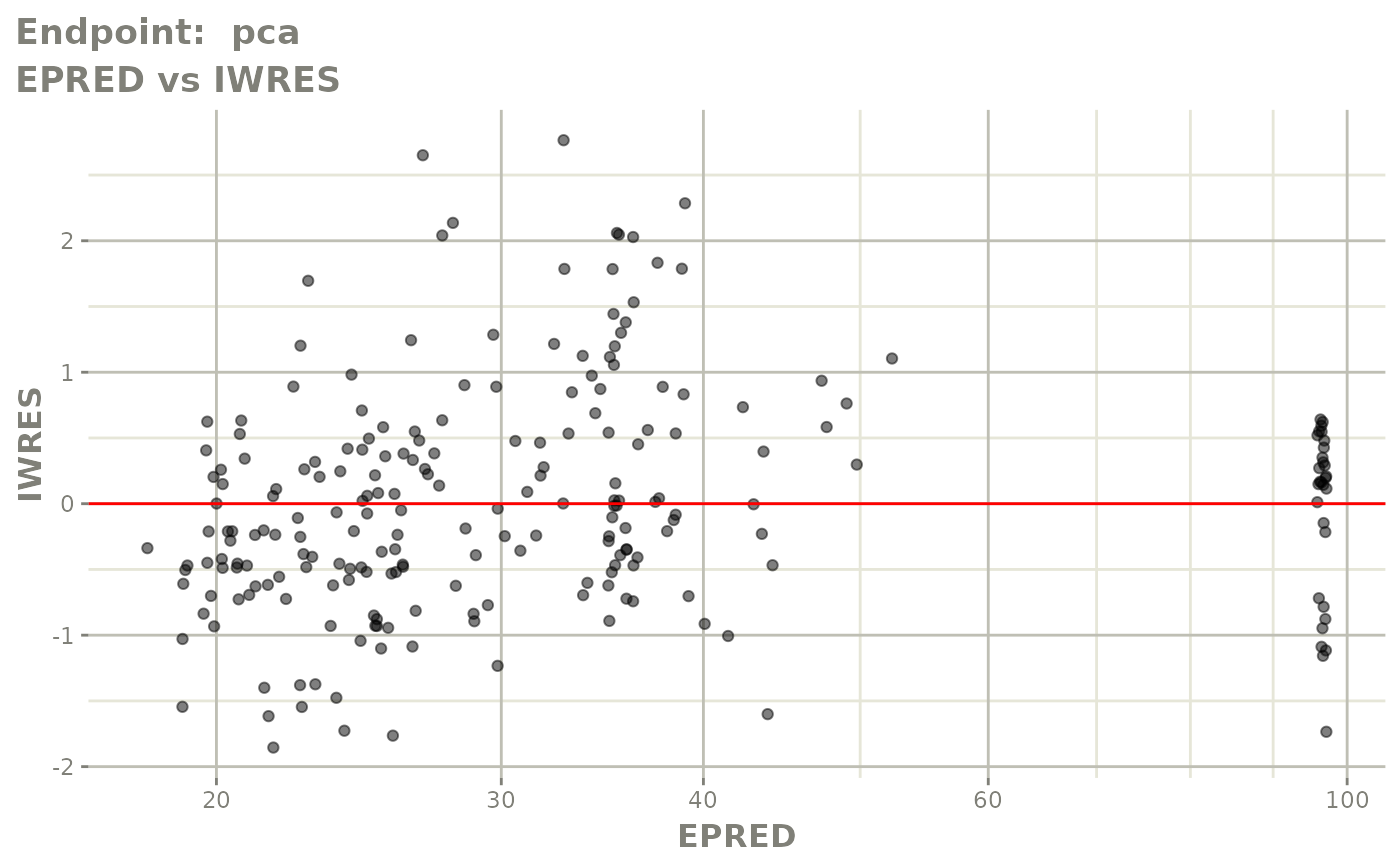
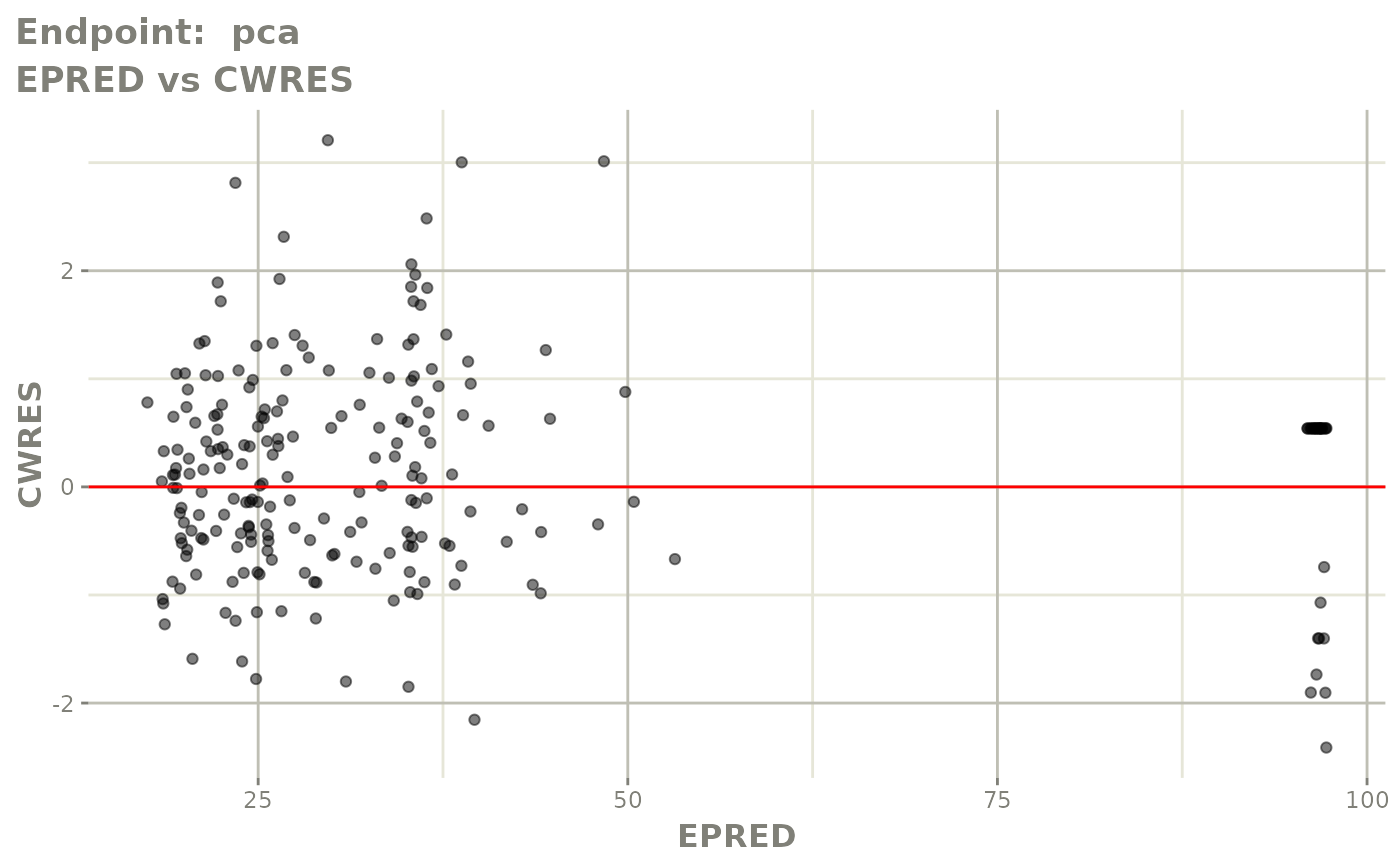
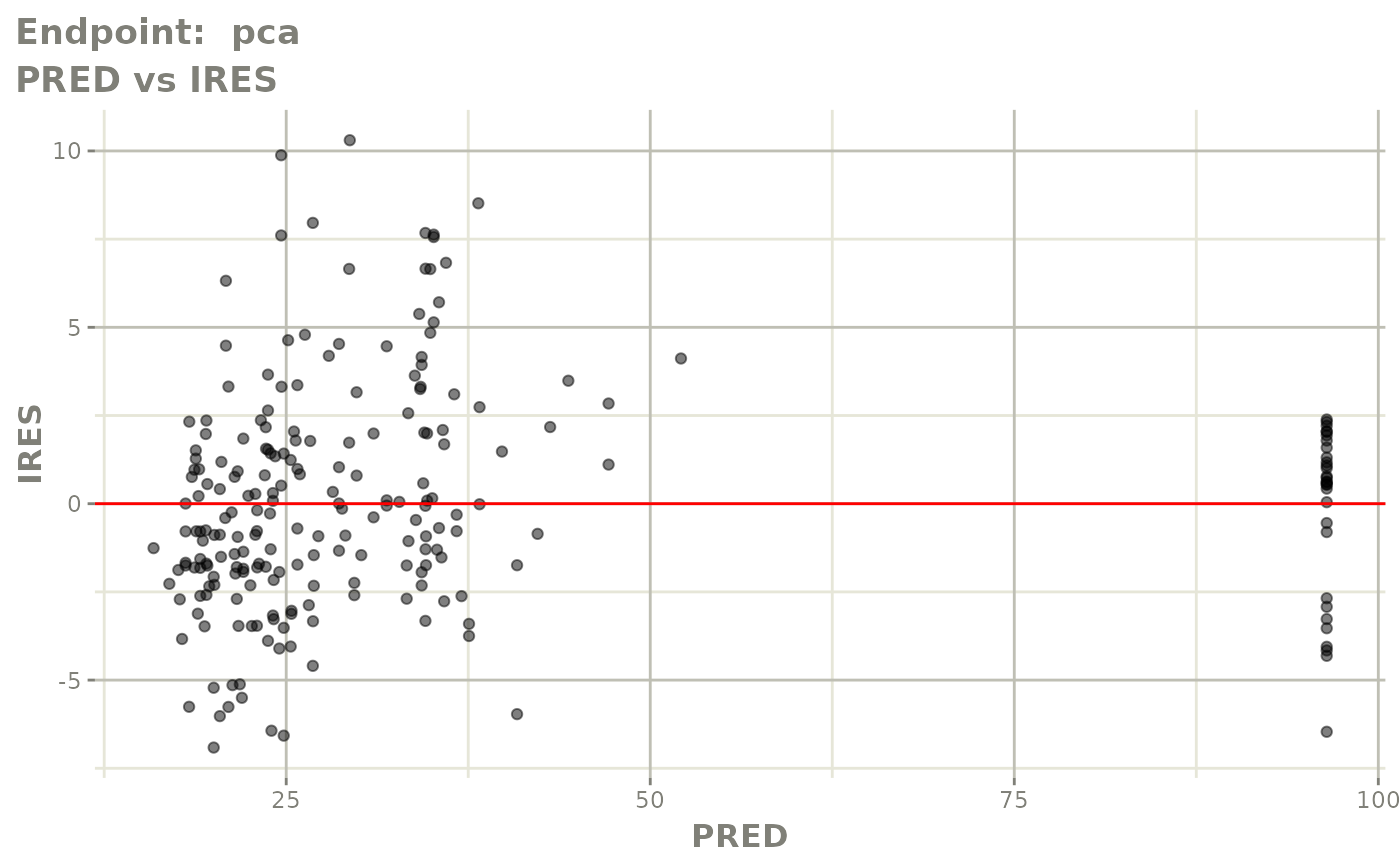
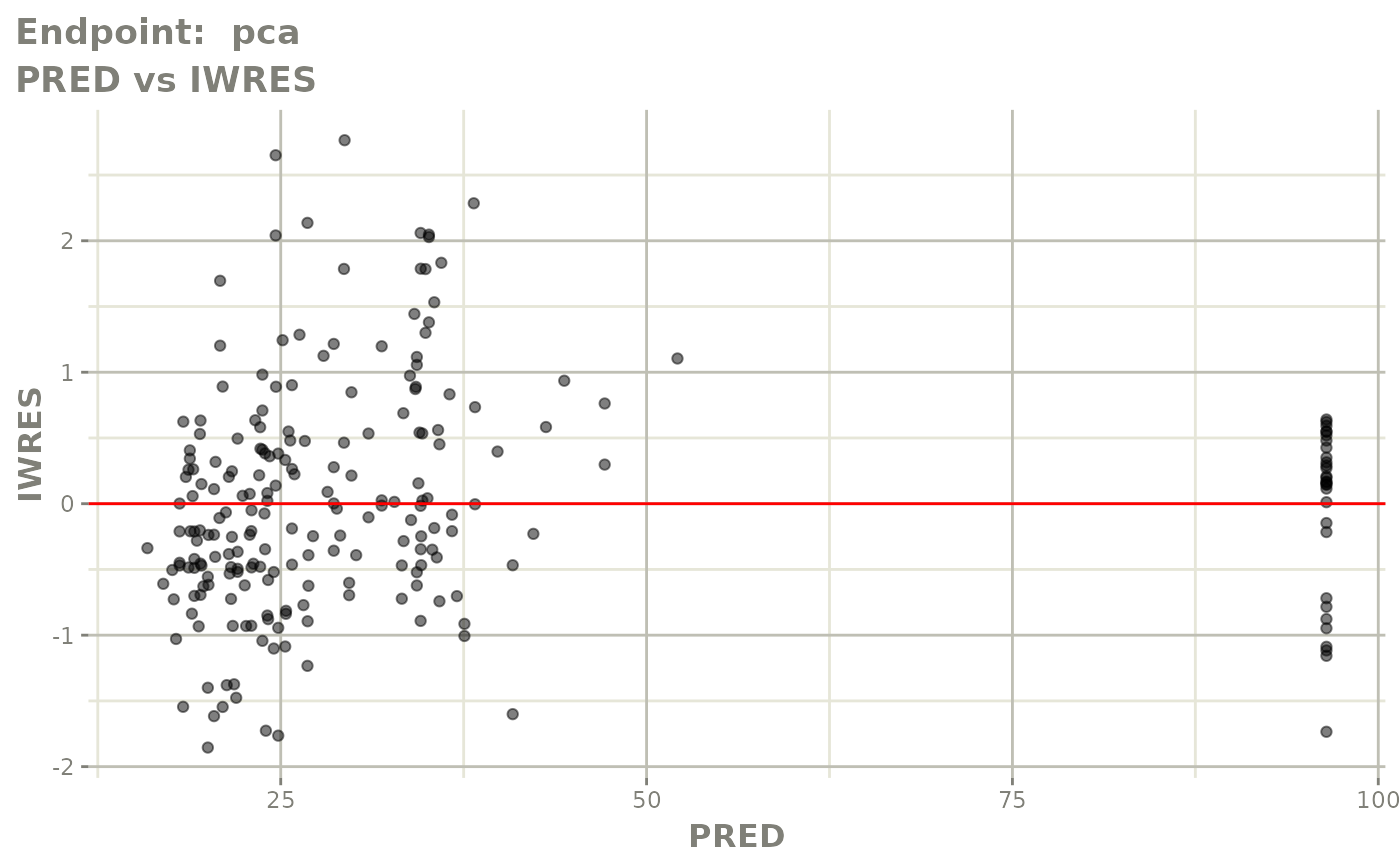
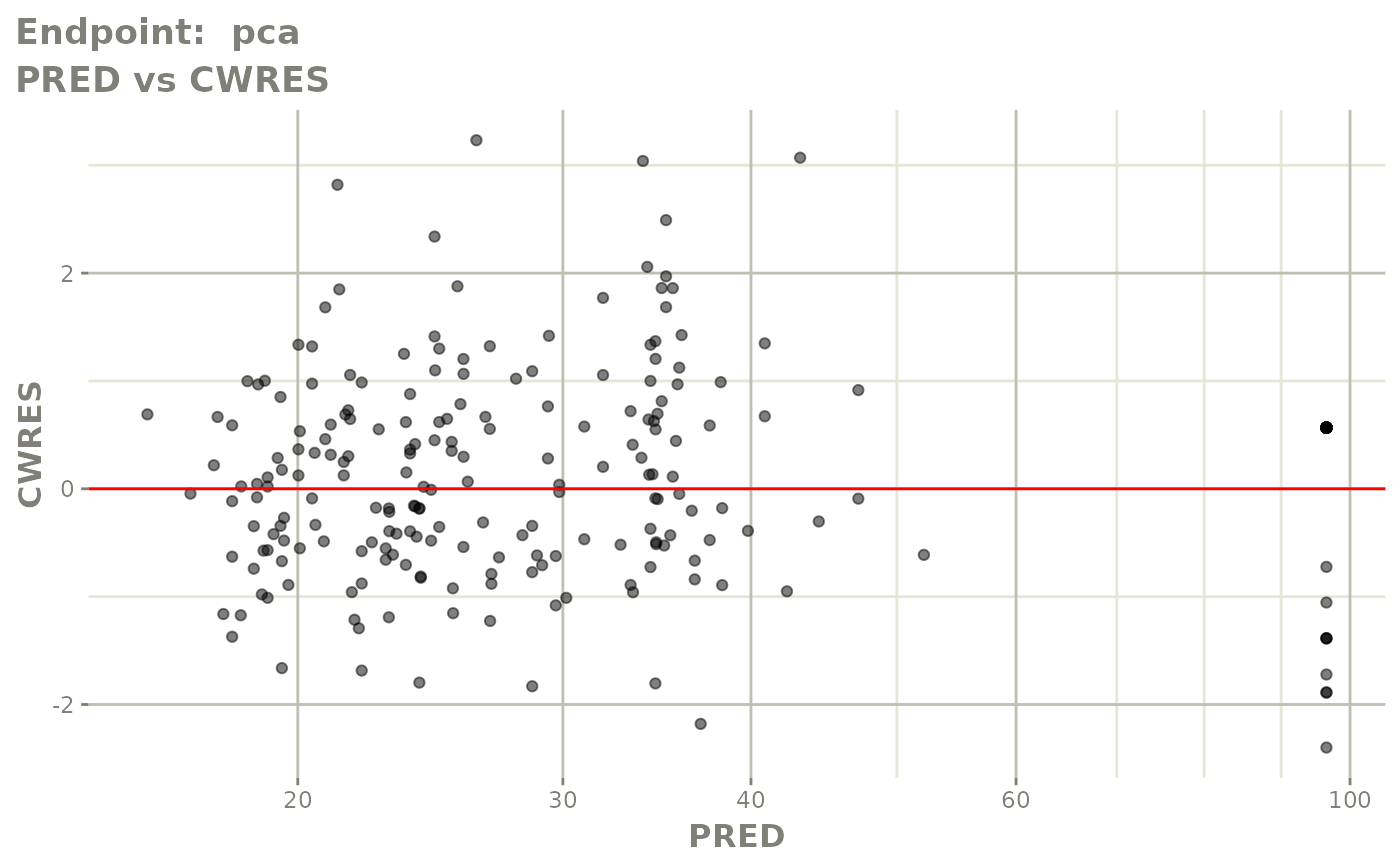
SAEM Diagnostic plots
plot(fit.TOS)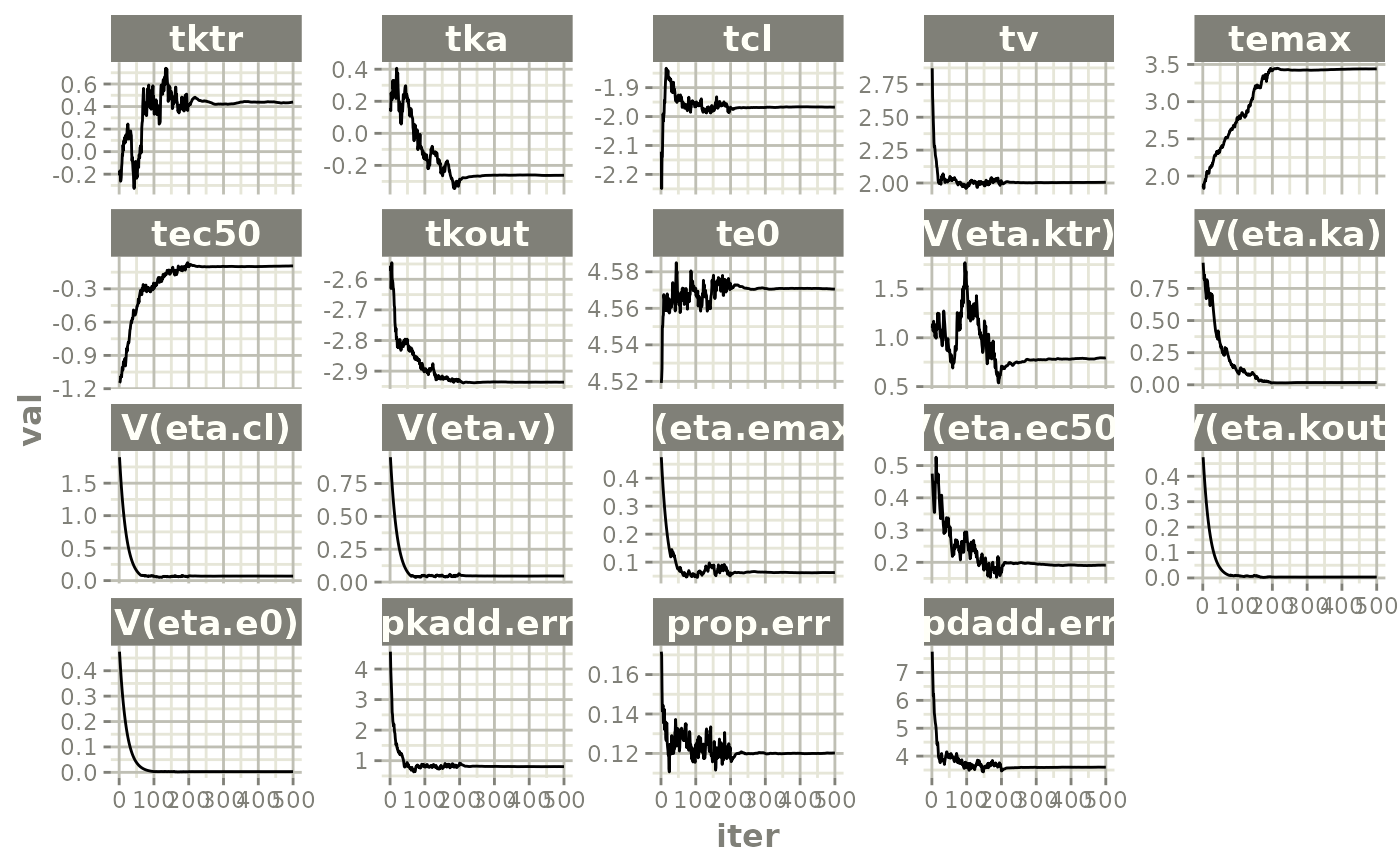




































v1s <- vpcPlot(fit.TOS, show=list(obs_dv=TRUE), scales="free_y") +
  ylab("Warfarin Cp [mg/L] or PCA") +
  xlab("Time [h]")

v2s <- vpcPlot(fit.TOS, show=list(obs_dv=TRUE), pred_corr = TRUE) +
  ylab("Prediction Corrected Warfarin Cp [mg/L] or PCA") +
  xlab("Time [h]")

v1s
v2s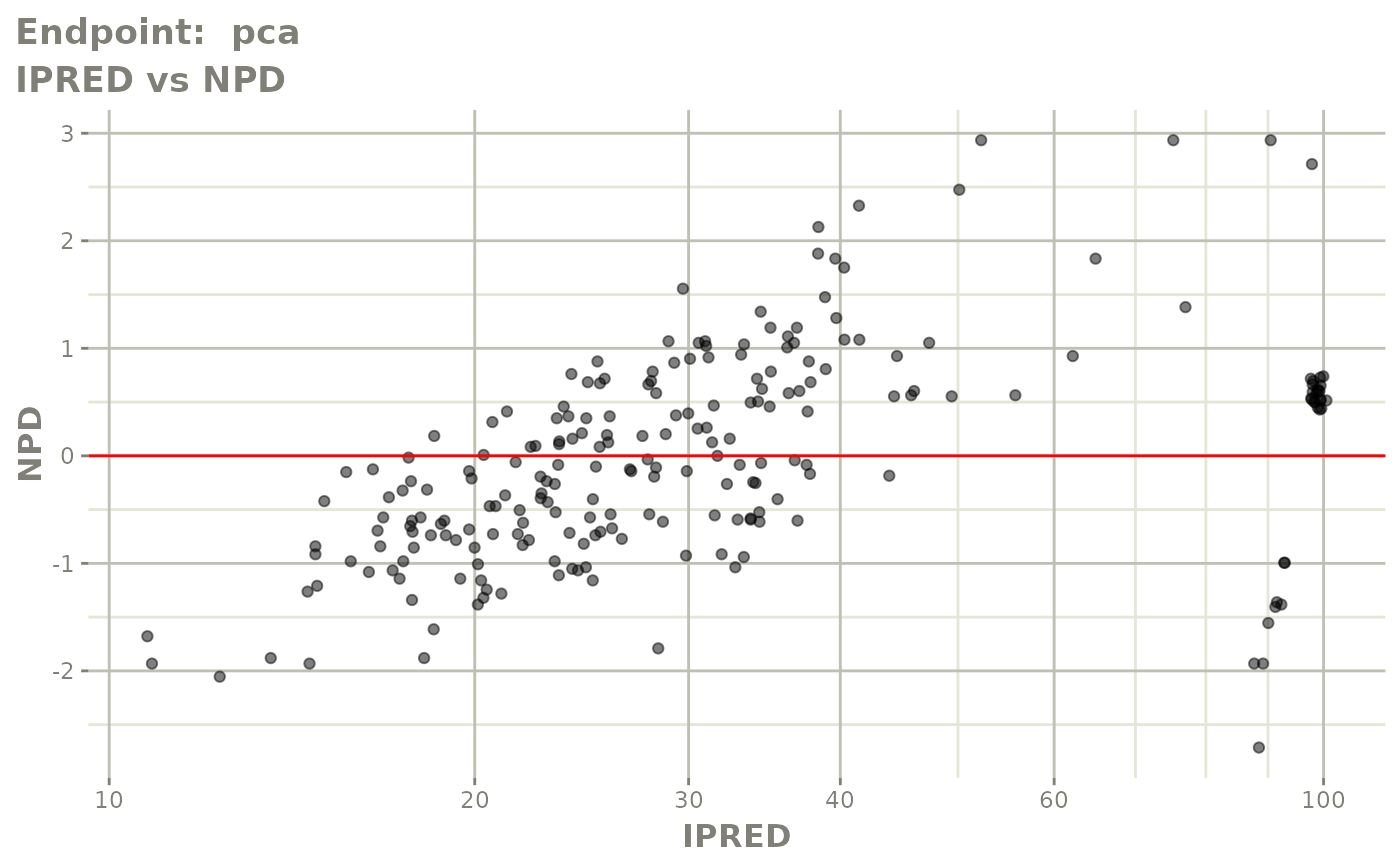
FOCEi fits
## FOCEi fit/vpcs
fit.TOF := nlmixr(pk.turnover.emax3, warfarin, "focei", control=list(print=0),
                  table=list(cwres=TRUE, npde=TRUE))
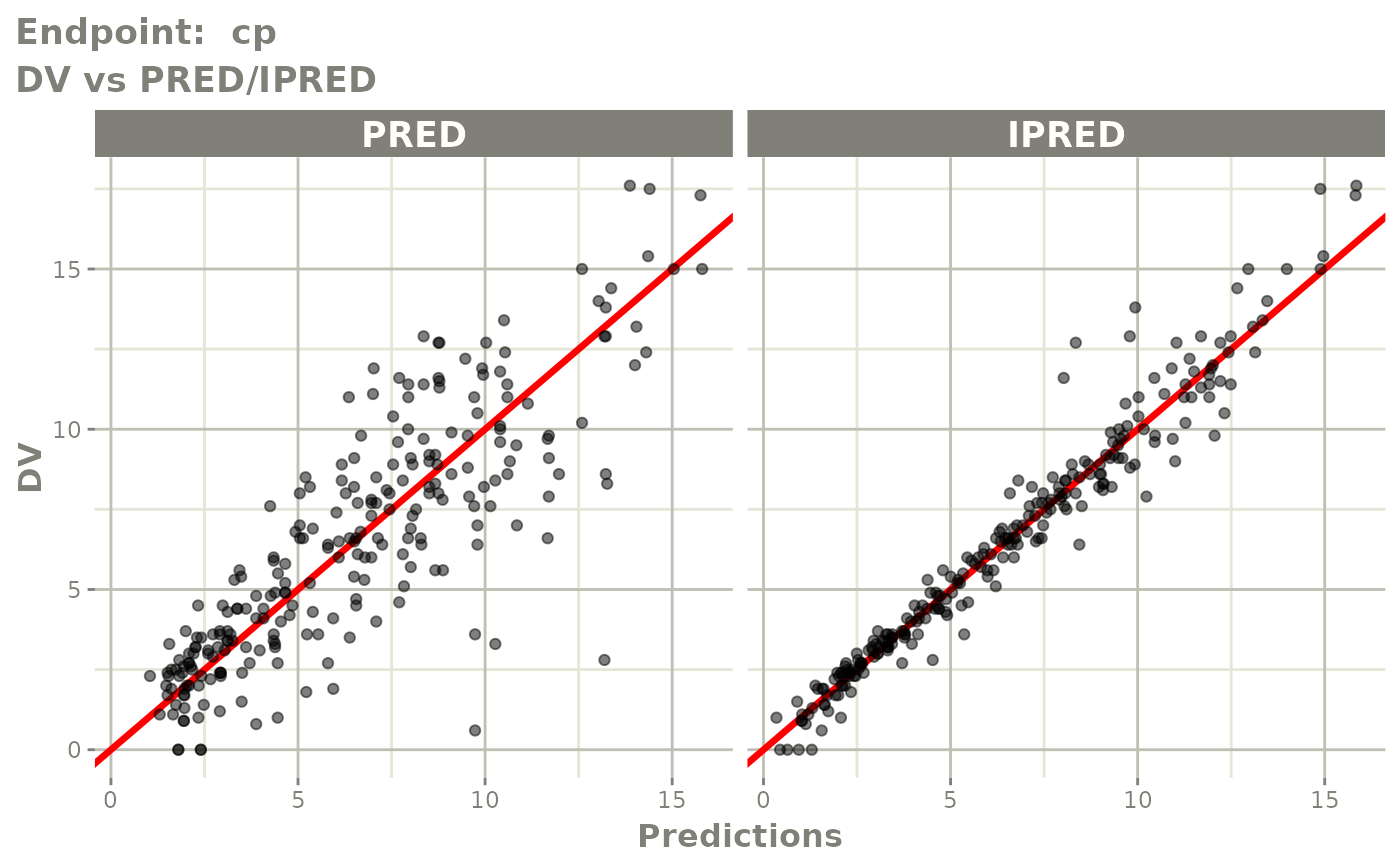
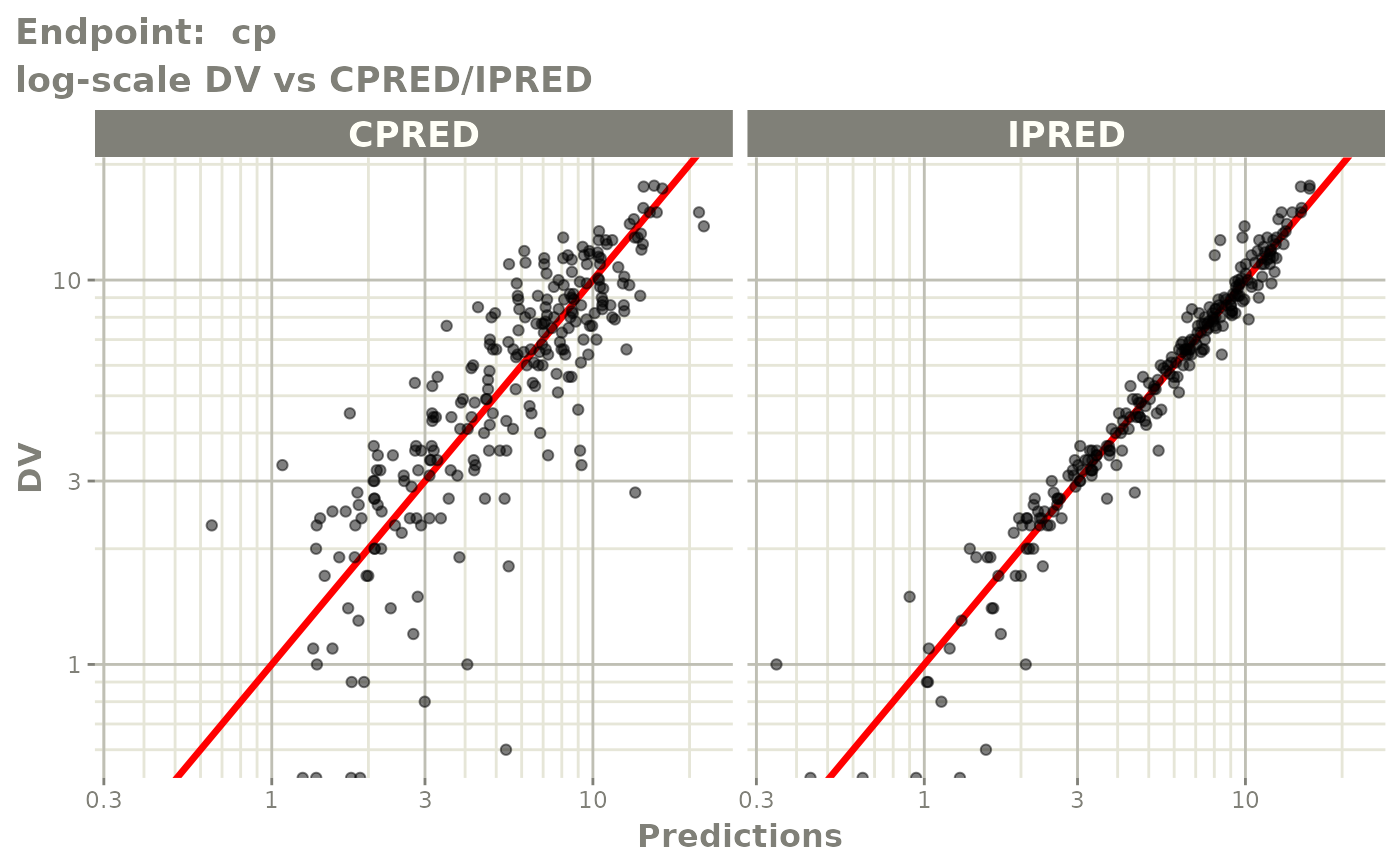
FOCEi Diagnostic Plots
print(fit.TOF)
#> ── nlmixr² FOCEi (outer: nlminb) ──
#>
#>           OBJF      AIC      BIC Log-likelihood Condition#(Cov) Condition#(Cor)
#> FOCEi 4233.486 5159.181 5238.601       -2560.59        7550.108        8.363926
#>
#> ── Time (sec $time): ──
#>
#>            setup optimize covariance preprocess postprocess table compress
#> elapsed 11.63354 3.480453   175.2906      0.052       0.015 0.497    0.001
#>             other
#> elapsed 0.1833817
#>
#> ── Population Parameters ($parFixed or $parFixedDf): ──
#>
#>              Est.      SE  %RSE    Back-transformed(95%CI) BSV(CV% or SD)
#> tktr      0.02223  0.3480  1565      1.022 (0.5170, 2.022)          131.6
#> tka       0.02225  0.3478  1563      1.022 (0.5171, 2.022)          132.9
#> tcl        -2.074 0.09240 4.455    0.1257 (0.1049, 0.1506)          39.65
#> tv          2.134 0.06880 3.225       8.445 (7.379, 9.664)          42.20
#> prop.err   0.1406 0.01222 8.692    0.1406 (0.1167, 0.1646)
#> pkadd.err  0.1240 0.02695 21.73   0.1240 (0.07119, 0.1768)
#> temax       2.584  0.2393 9.260    0.9298 (0.8924, 0.9549)         0.7012
#> tec50     -0.3697 0.06443 17.43    0.6910 (0.6090, 0.7840)          113.2
#> tkout      -2.911 0.08167 2.806 0.05444 (0.04639, 0.06389)          45.85
#> te0         4.578 0.06759 1.476       97.34 (85.26, 111.1)          39.17
#> pdadd.err   5.743  0.6152 10.71       5.743 (4.537, 6.948)
#>           Shrink(SD)%
#> tktr           65.84
#> tka            65.85
#> tcl            27.19
#> tv             42.58
#> prop.err
#> pkadd.err
#> temax          83.73
#> tec50          41.73
#> tkout          68.34
#> te0            80.78
#> pdadd.err
#>
#>   Covariance Type ($covMethod): r
#>   Some strong fixed parameter correlations exist ($cor) :
#>                cor:tka,tktr            cor:tcl,tktr             cor:tv,tktr
#>                 -0.287                  -0.0387                  -0.0168
#>       cor:prop.err,tktr      cor:pkadd.err,tktr          cor:temax,tktr
#>                -0.0262                   0.0190                 -0.00670
#>          cor:tec50,tktr          cor:tkout,tktr            cor:te0,tktr
#>                0.00921                  -0.0185                 0.000153
#>      cor:pdadd.err,tktr             cor:tcl,tka              cor:tv,tka
#>                 0.0232                  -0.0382                  -0.0180
#>        cor:prop.err,tka       cor:pkadd.err,tka           cor:temax,tka
#>                -0.0289                   0.0211                 -0.00679
#>           cor:tec50,tka           cor:tkout,tka             cor:te0,tka
#>                0.00887                  -0.0189               -0.0000596
#>       cor:pdadd.err,tka              cor:tv,tcl        cor:prop.err,tcl
#>                 0.0230                   0.0148                   0.0817
#>       cor:pkadd.err,tcl           cor:temax,tcl           cor:tec50,tcl
#>                -0.0729                  0.00281                  -0.0463
#>           cor:tkout,tcl             cor:te0,tcl       cor:pdadd.err,tcl
#>               0.000636                  0.00138                  -0.0189
#>         cor:prop.err,tv        cor:pkadd.err,tv            cor:temax,tv
#>                 0.0454                  -0.0362                 -0.00326
#>            cor:tec50,tv            cor:tkout,tv              cor:te0,tv
#>               -0.00728                   0.0178                 0.000718
#>        cor:pdadd.err,tv  cor:pkadd.err,prop.err      cor:temax,prop.err
#>                 0.0250                   -0.783                 0.00627
#>      cor:tec50,prop.err      cor:tkout,prop.err        cor:te0,prop.err
#>                -0.0279                   0.0106                  0.00365
#>  cor:pdadd.err,prop.err     cor:temax,pkadd.err     cor:tec50,pkadd.err
#>                0.00772                 -0.00480                   0.0120
#>     cor:tkout,pkadd.err       cor:te0,pkadd.err cor:pdadd.err,pkadd.err
#>                -0.0130                 -0.00405                  -0.0163
#>         cor:tec50,temax         cor:tkout,temax           cor:te0,temax
#>                 -0.500                  -0.210                  0.00803
#>     cor:pdadd.err,temax         cor:tkout,tec50           cor:te0,tec50
#>                 -0.263                    0.212                  -0.0552
#>     cor:pdadd.err,tec50           cor:te0,tkout     cor:pdadd.err,tkout
#>                  0.210                  0.00954                   0.0725
#>       cor:pdadd.err,te0
#>                -0.0153
#>
#>
#>   No correlations in between subject variability (BSV) matrix
#>   Full BSV covariance ($omega) or correlation ($omegaR; diagonals=SDs)
#>   Distribution stats (mean/skewness/kurtosis/p-value) available in $shrink
#>   Information about run found ($runInfo):
#>    • analytic covariance is not positive definite; keeping the finite-difference covariance
#>    • tolerances (atol/rtol) were increased (after 4 bad solves) for some difficult ODE solving during the optimization. can control with foceiControl(stickyRecalcN=) consider increasing sigdig/atol/rtol changing initial estimates or changing the structural model
#>    • gradient problems with initial estimate and covariance; see $scaleInfo
#>    • last objective function was not at minimum, possible problems in optimization
#>    • ETAs were reset to zero during optimization; (Can control by foceiControl(resetEtaP=.))
#>    • Hessian reset during optimization; (can control by foceiControl(resetHessianAndEta=.))
#>   Censoring ($censInformation): No censoring
#>   Minimization message ($message):
#>     false convergence (8)
#>   In an ODE system, false convergence may mean "useless" evaluations were performed.
#>   See https://tinyurl.com/yyrrwkce
#>   It could also mean the convergence is poor, check results before accepting fit
#>   You may also try a good derivative free optimization:
#>     nlmixr2(...,control=list(outerOpt="bobyqa"))
#>
#> ── Fit Data (object is a modified tibble): ──
#> # A tibble: 483 × 44
#>   ID     TIME CMT      DV EPRED  ERES   NPDE    NPD   PDE     PD  PRED   RES
#>   <fct> <dbl> <chr> <dbl> <dbl> <dbl>  <dbl>  <dbl> <dbl>  <dbl> <dbl> <dbl>
#> 1 1       0.5 cp      0    1.86 -1.86 -0.583 -2.13  0.28  0.0167  1.11 -1.11
#> 2 1       1   cp      1.9  3.91 -2.01 -0.219 -0.449 0.413 0.327   3.21 -1.31
#> 3 1       2   cp      3.3  6.83 -3.53 -1.19  -0.685 0.117 0.247   7.08 -3.78
#> # ℹ 480 more rows
#> # ℹ 32 more variables: WRES <dbl>, IPRED <dbl>, IRES <dbl>, IWRES <dbl>,
#> #   CPRED <dbl>, CRES <dbl>, CWRES <dbl>, eta.ktr <dbl>, eta.ka <dbl>,
#> #   eta.cl <dbl>, eta.v <dbl>, eta.emax <dbl>, eta.ec50 <dbl>, eta.kout <dbl>,
#> #   eta.e0 <dbl>, depot <dbl>, gut <dbl>, center <dbl>, effect <dbl>,
#> #   ktr <dbl>, ka <dbl>, cl <dbl>, v <dbl>, emax <dbl>, ec50 <dbl>, kout <dbl>,
#> #   e0 <dbl>, DCP <dbl>, PD.1 <dbl>, kin <dbl>, tad <dbl>, dosenum <int>
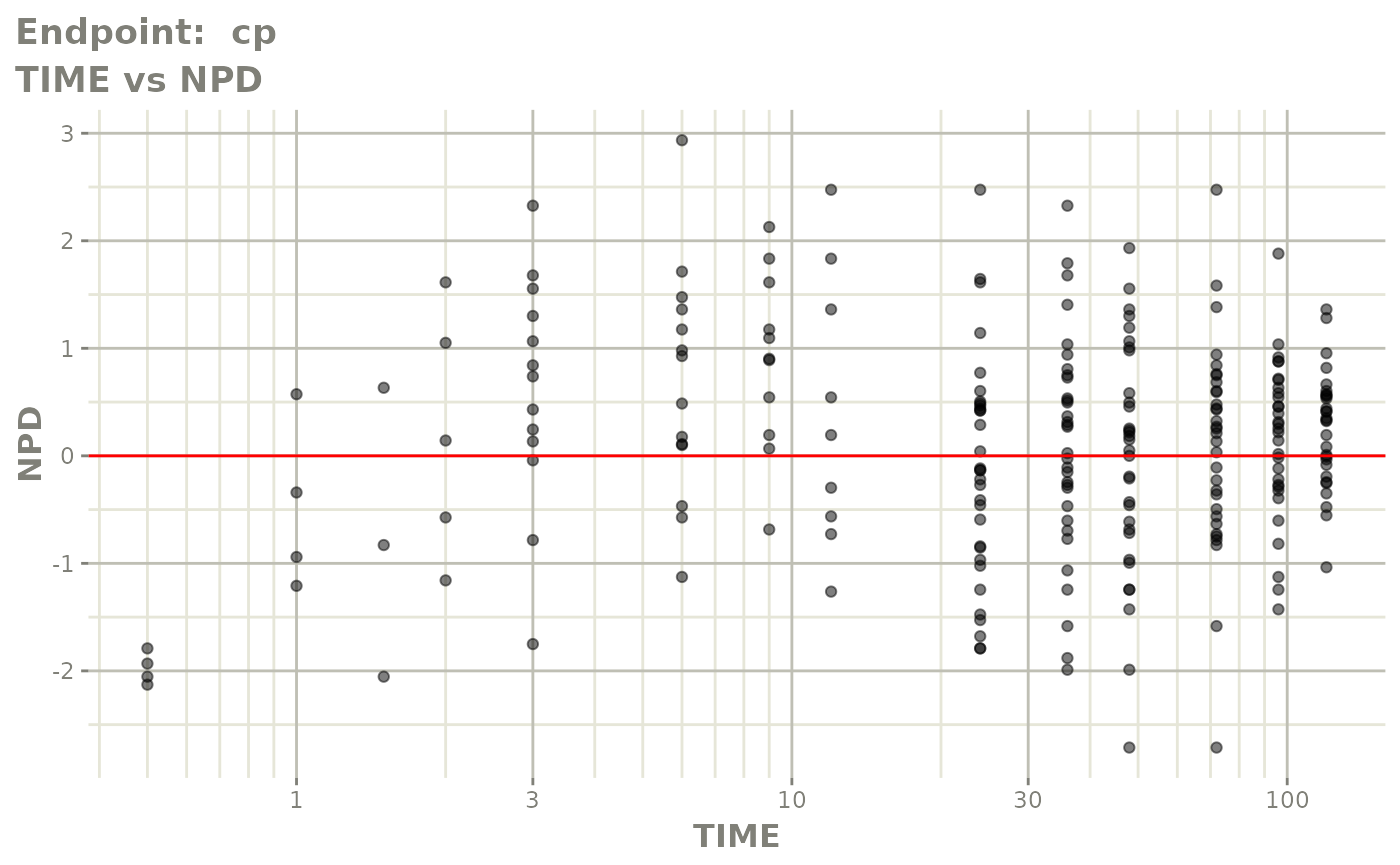
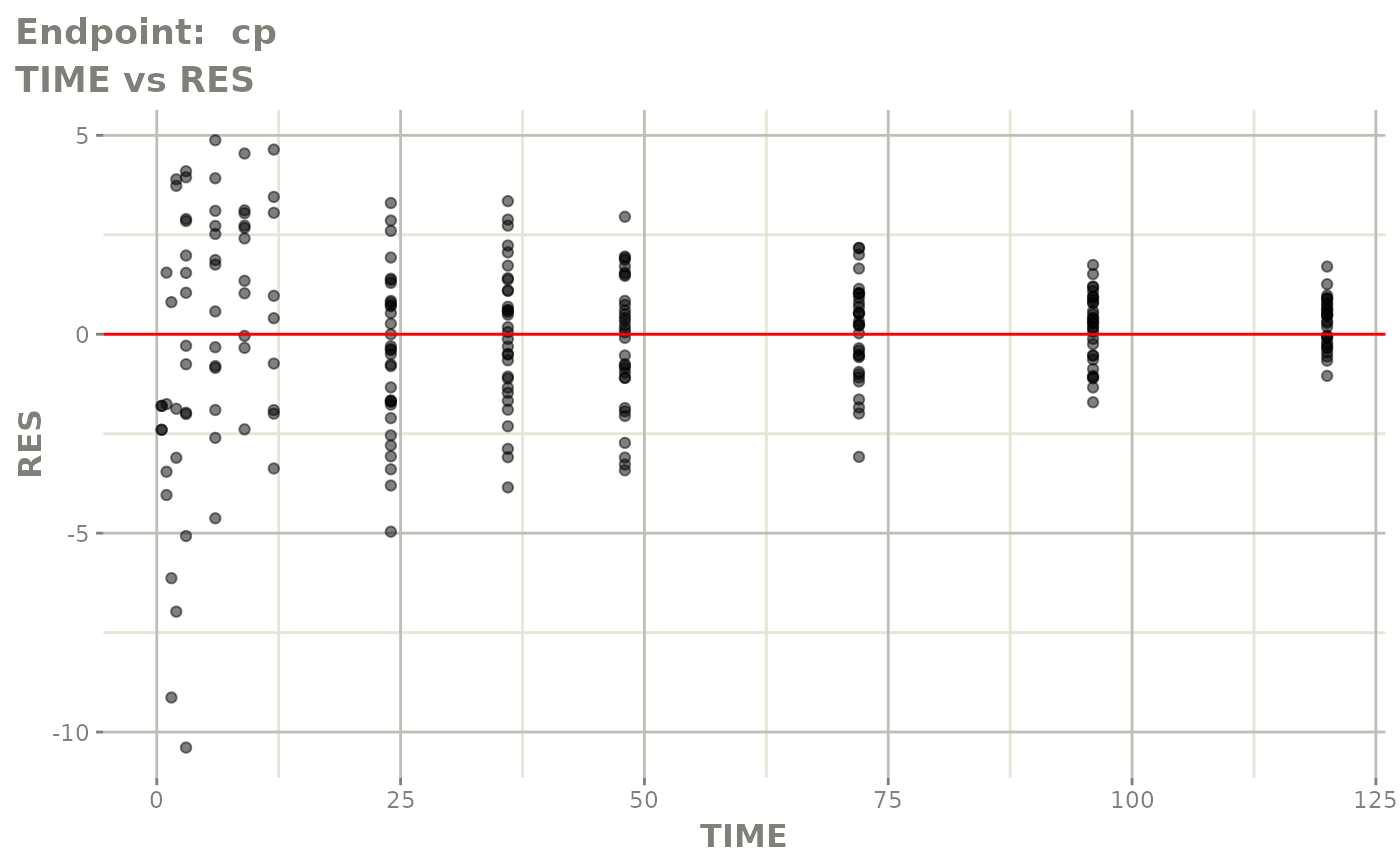
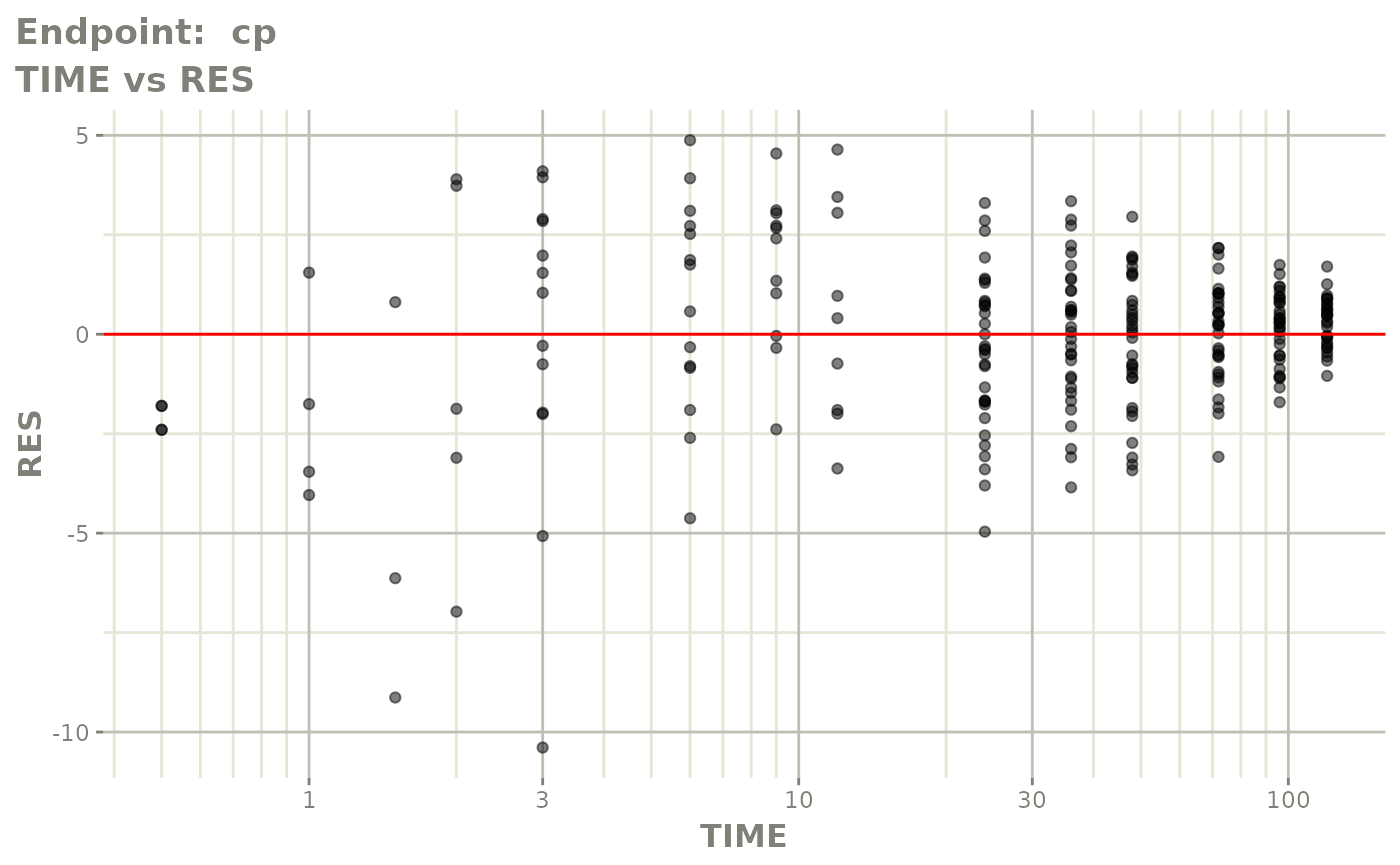
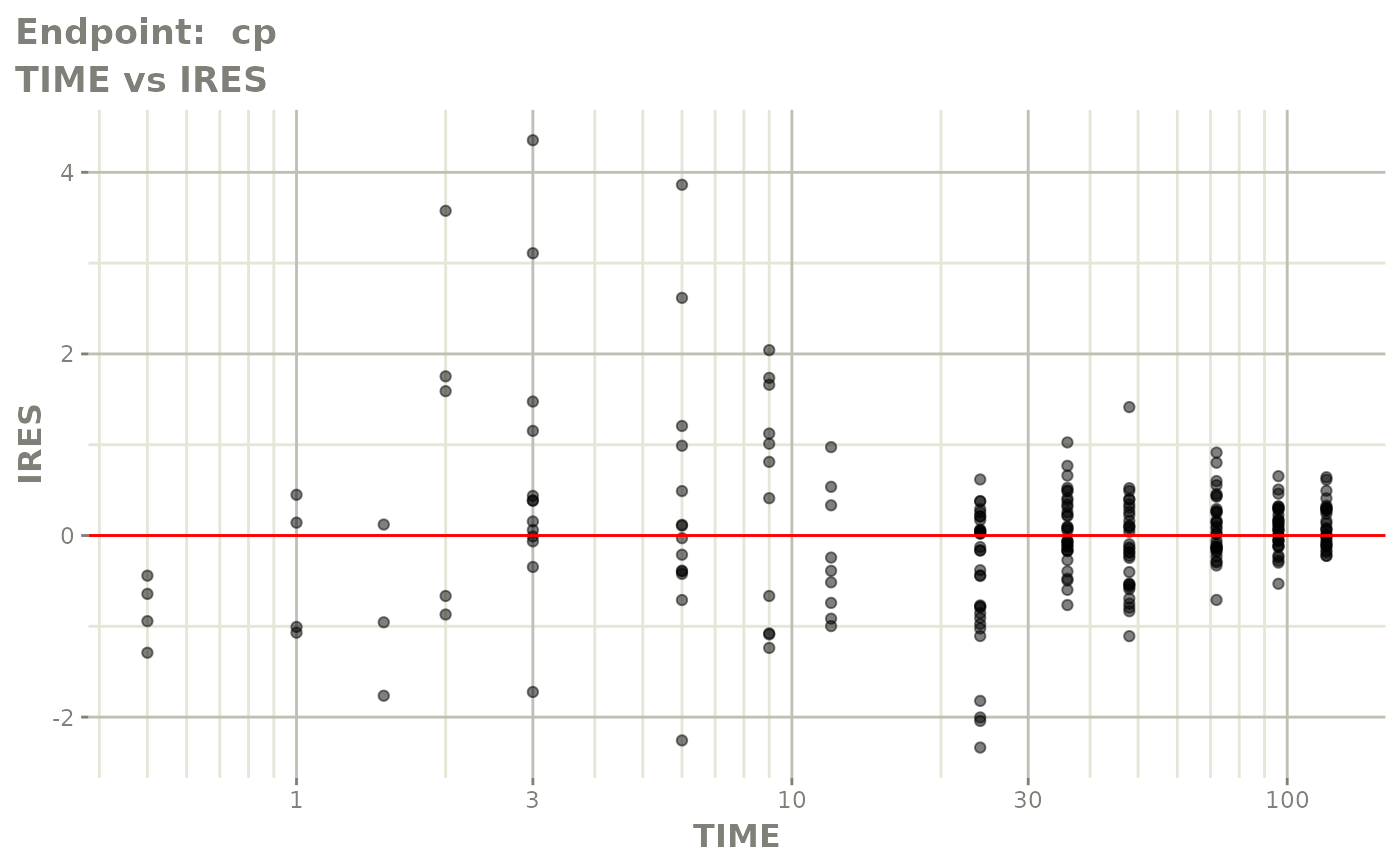
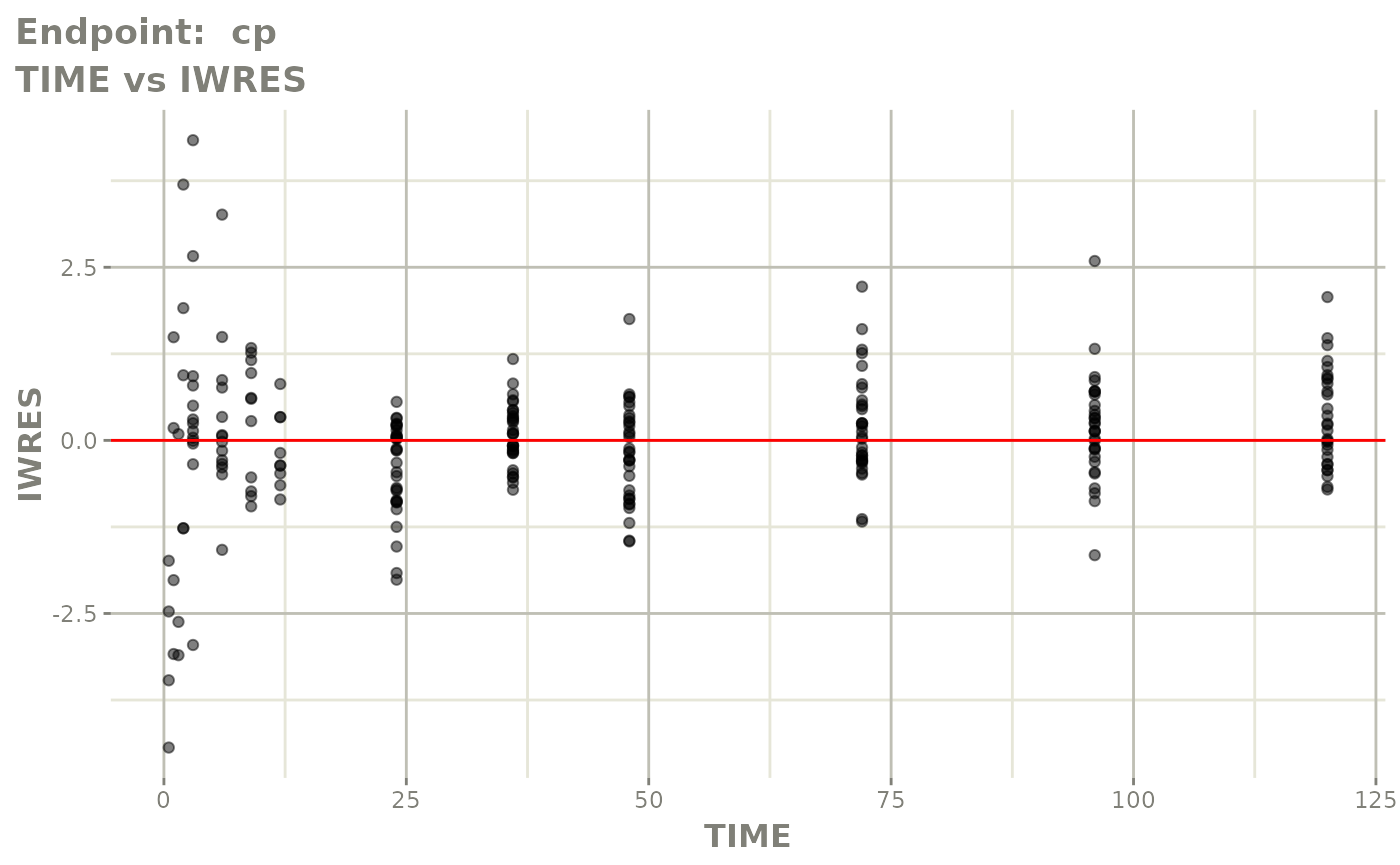
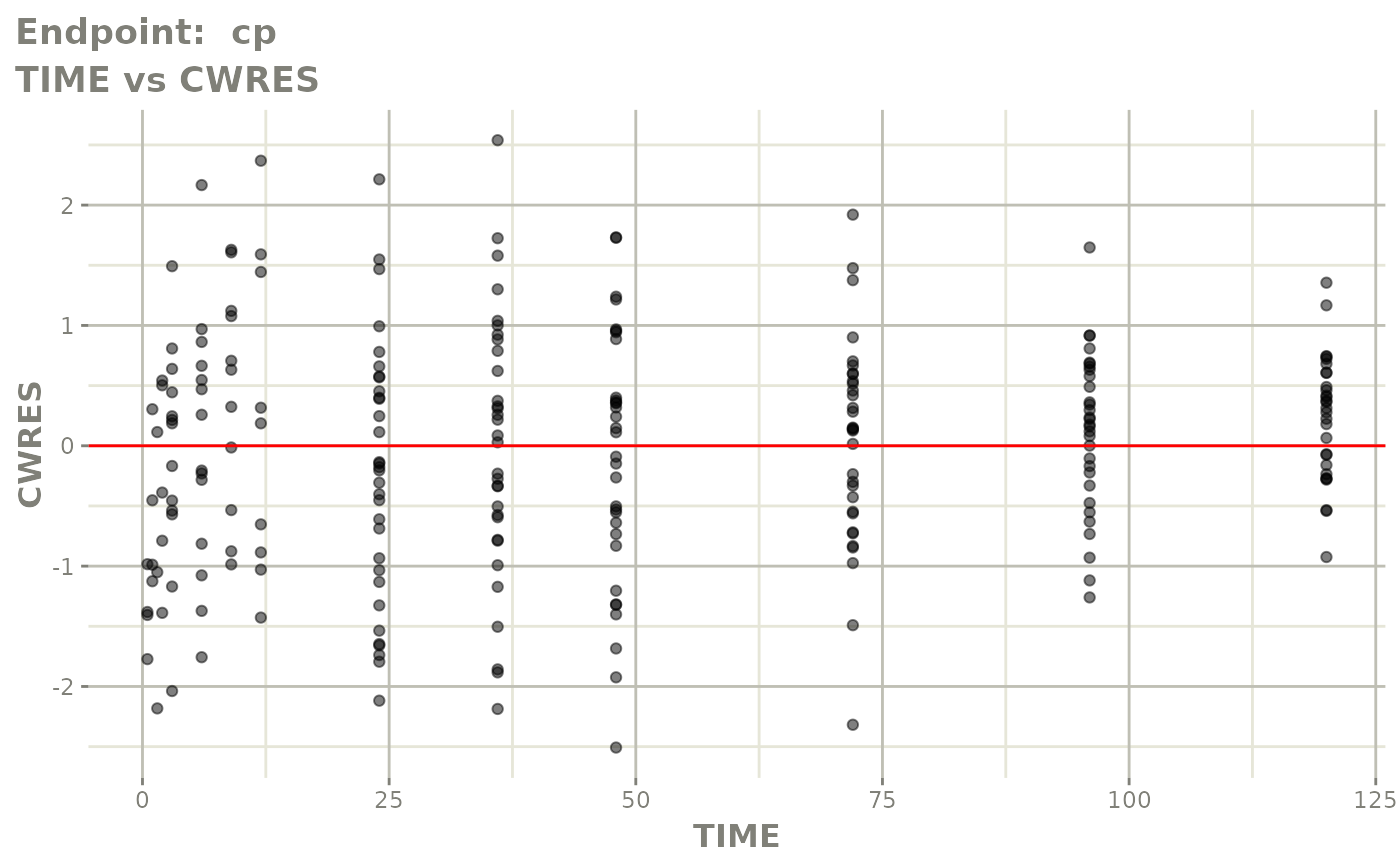
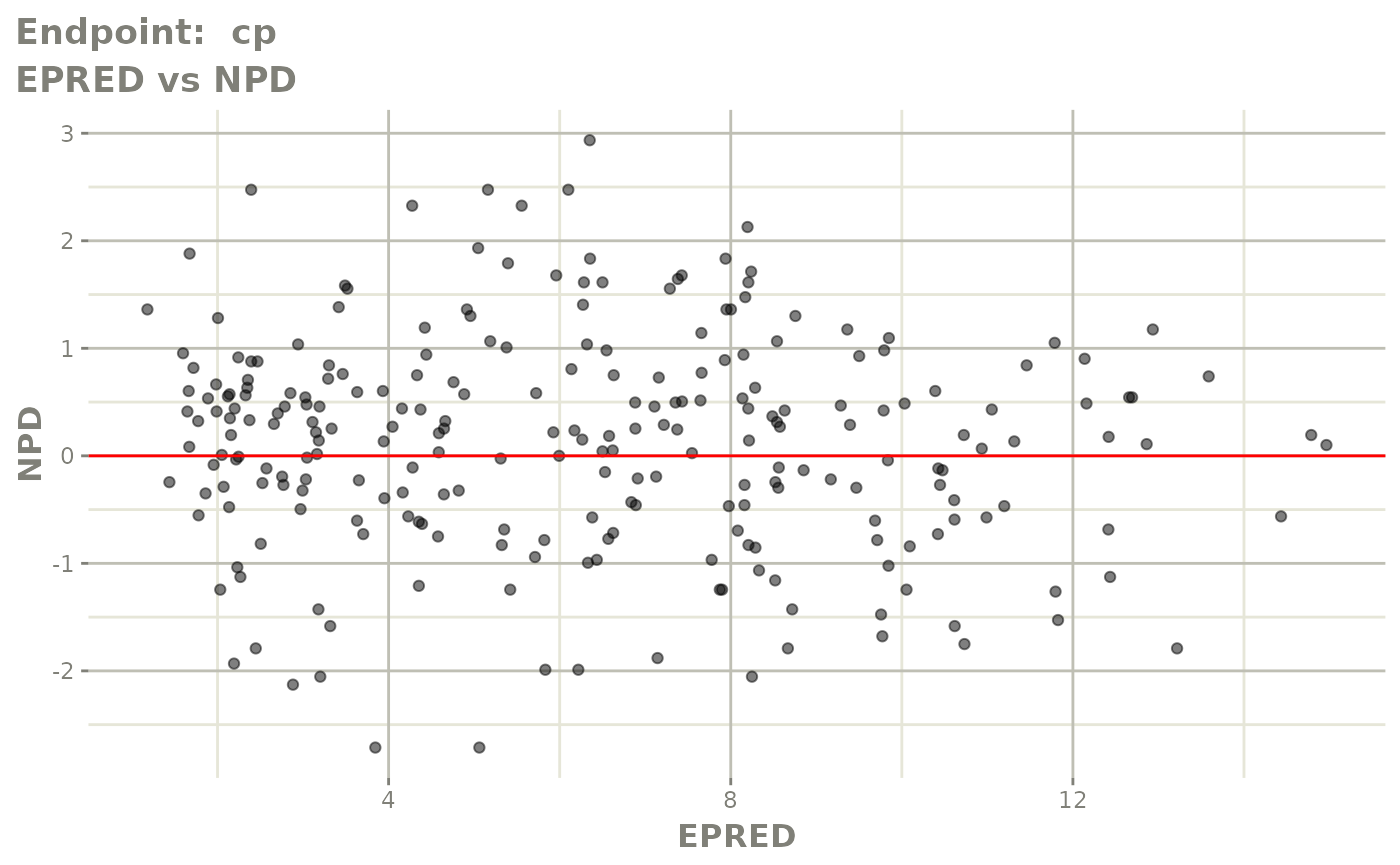
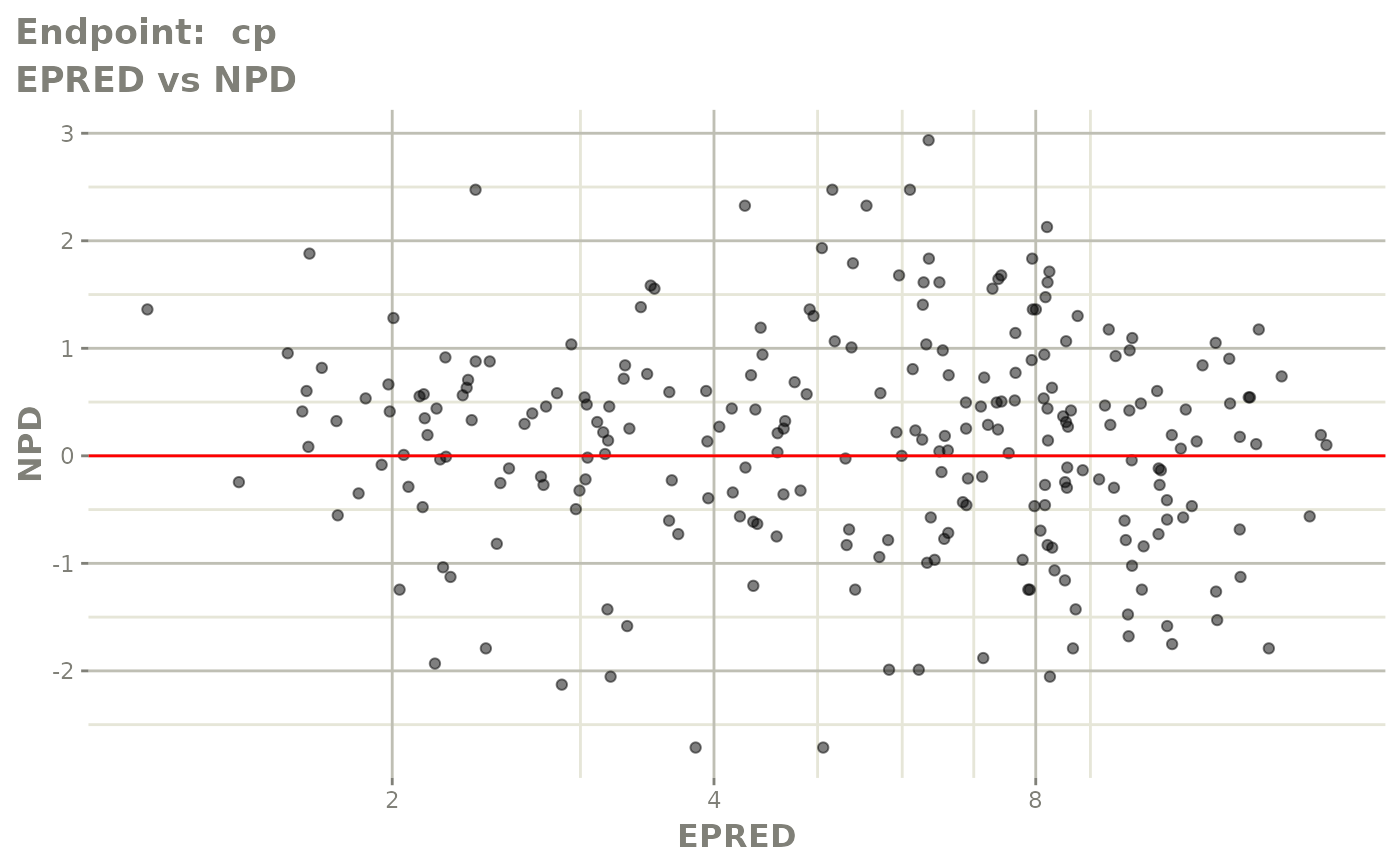
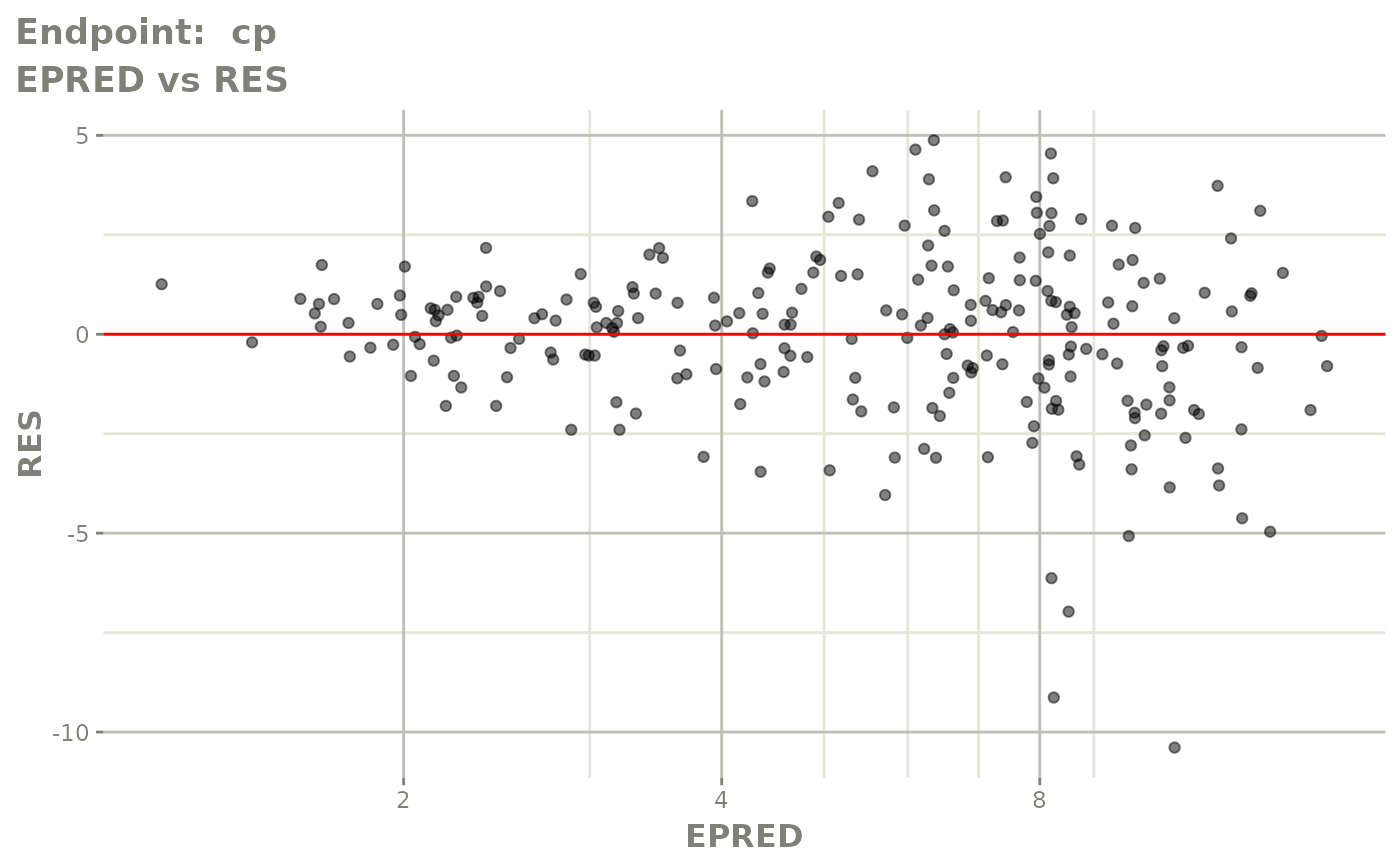
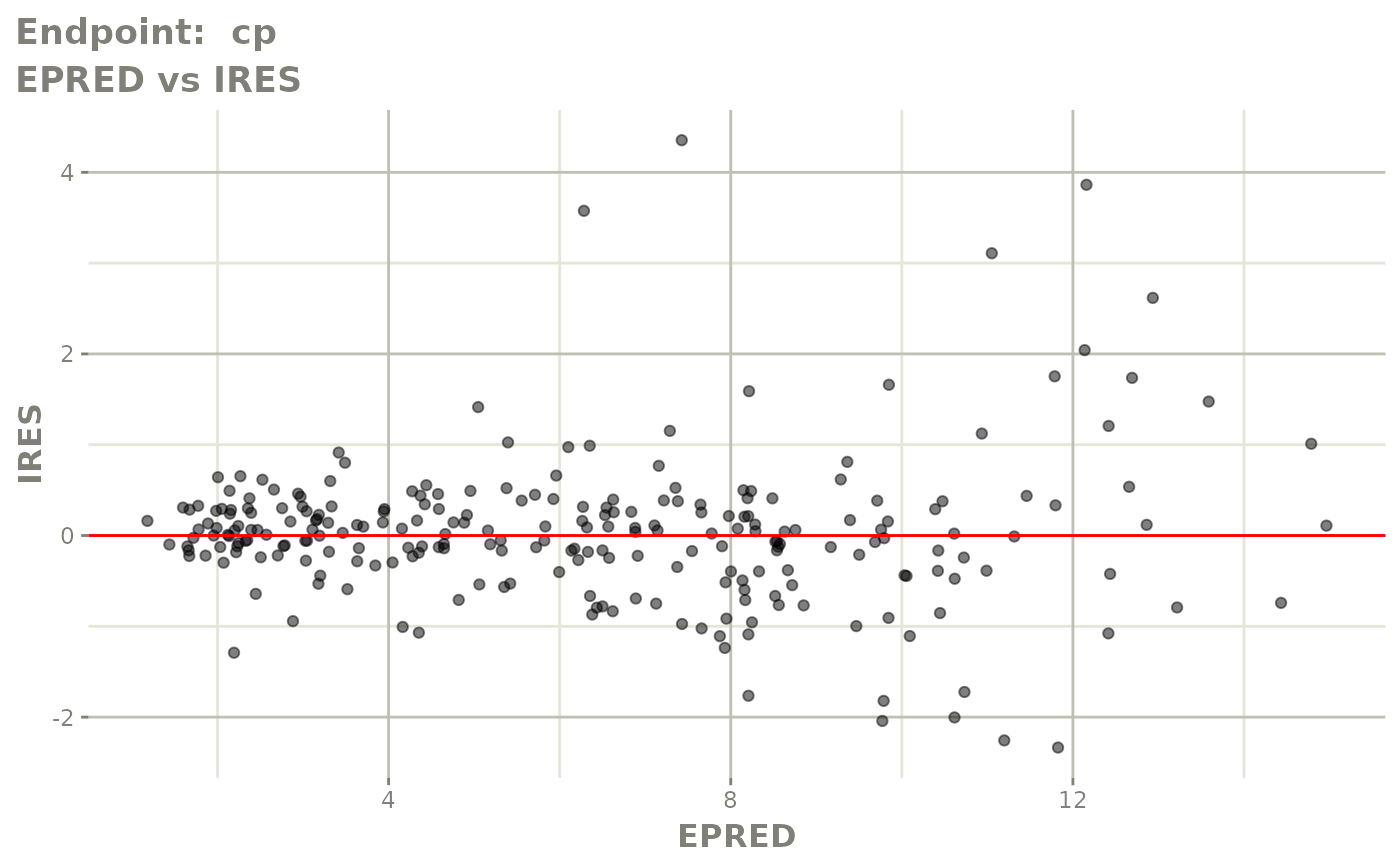
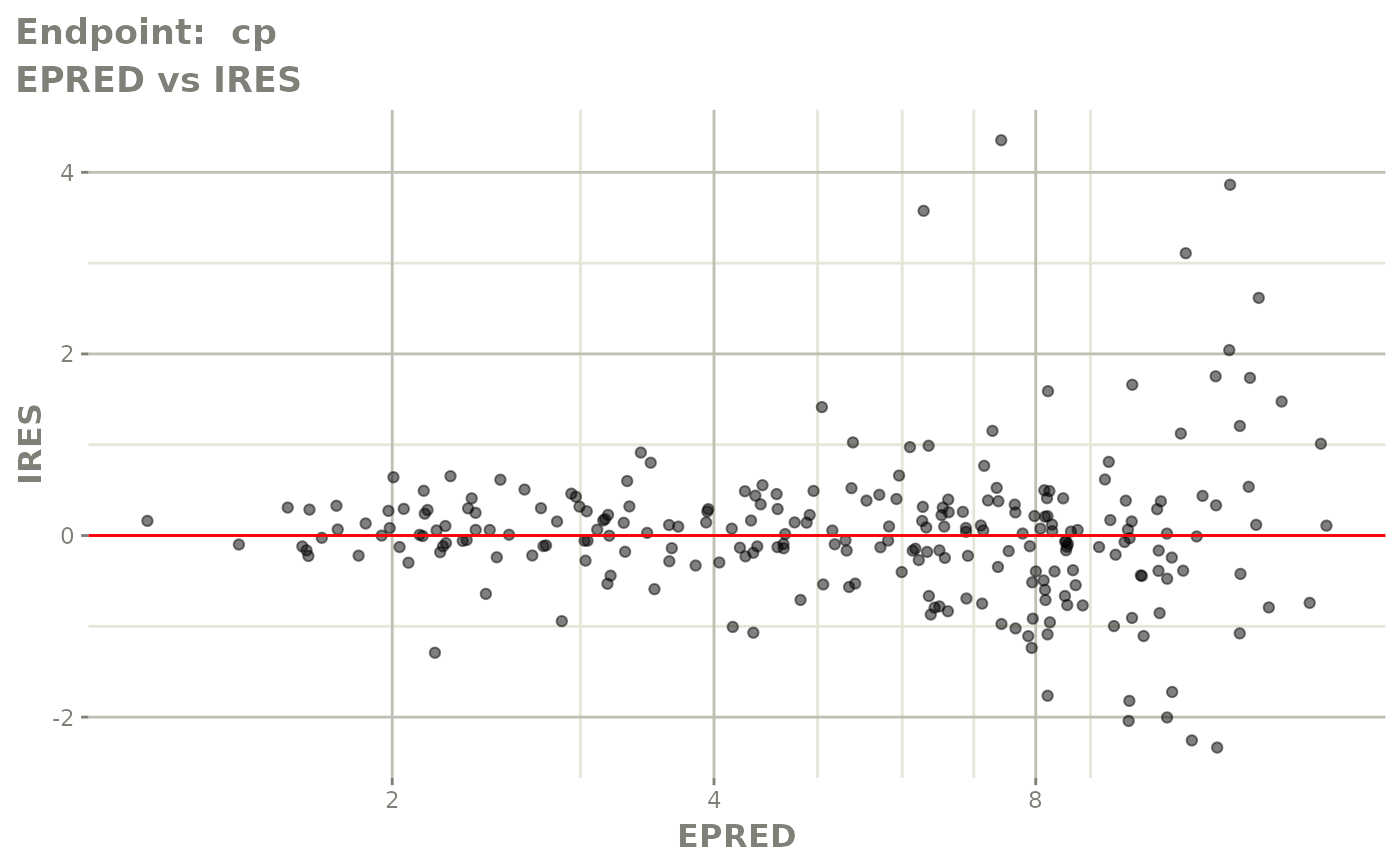
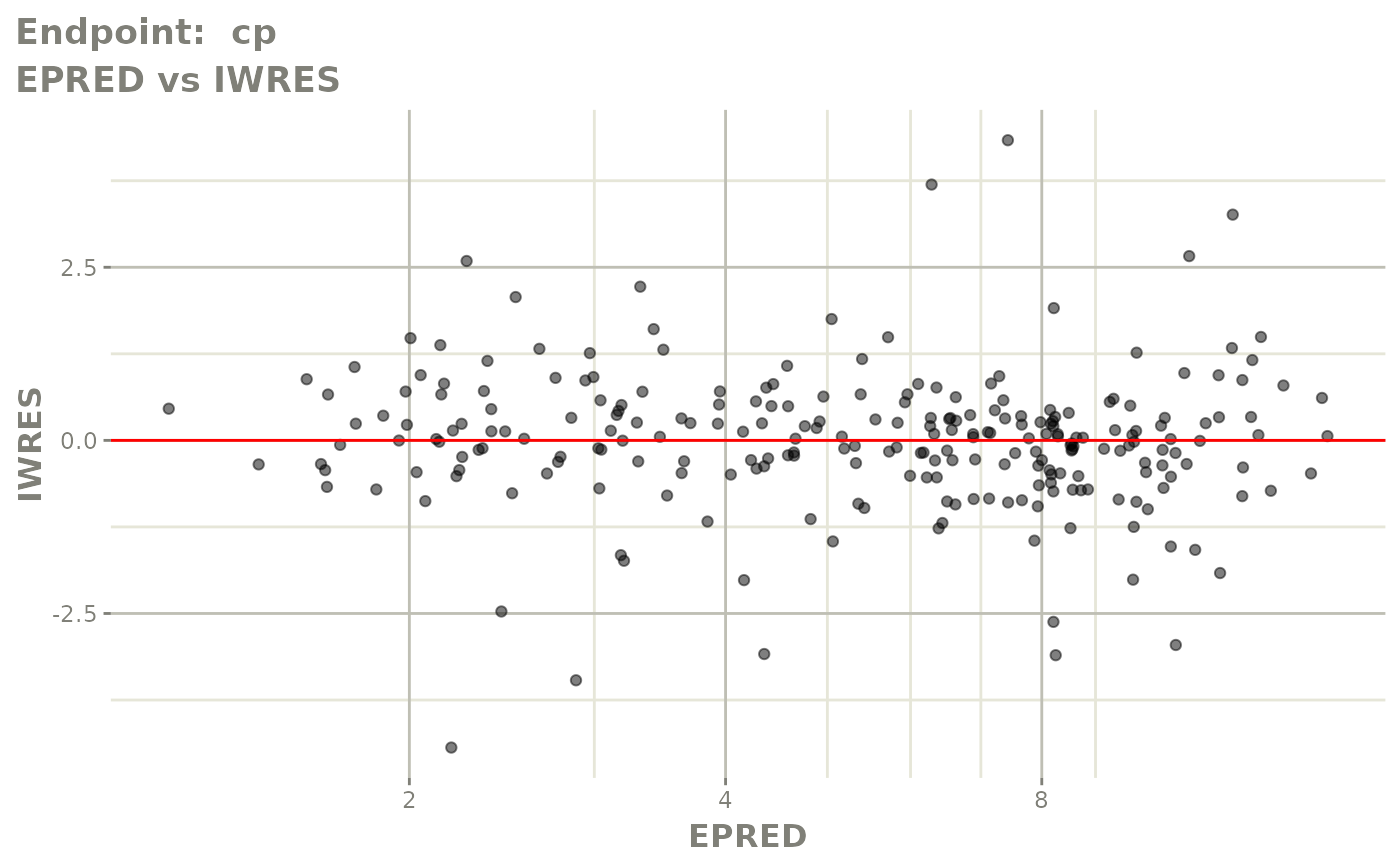
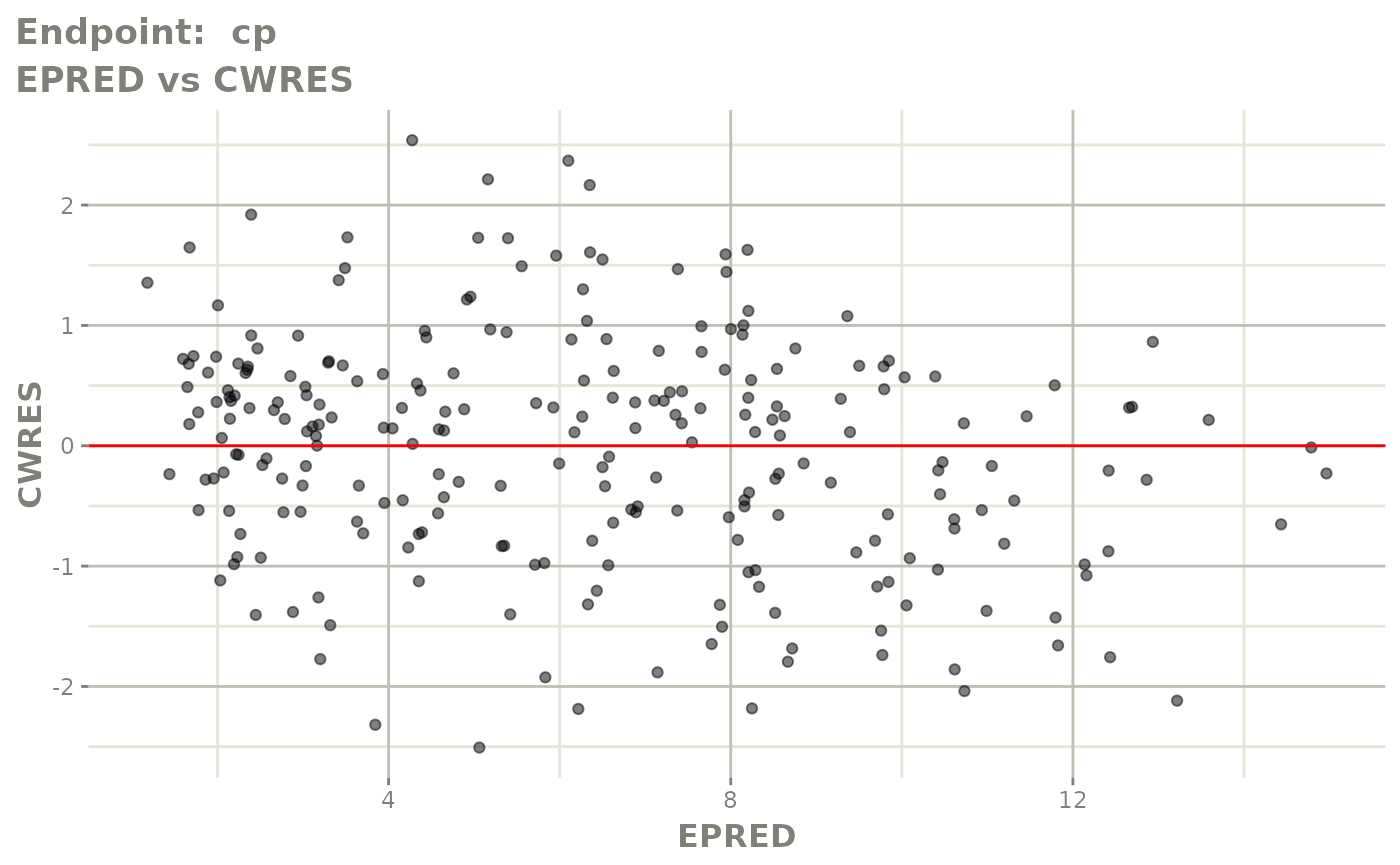
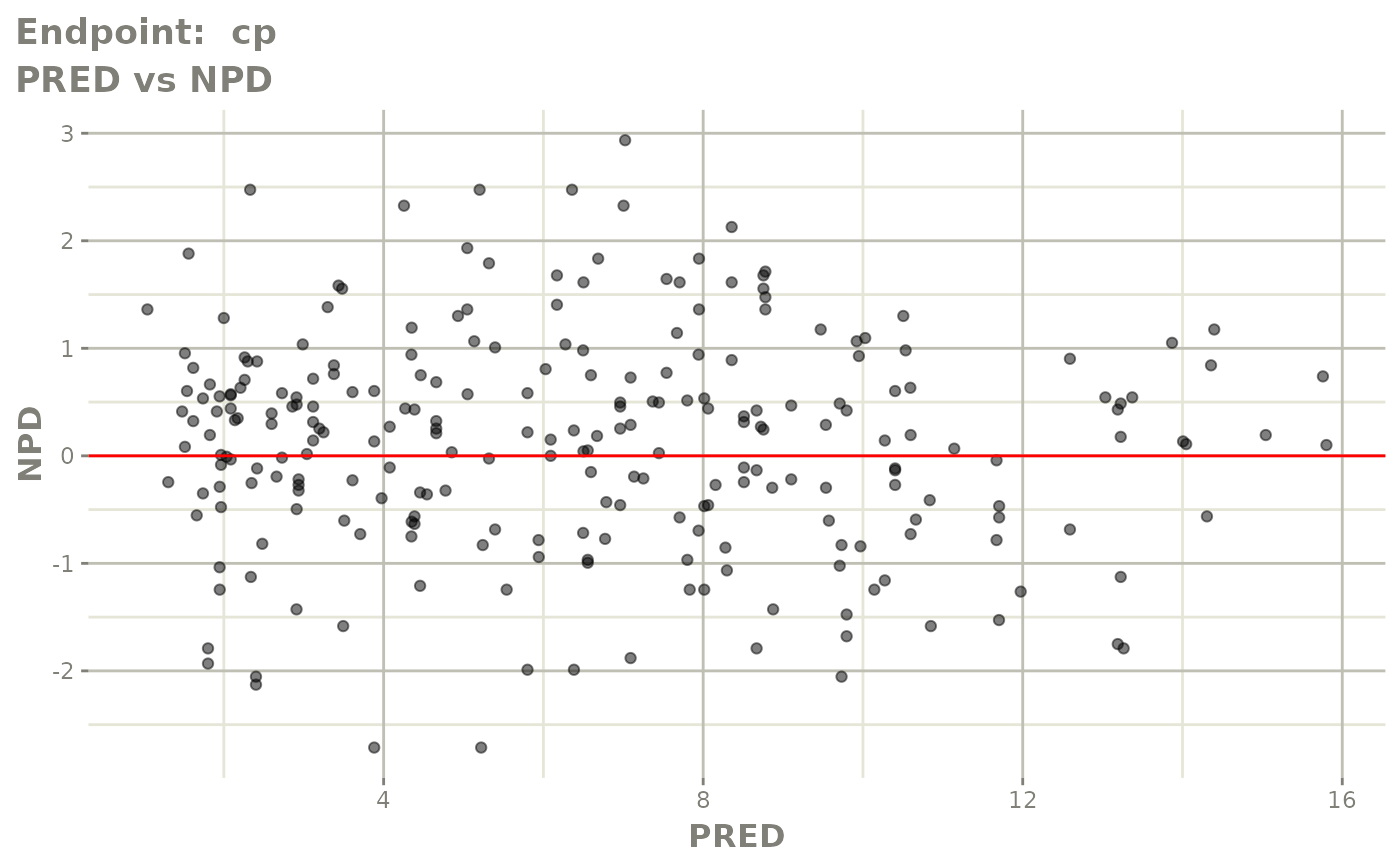
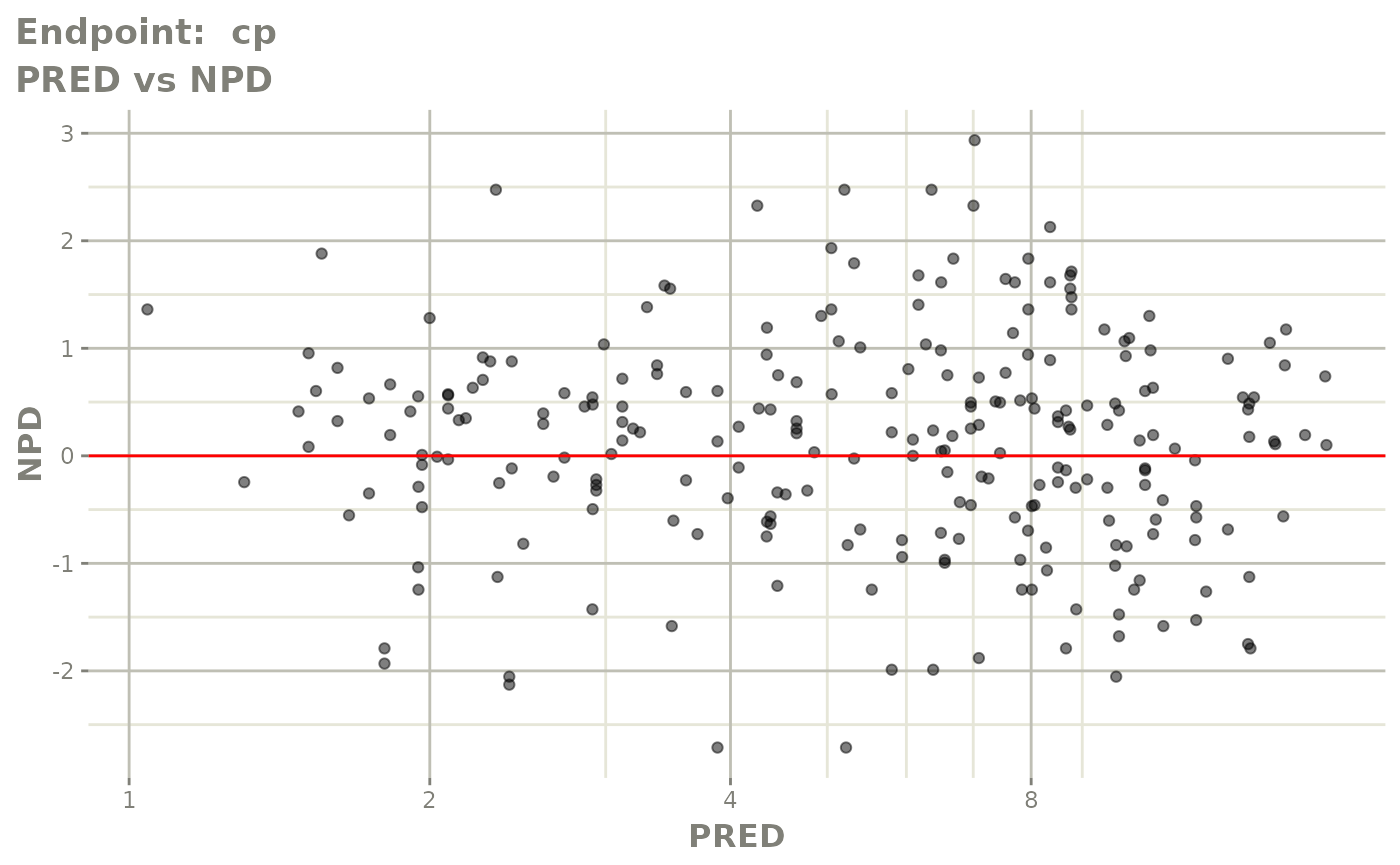
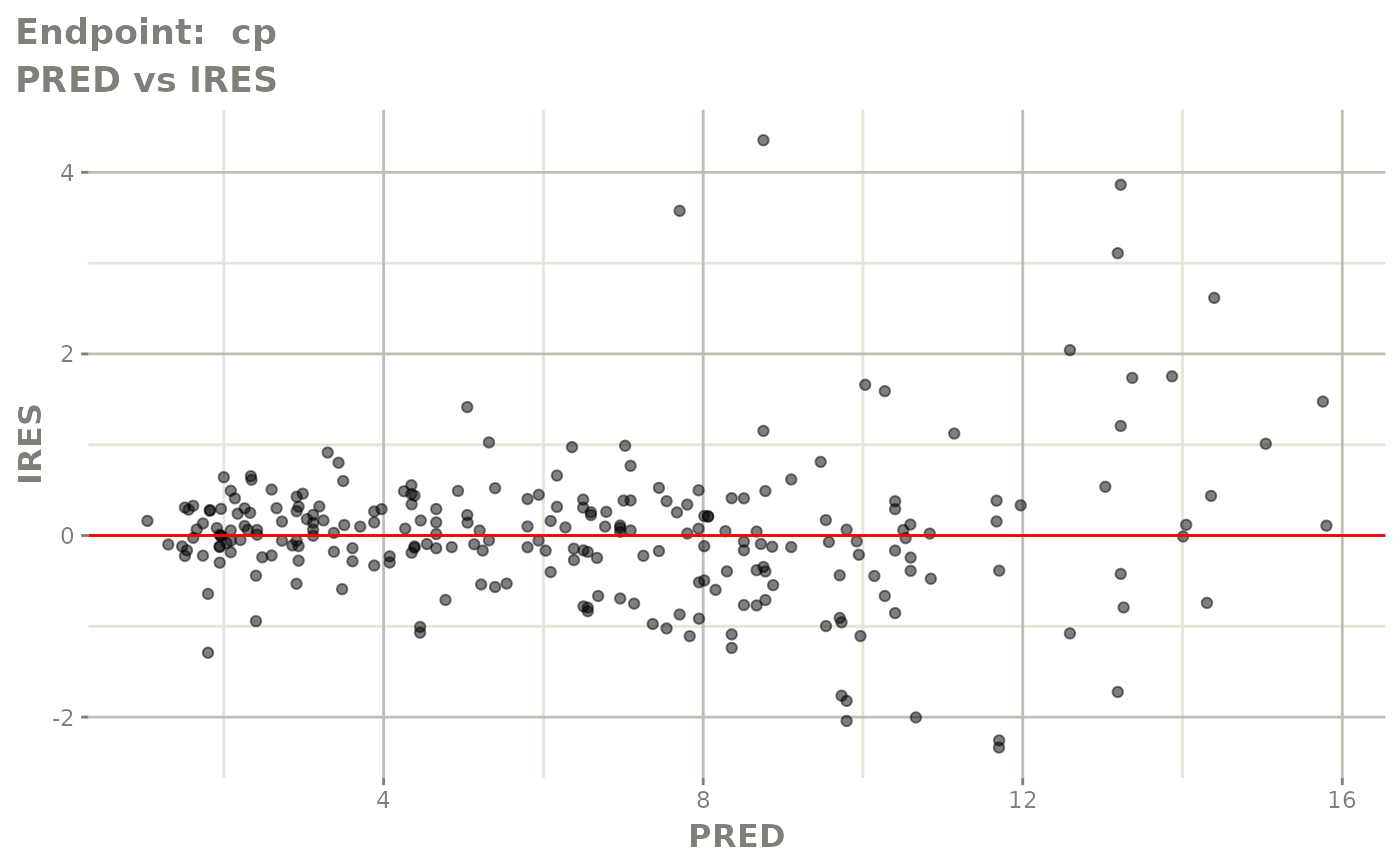
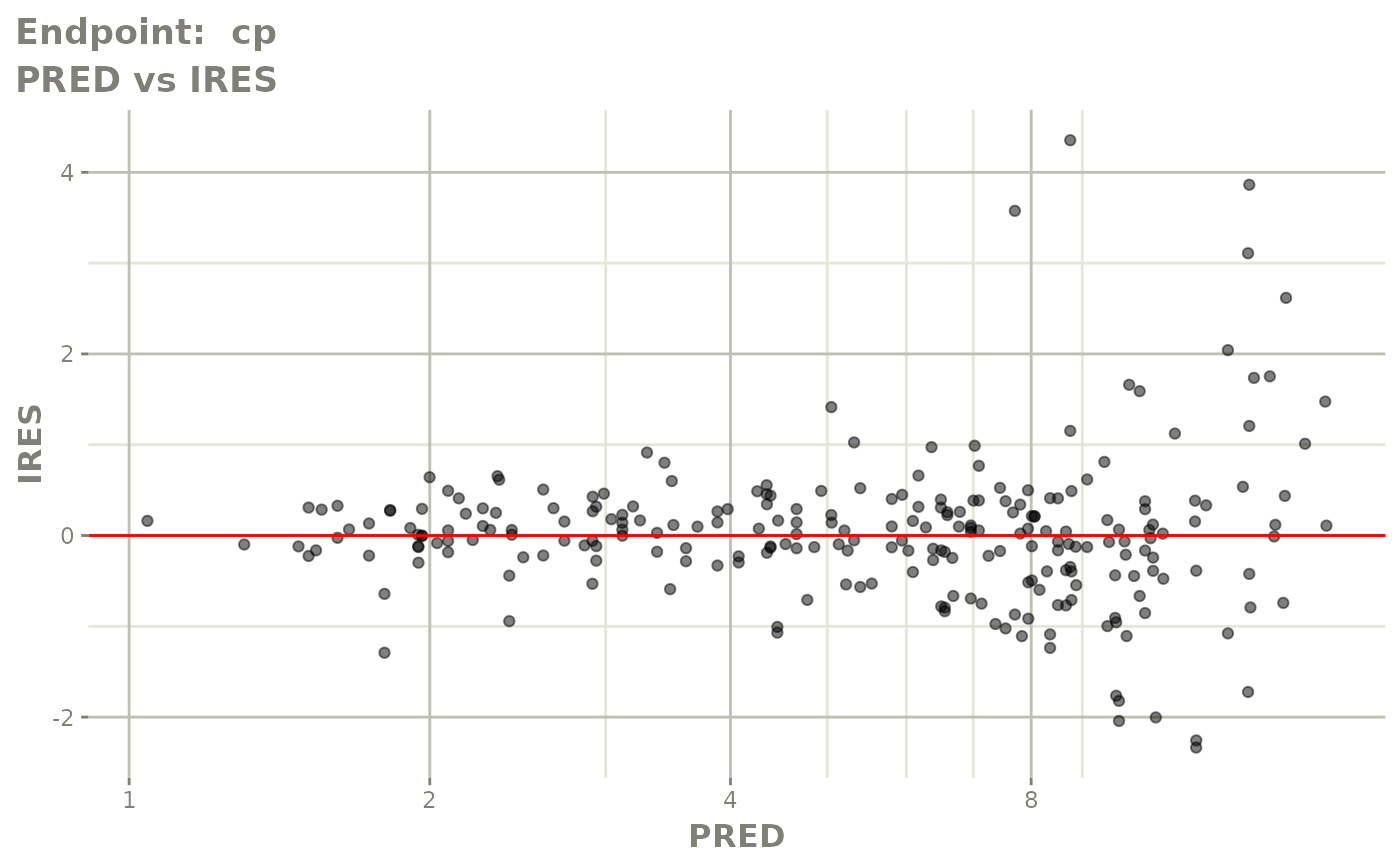
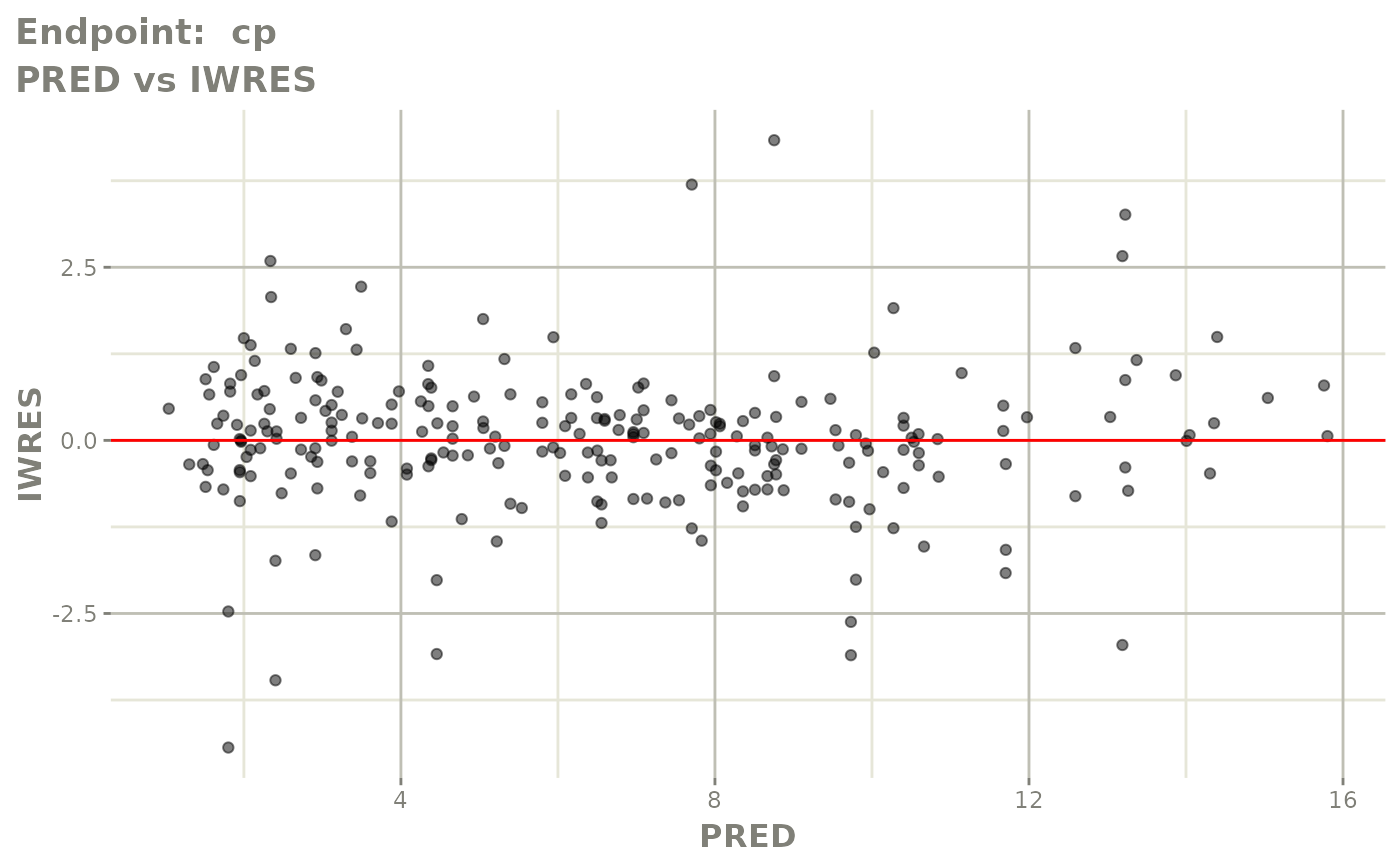
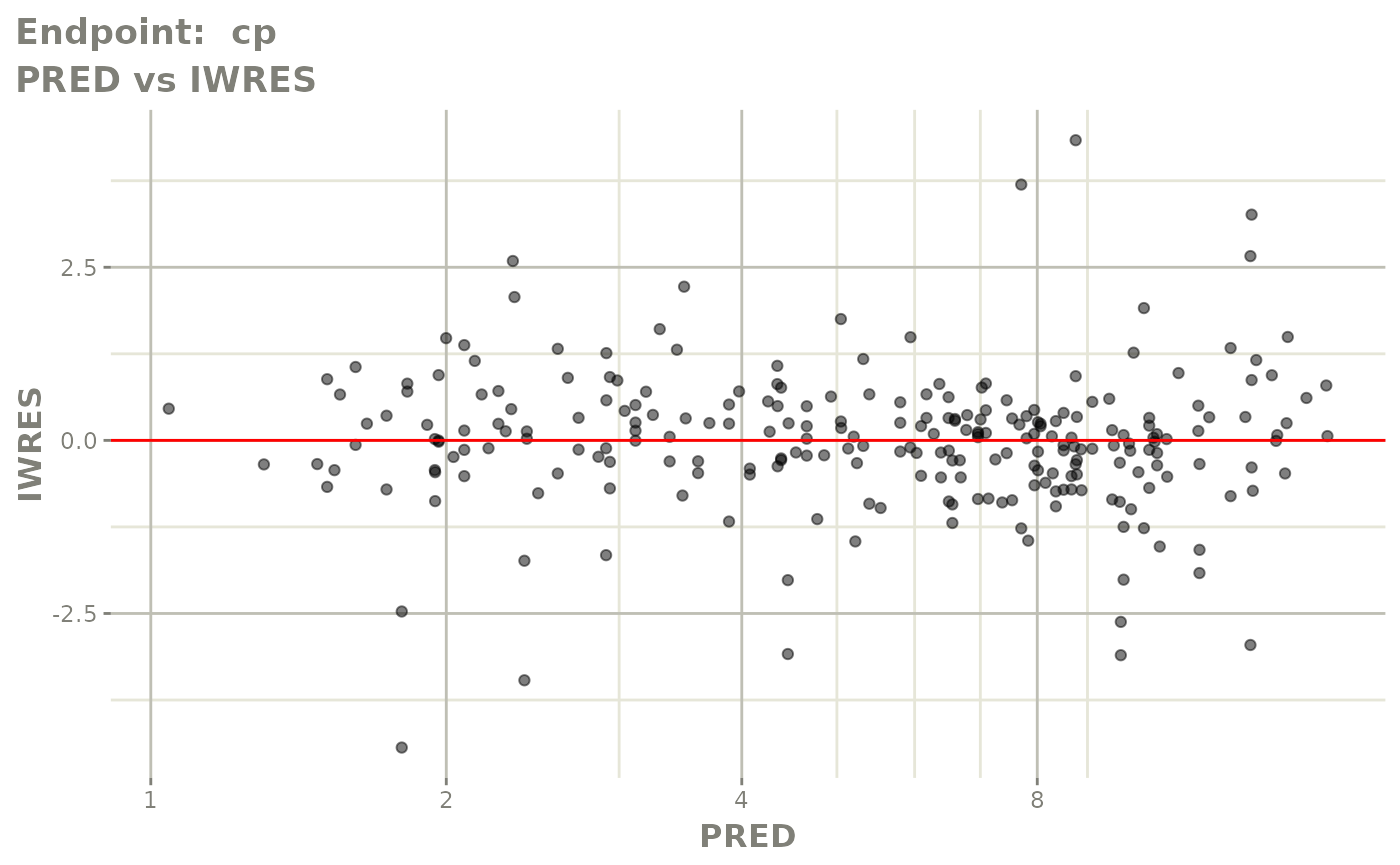
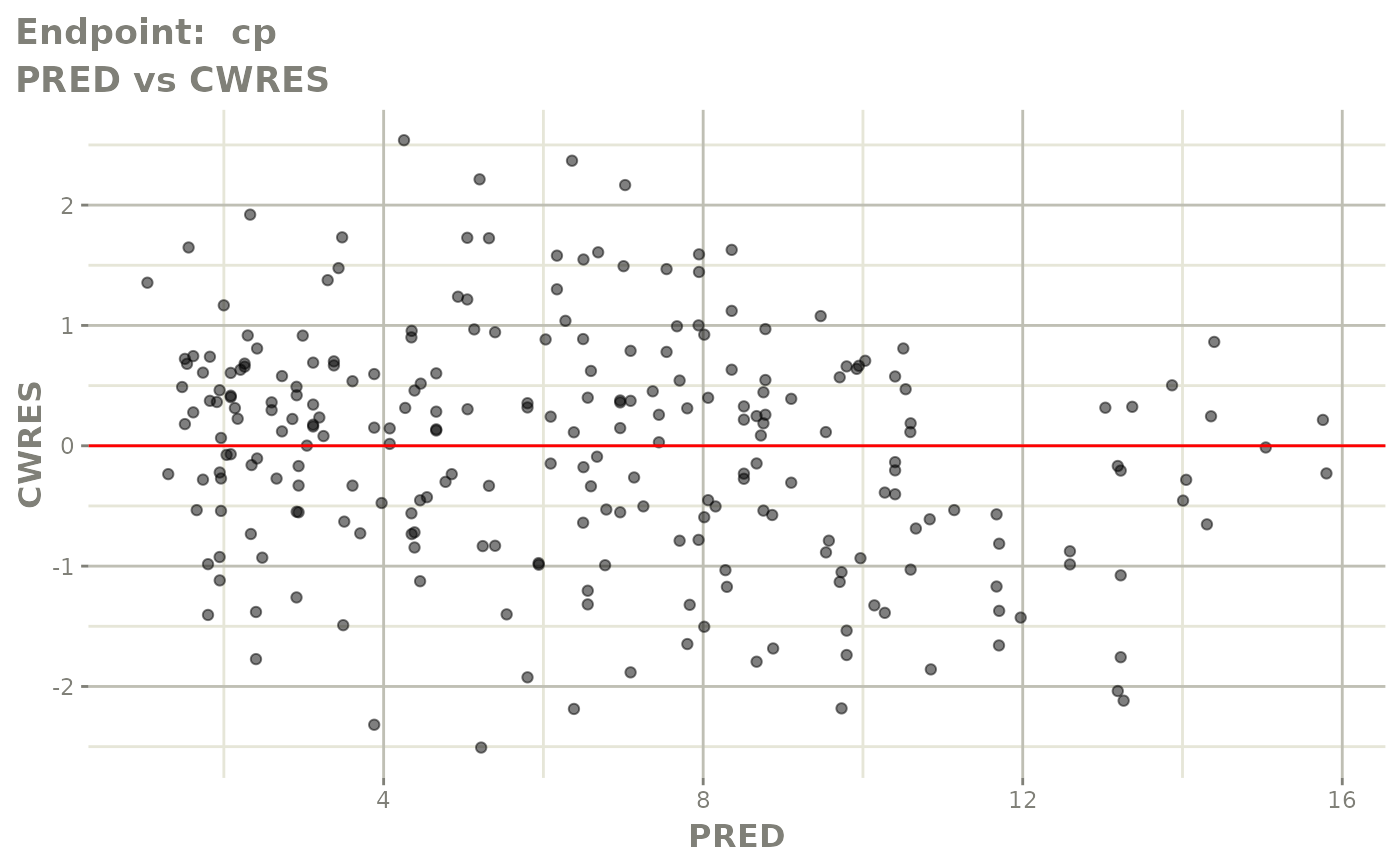
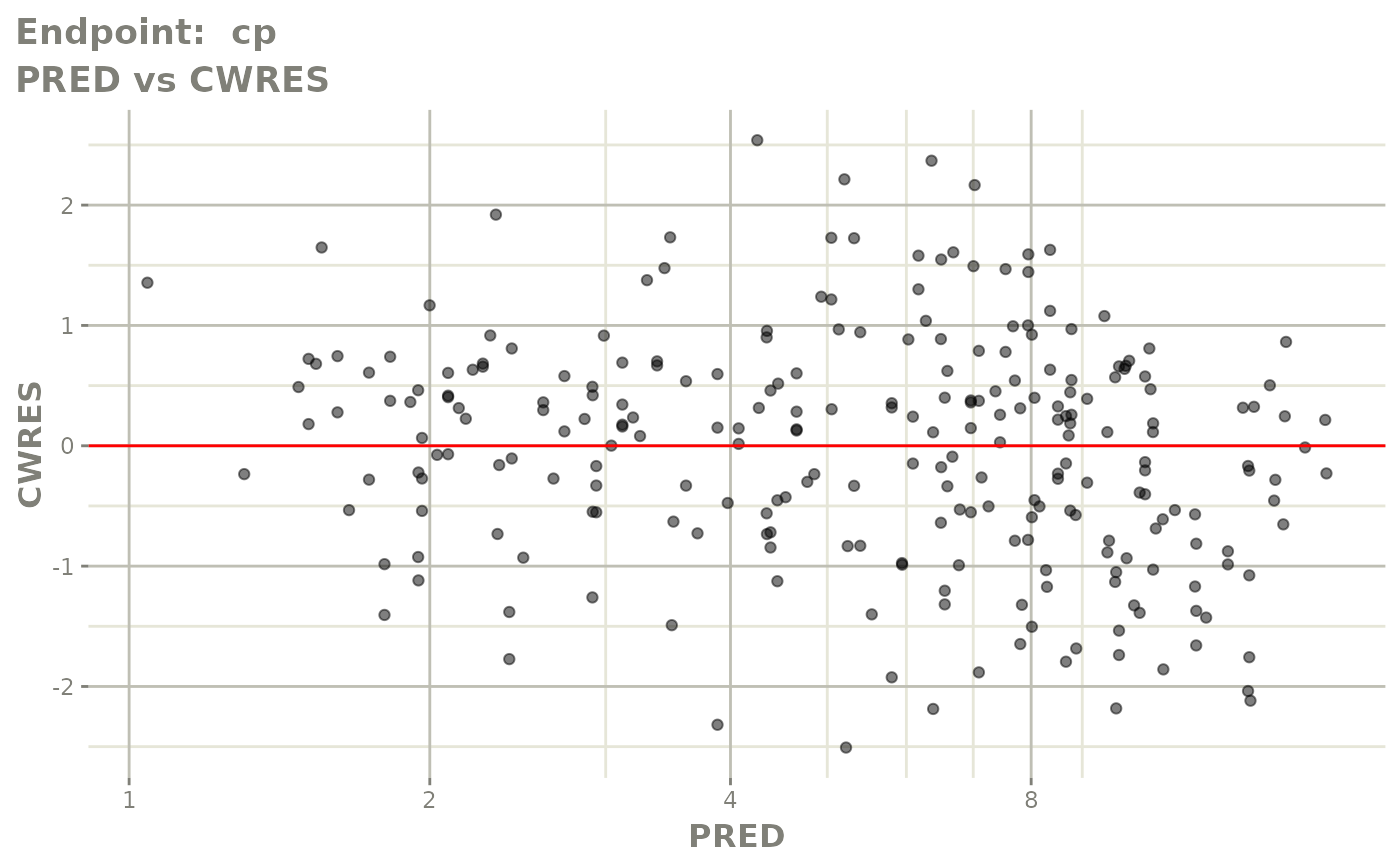
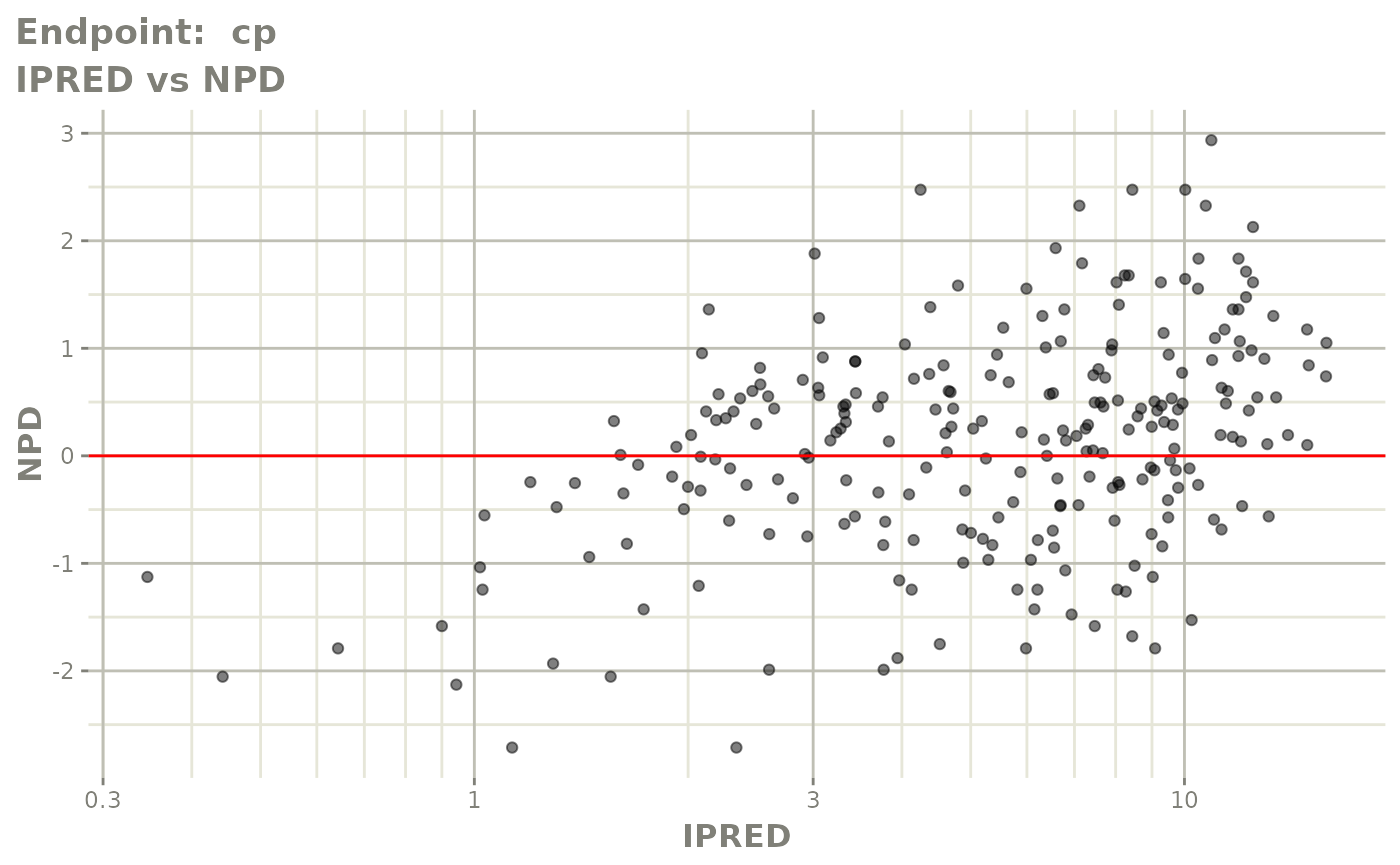
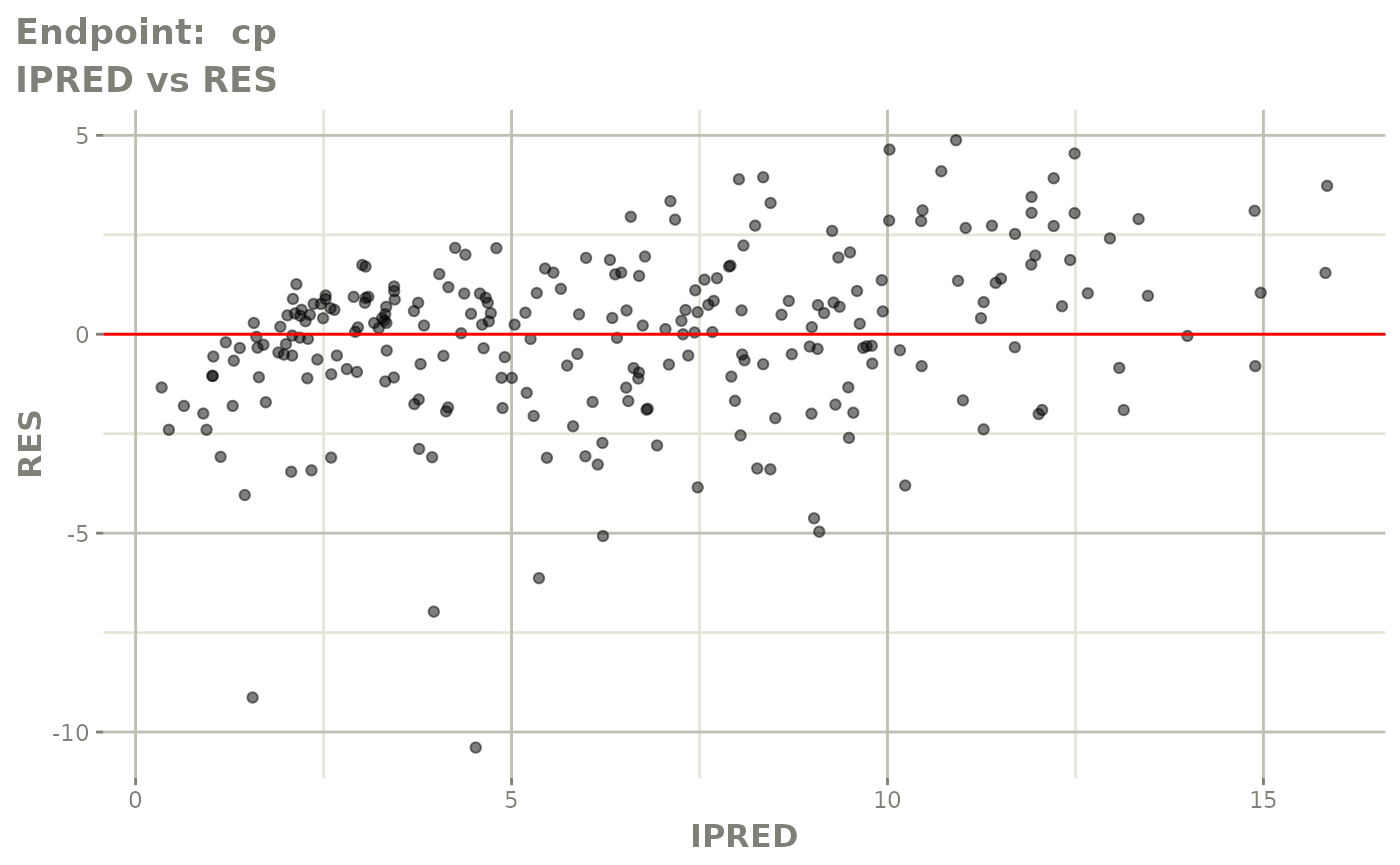
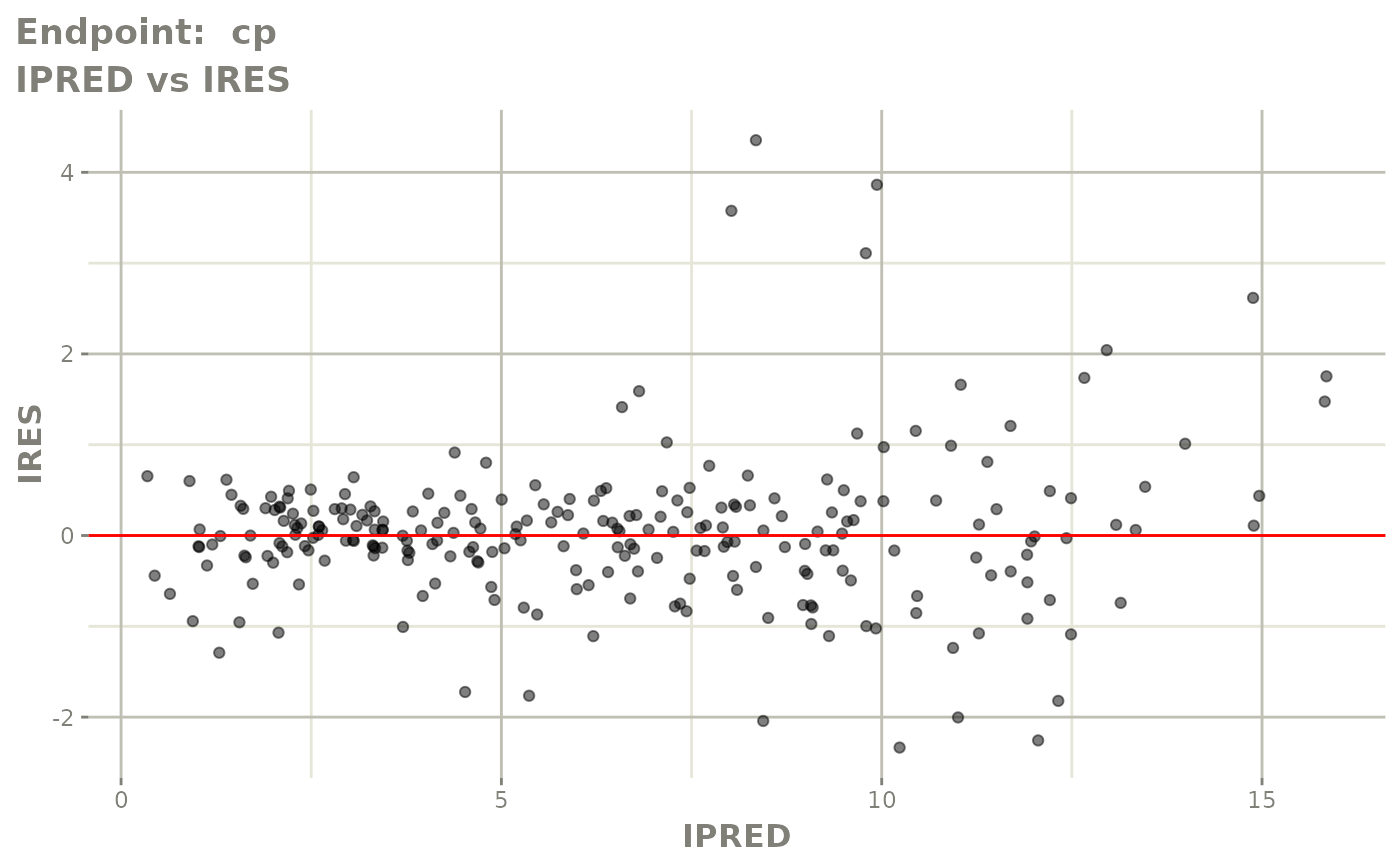
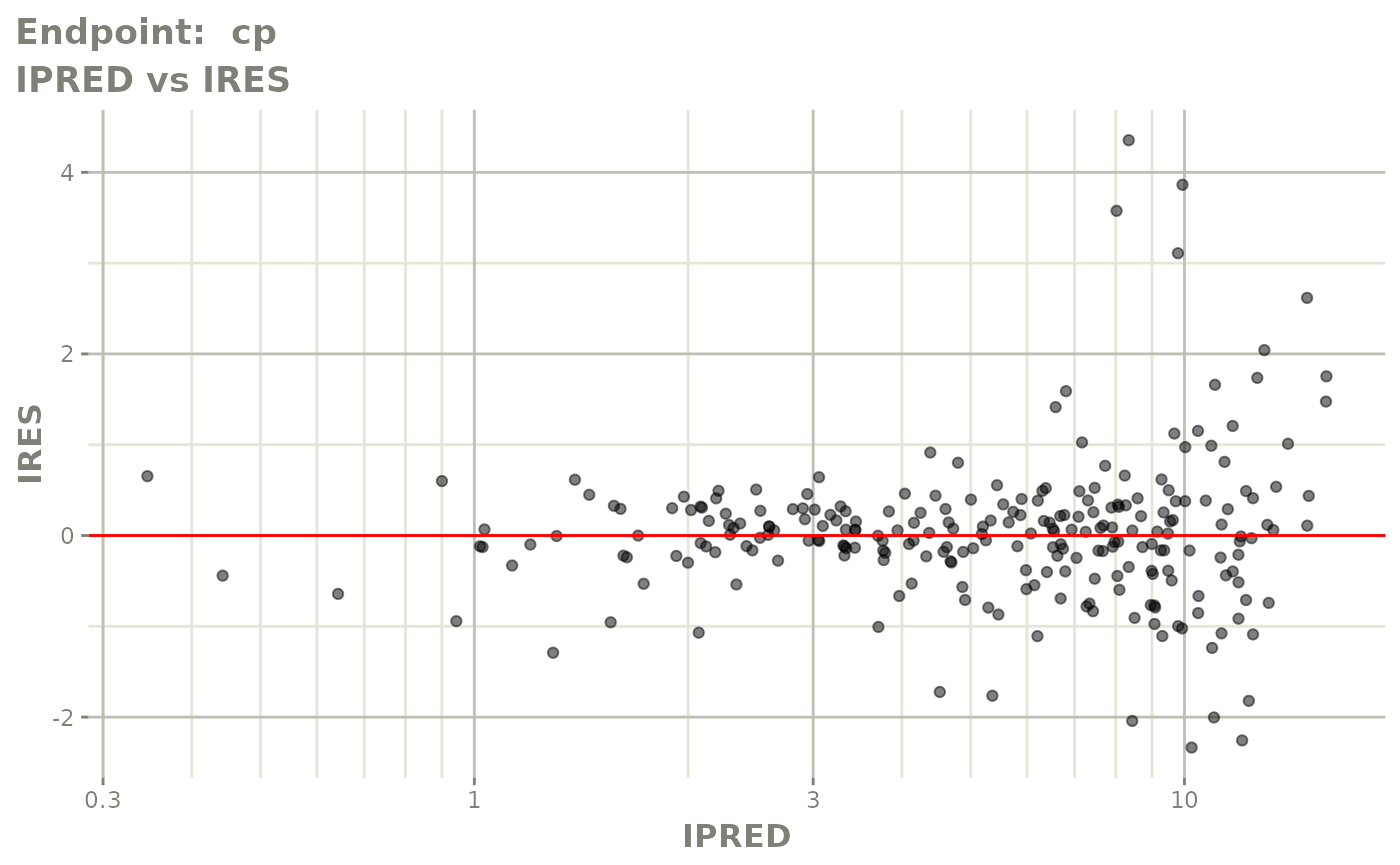
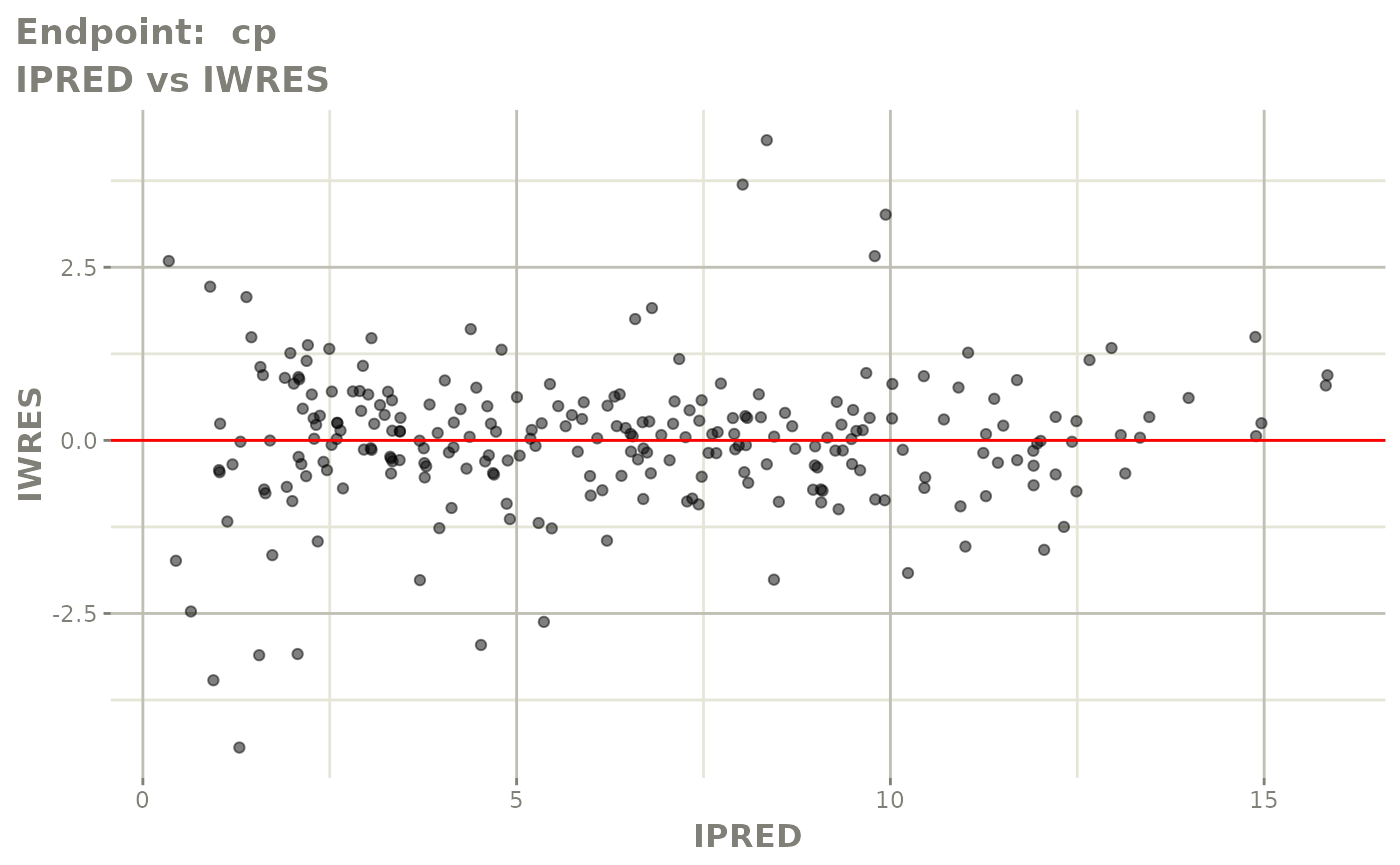
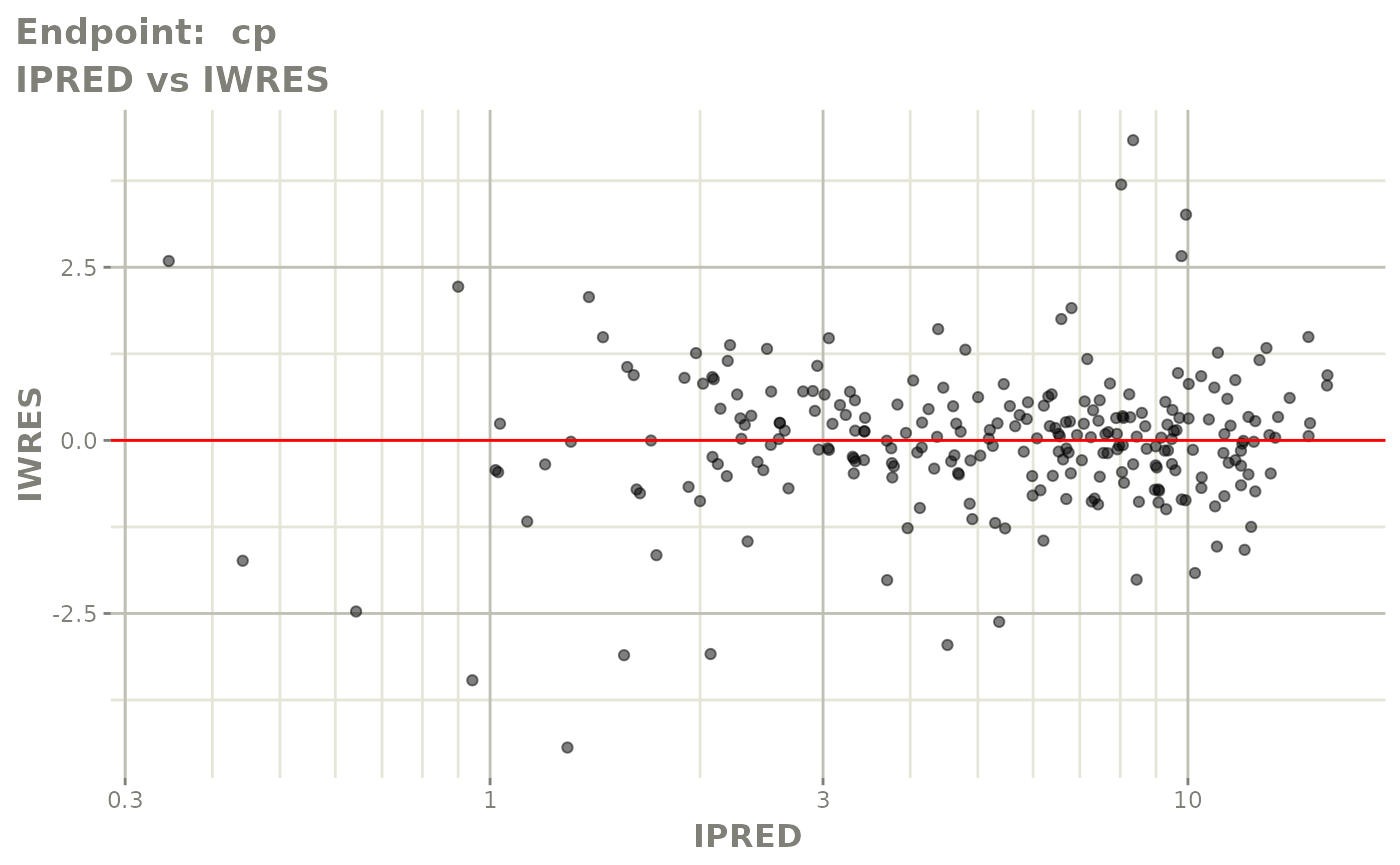
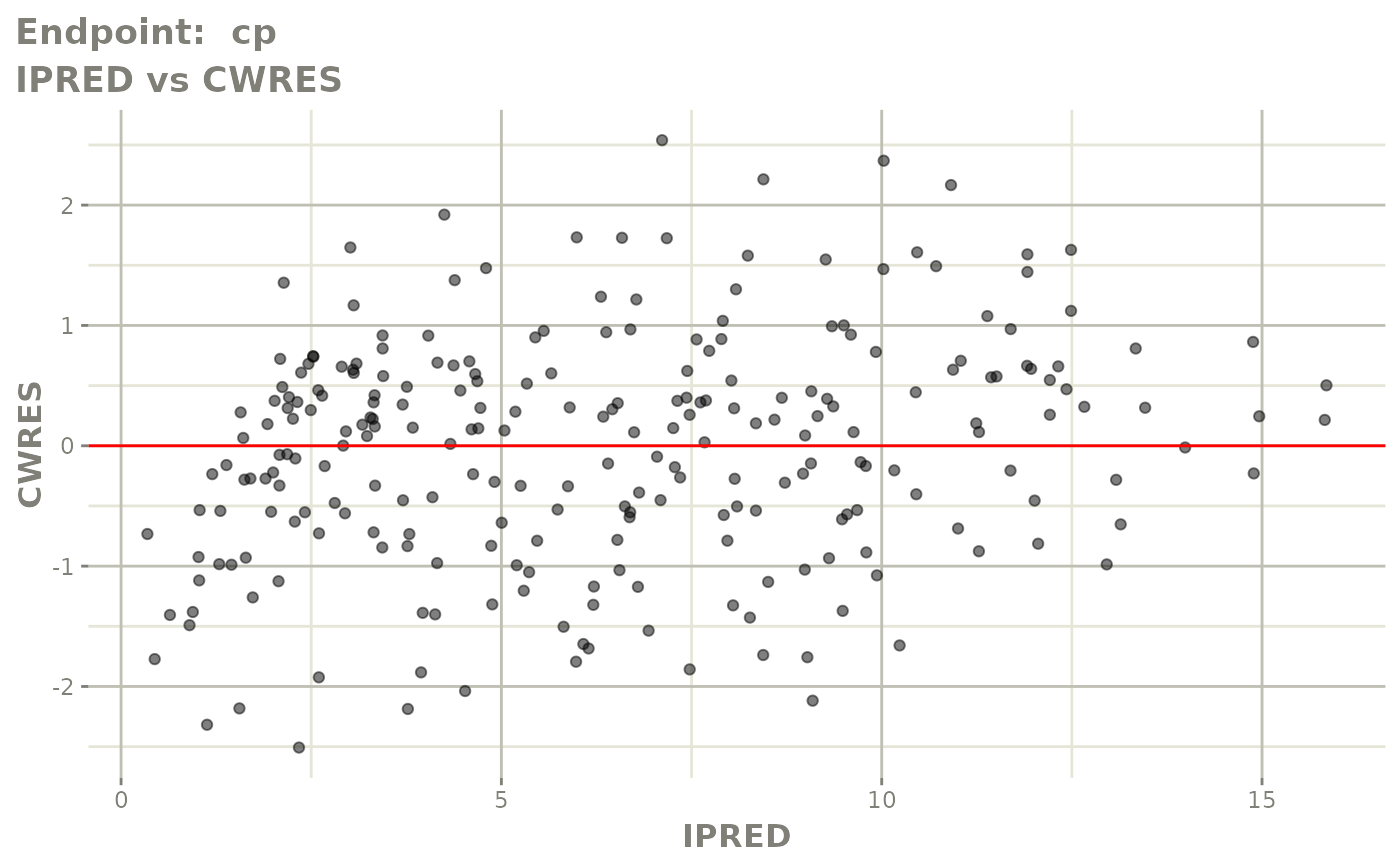
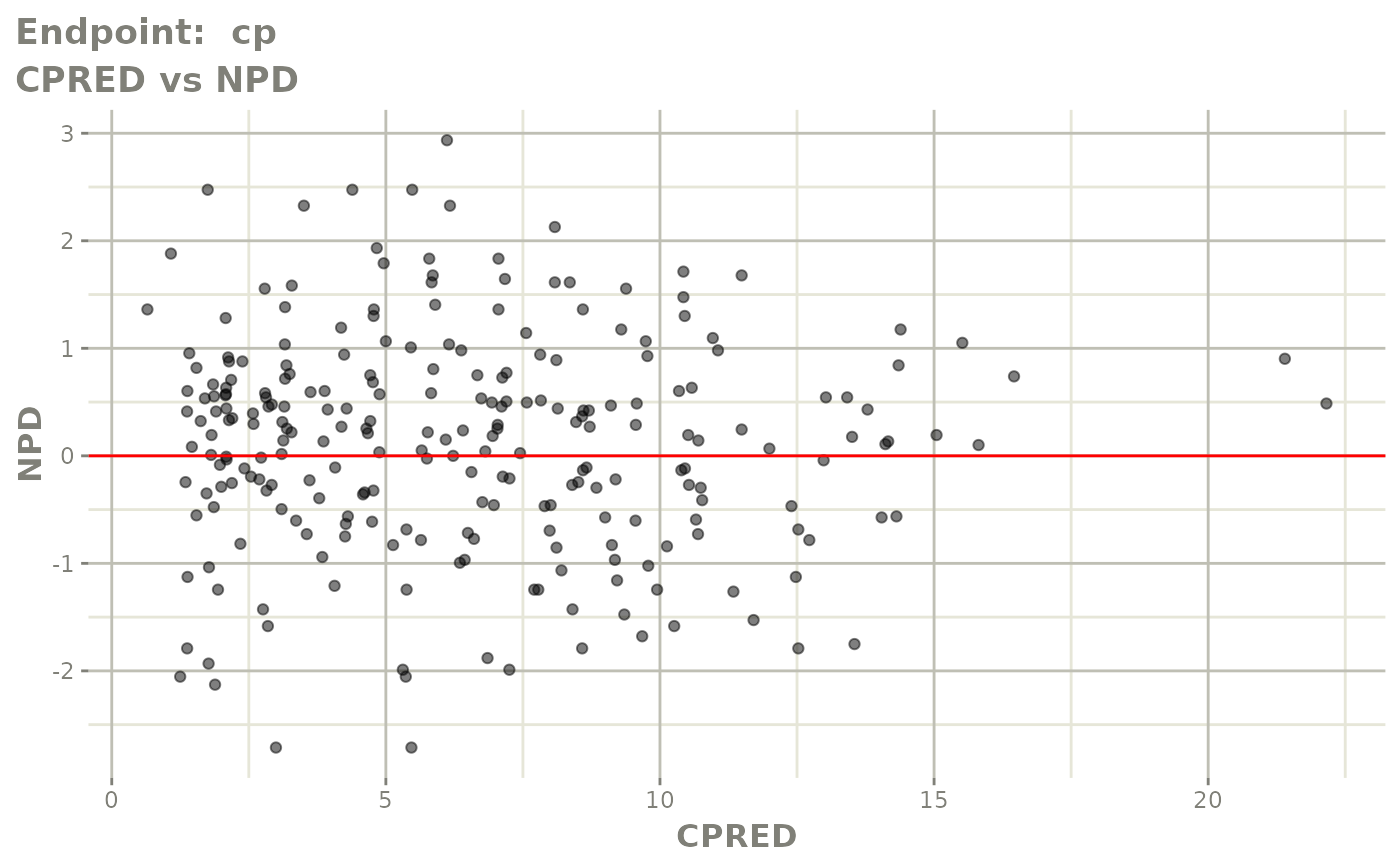
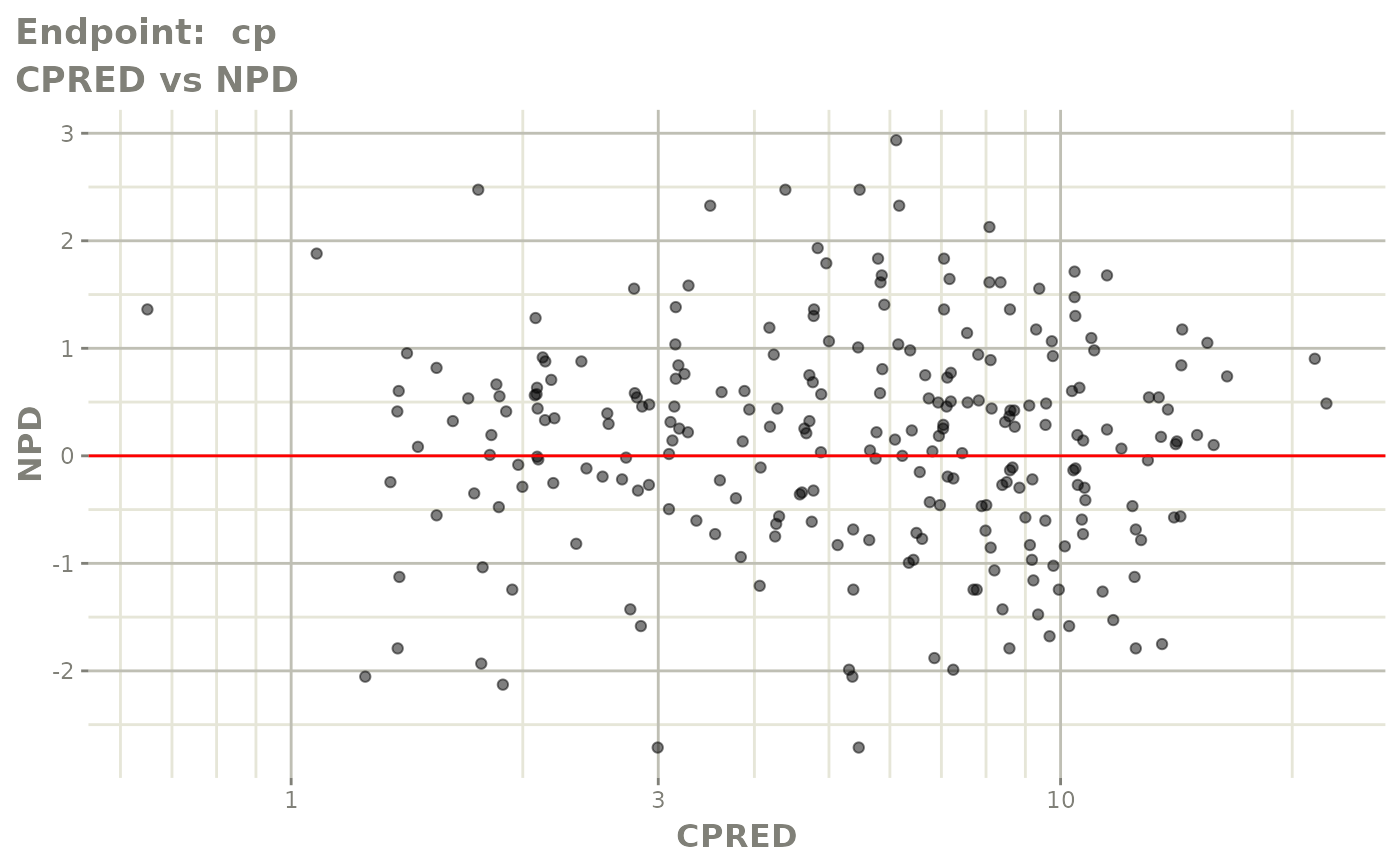
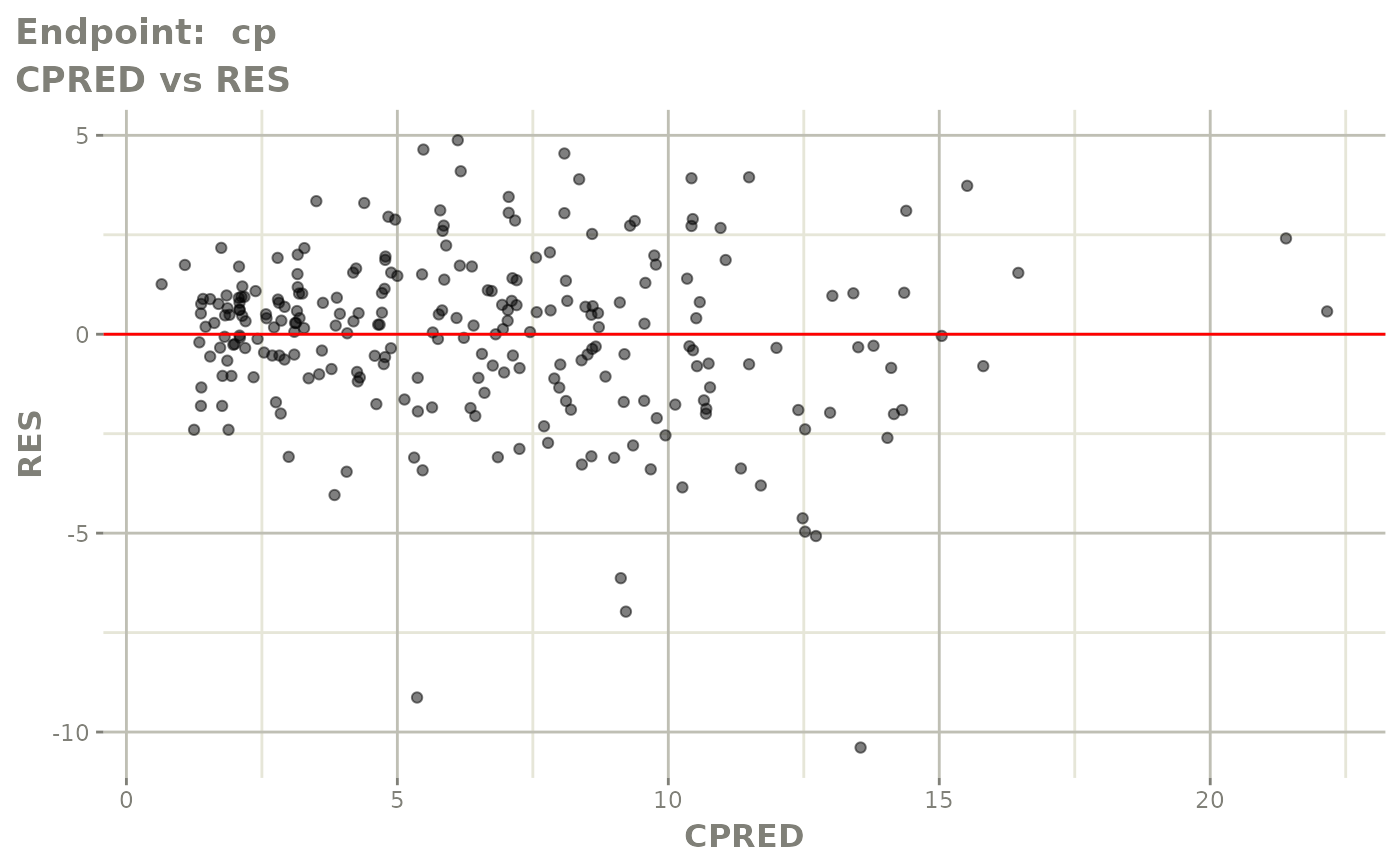
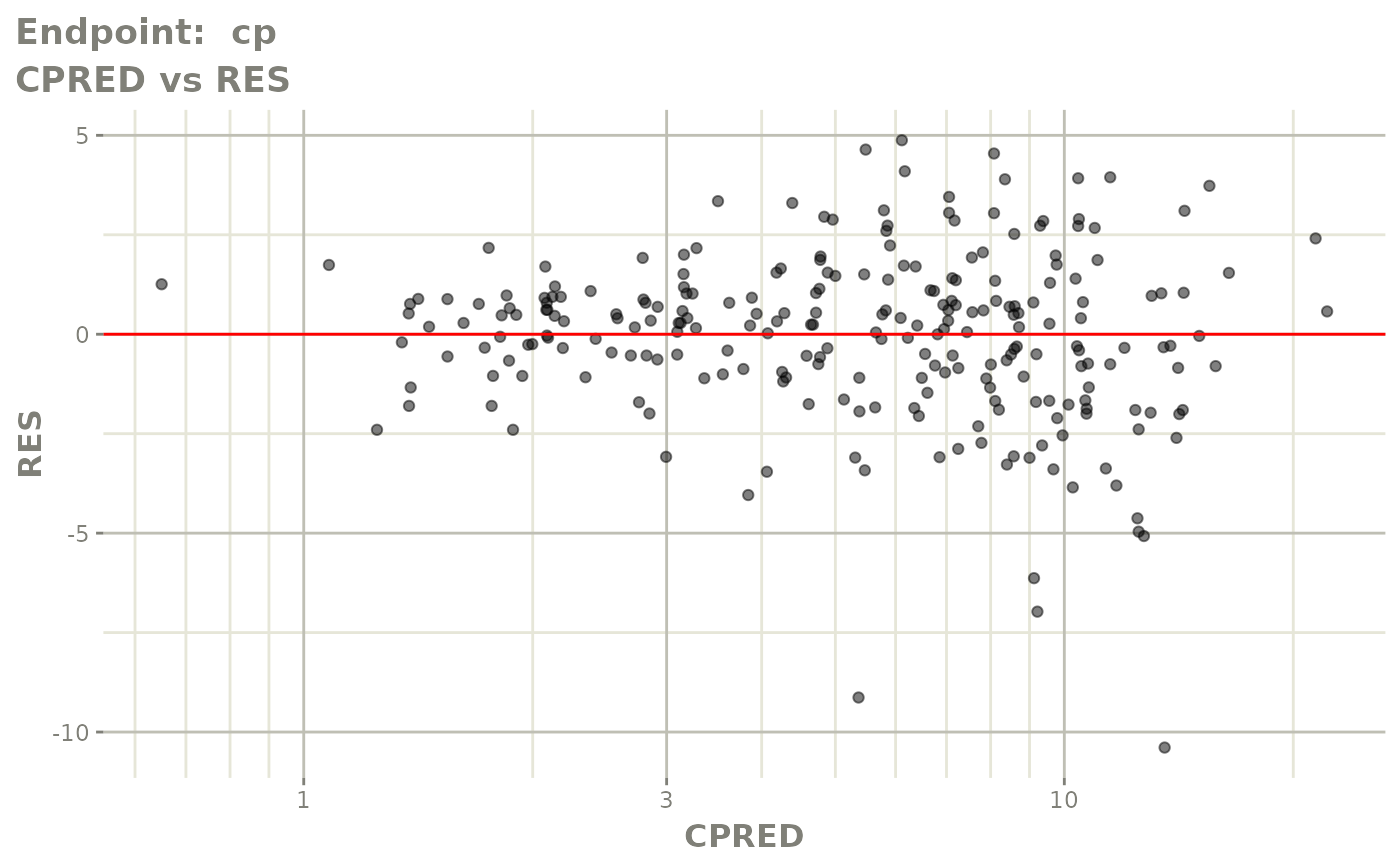
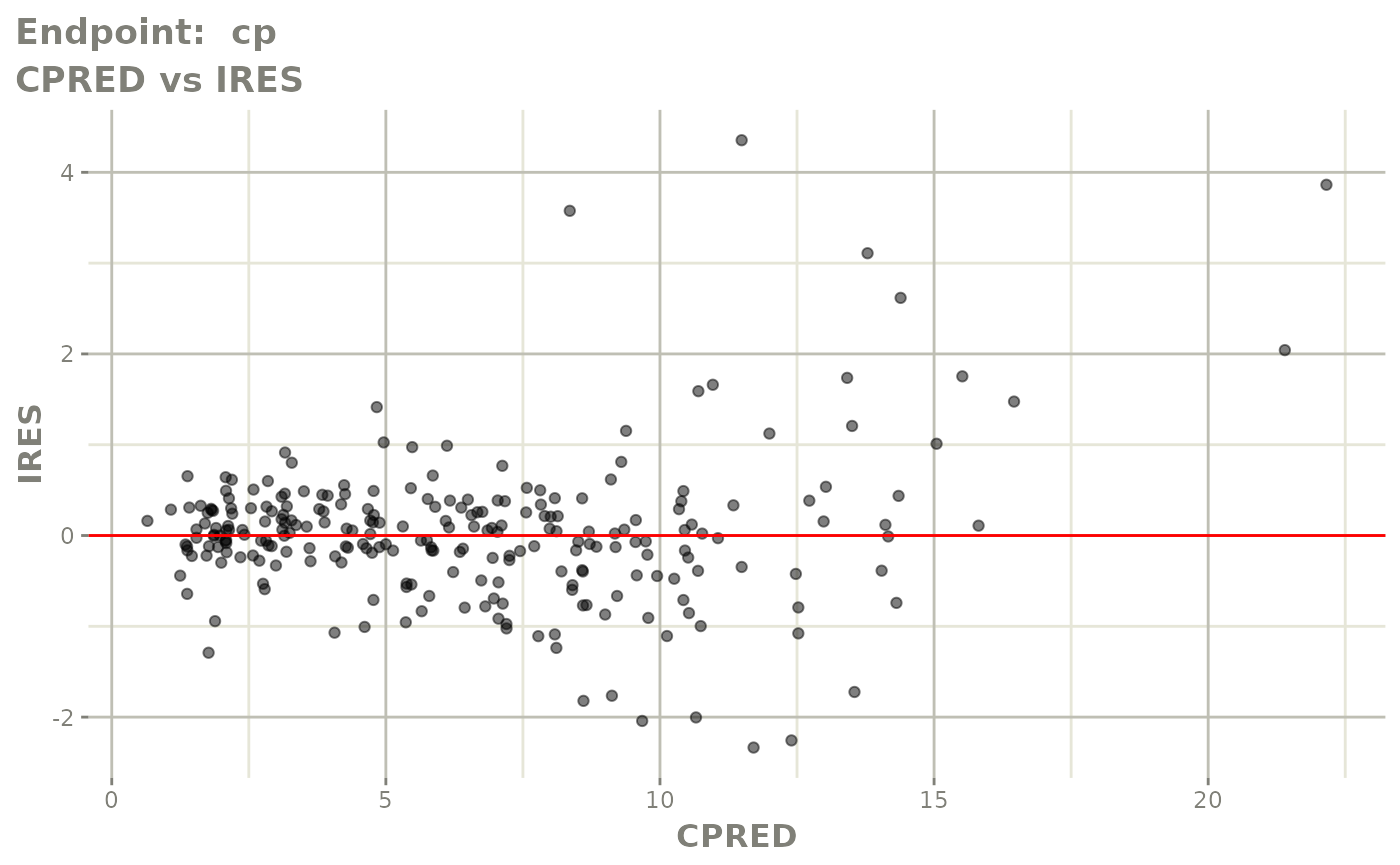
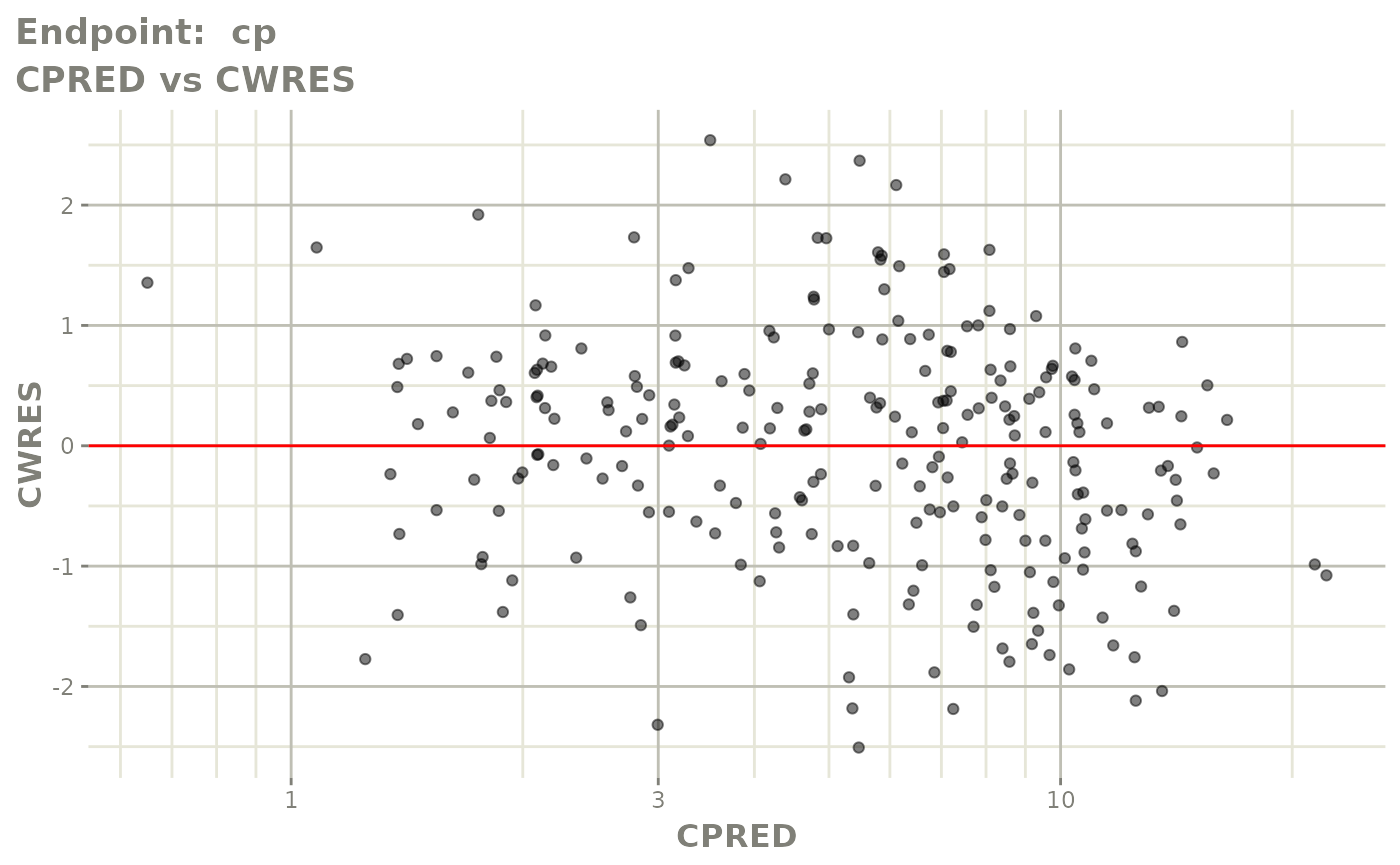
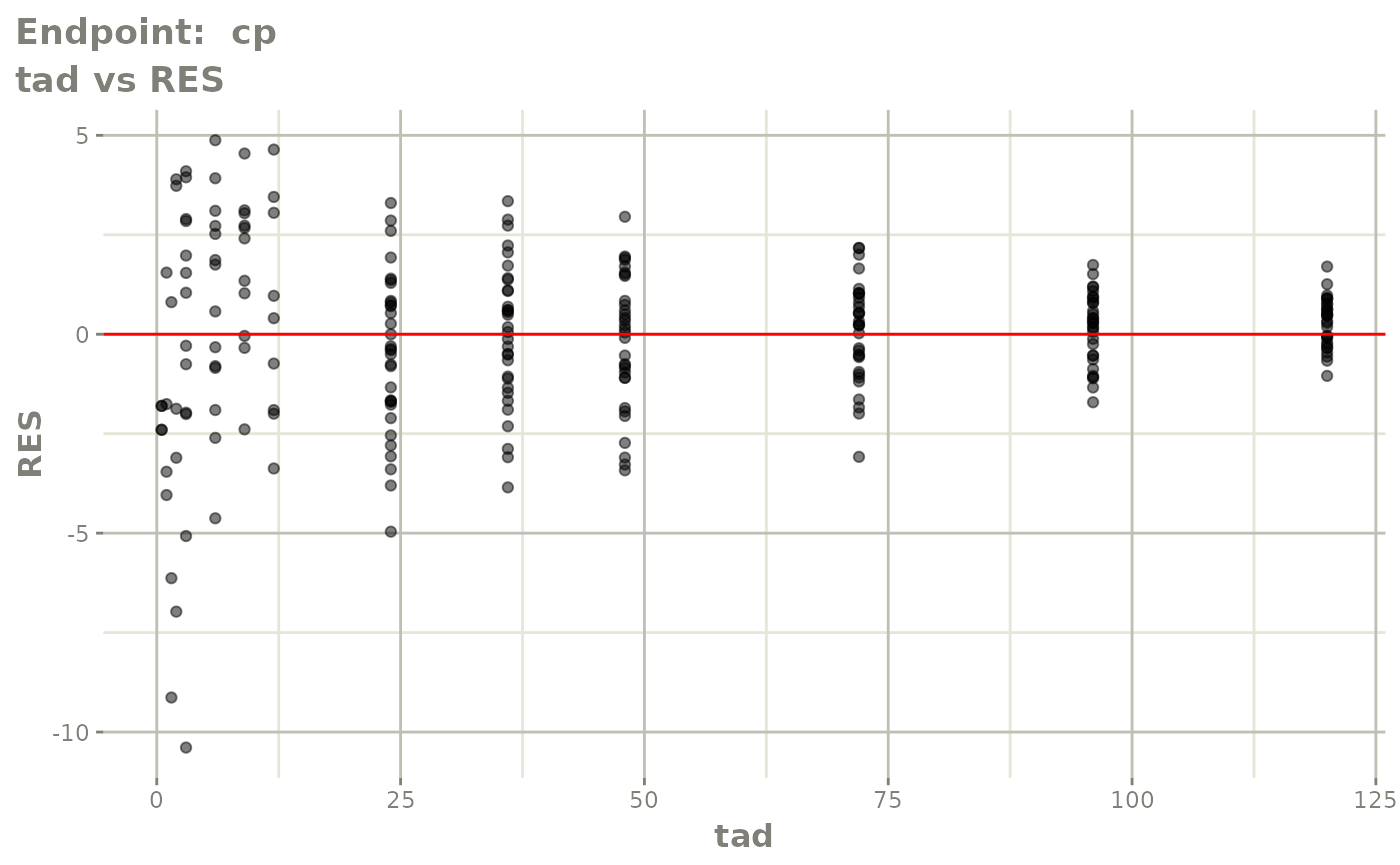
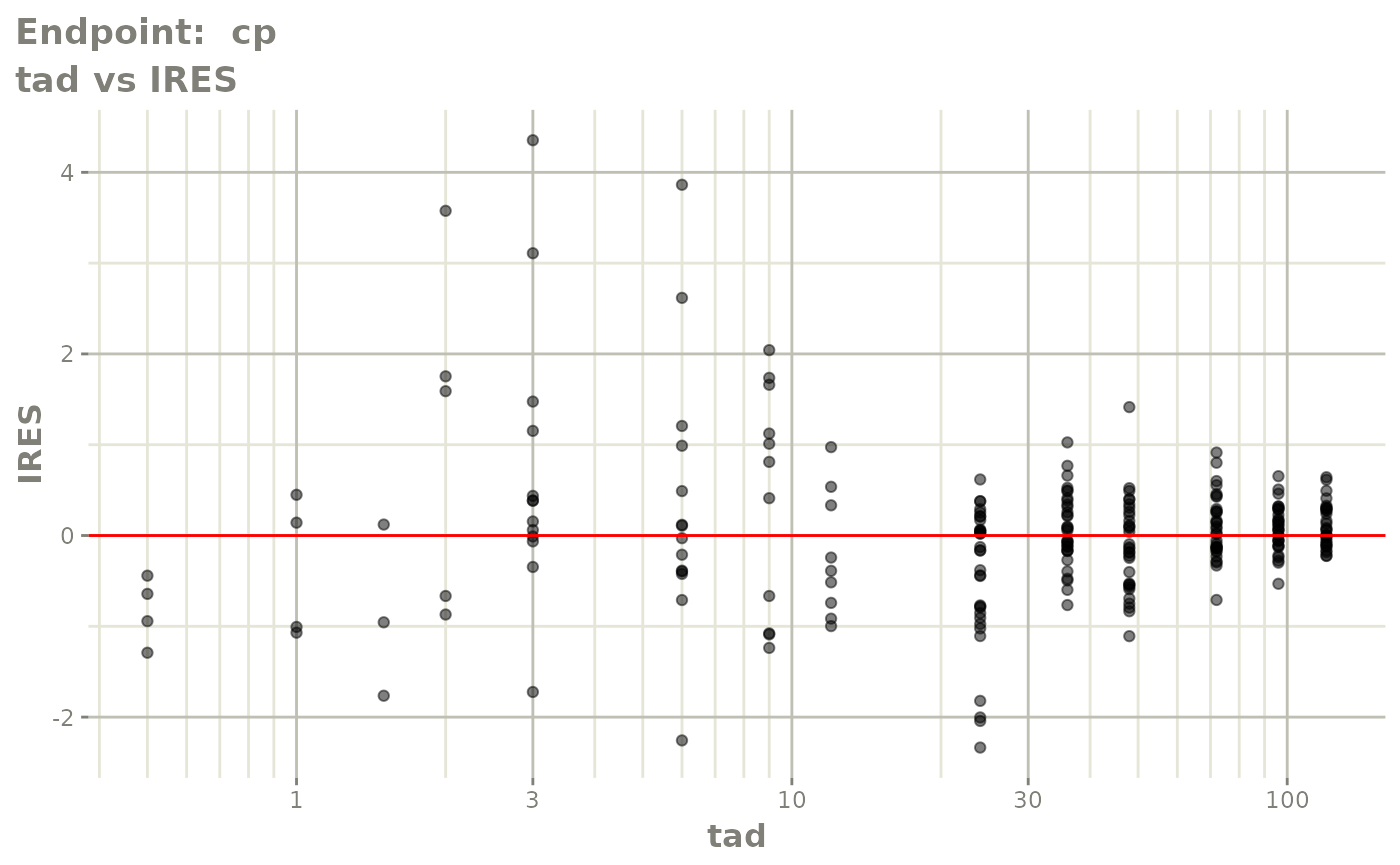
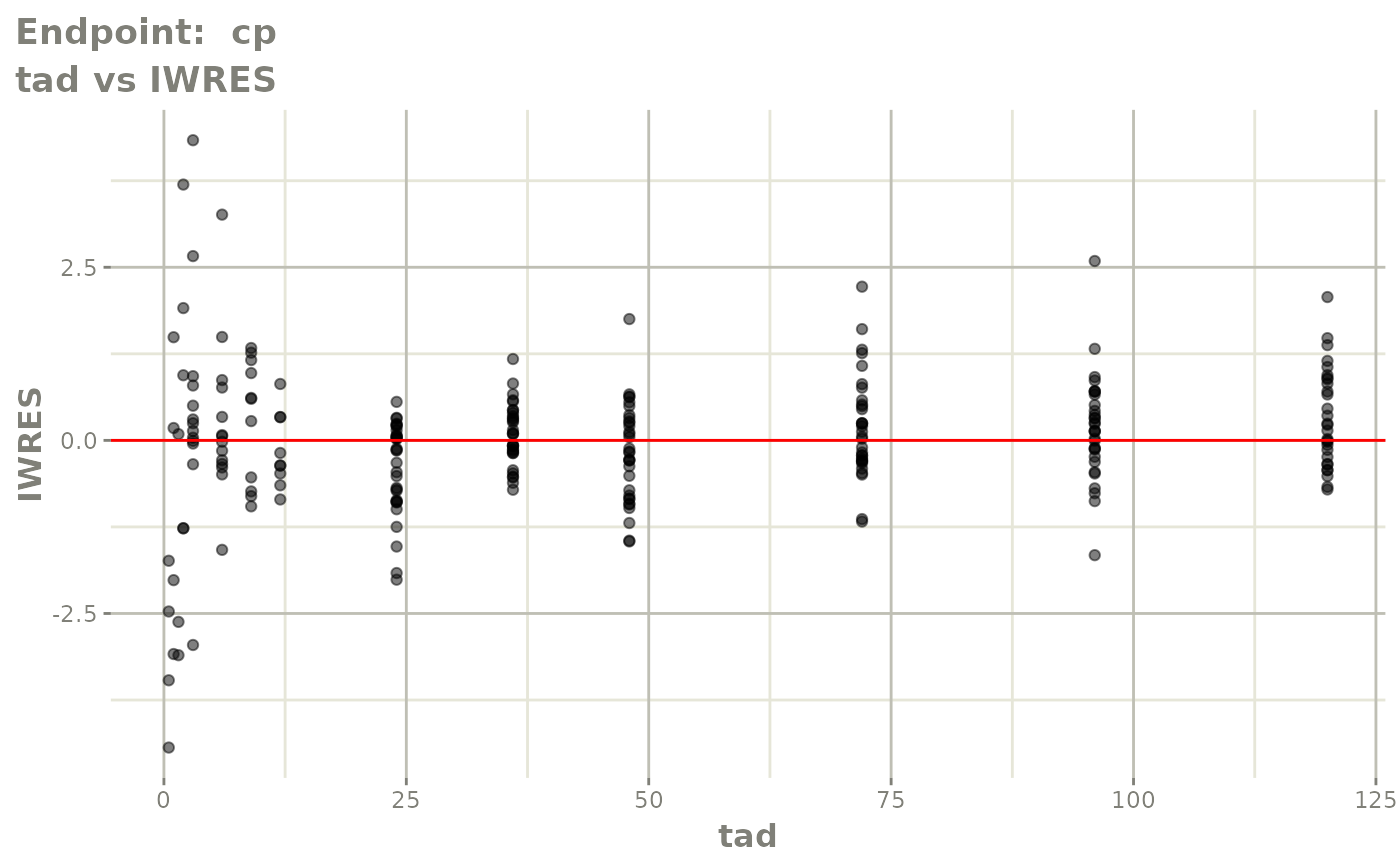
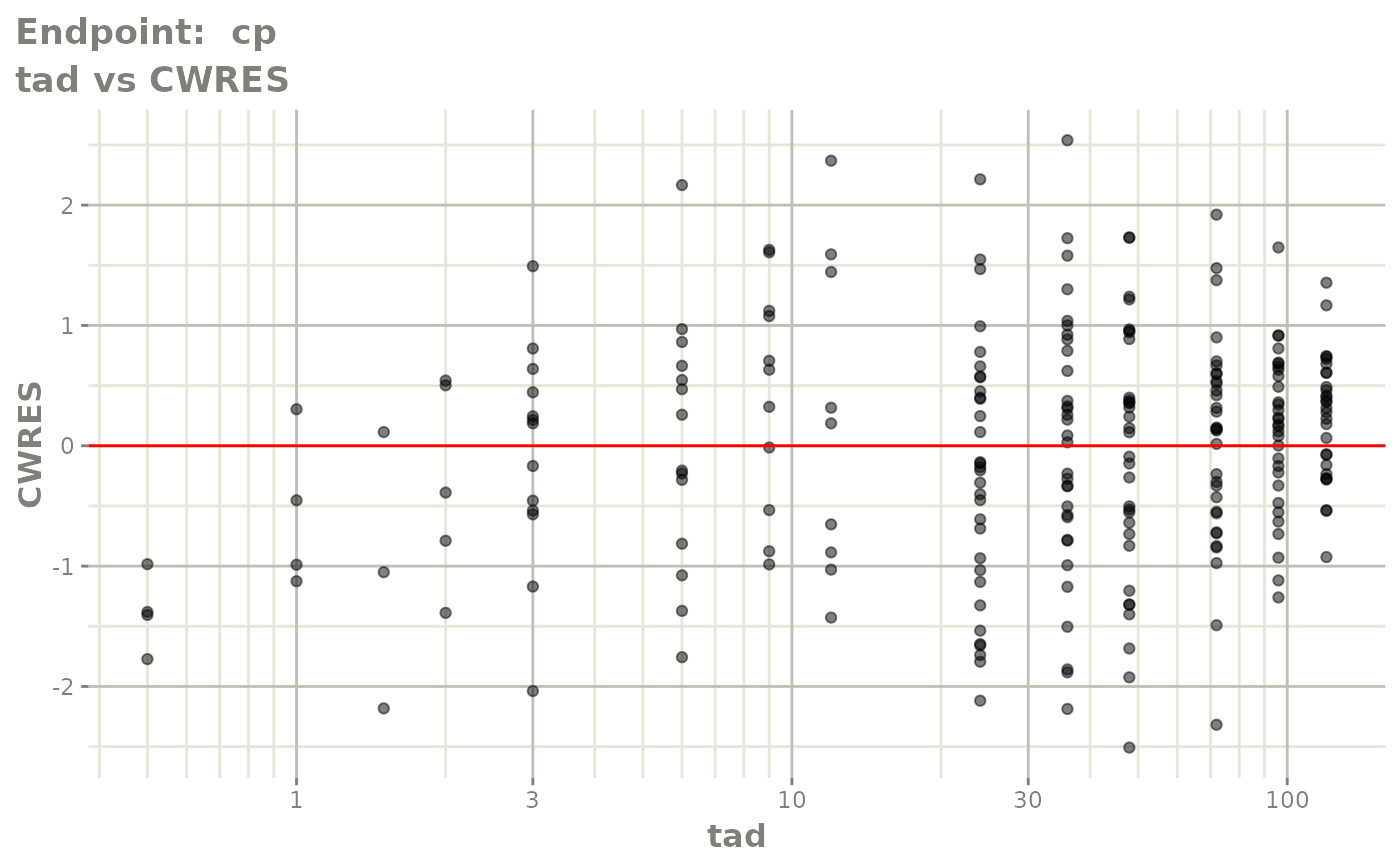
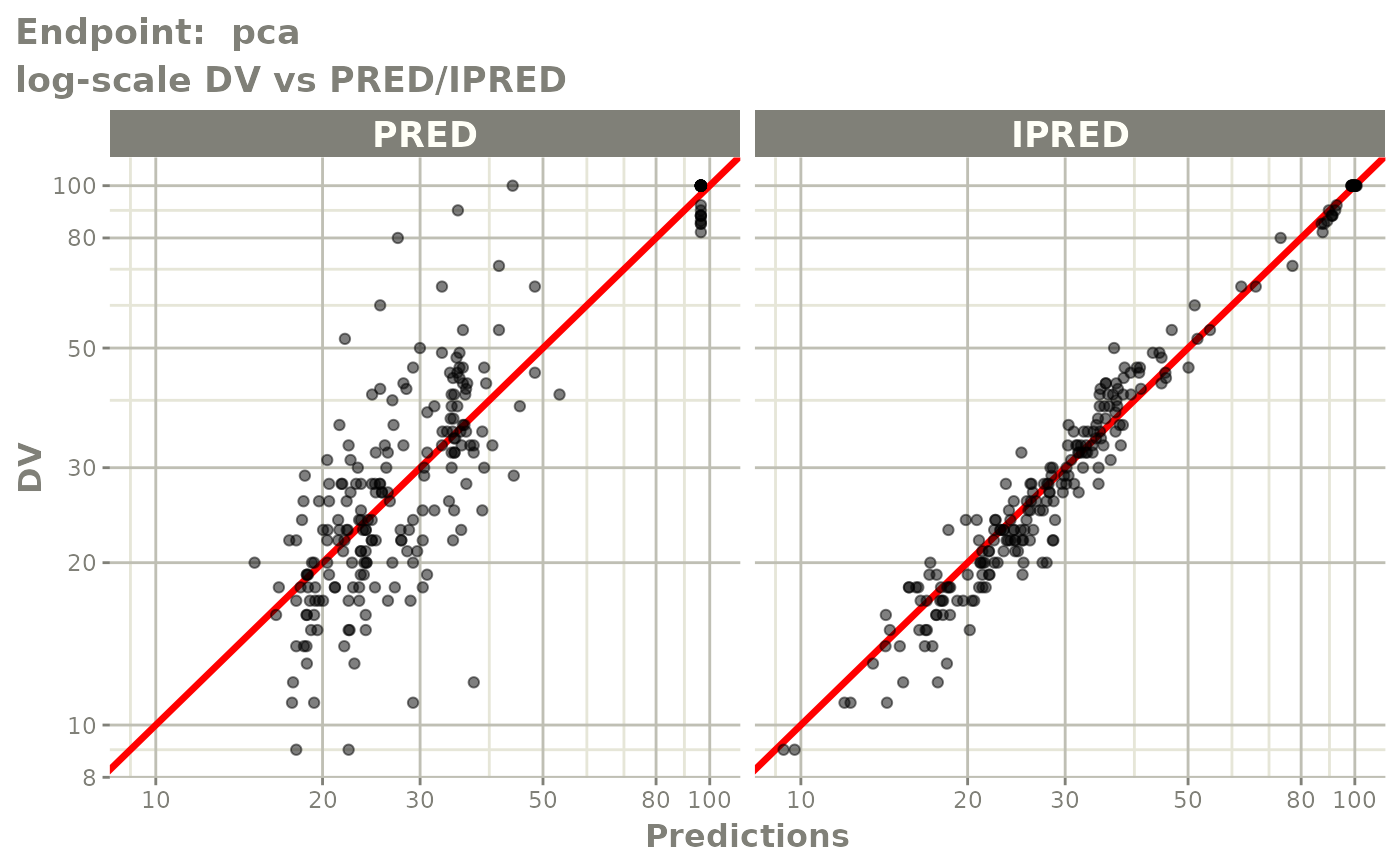
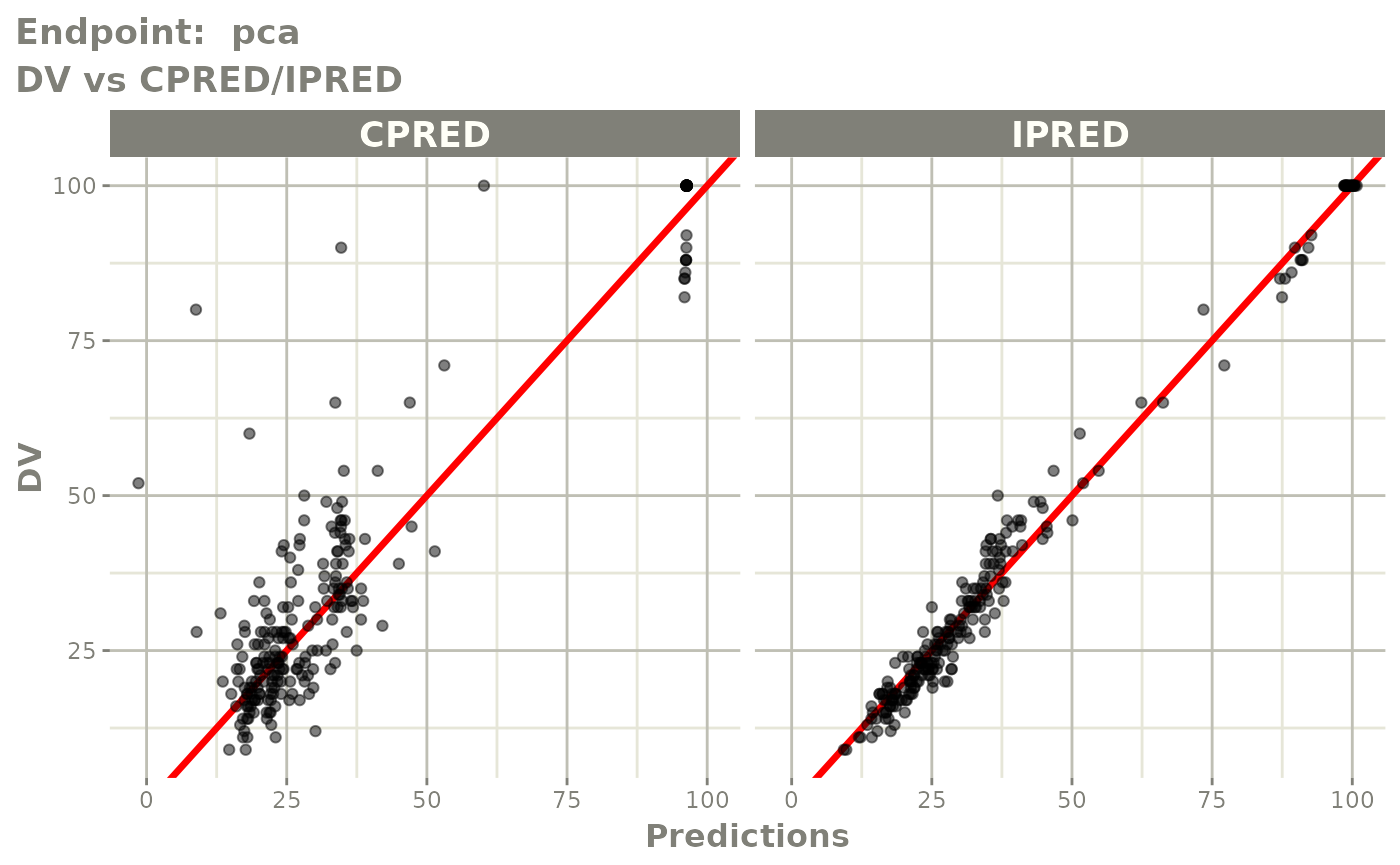
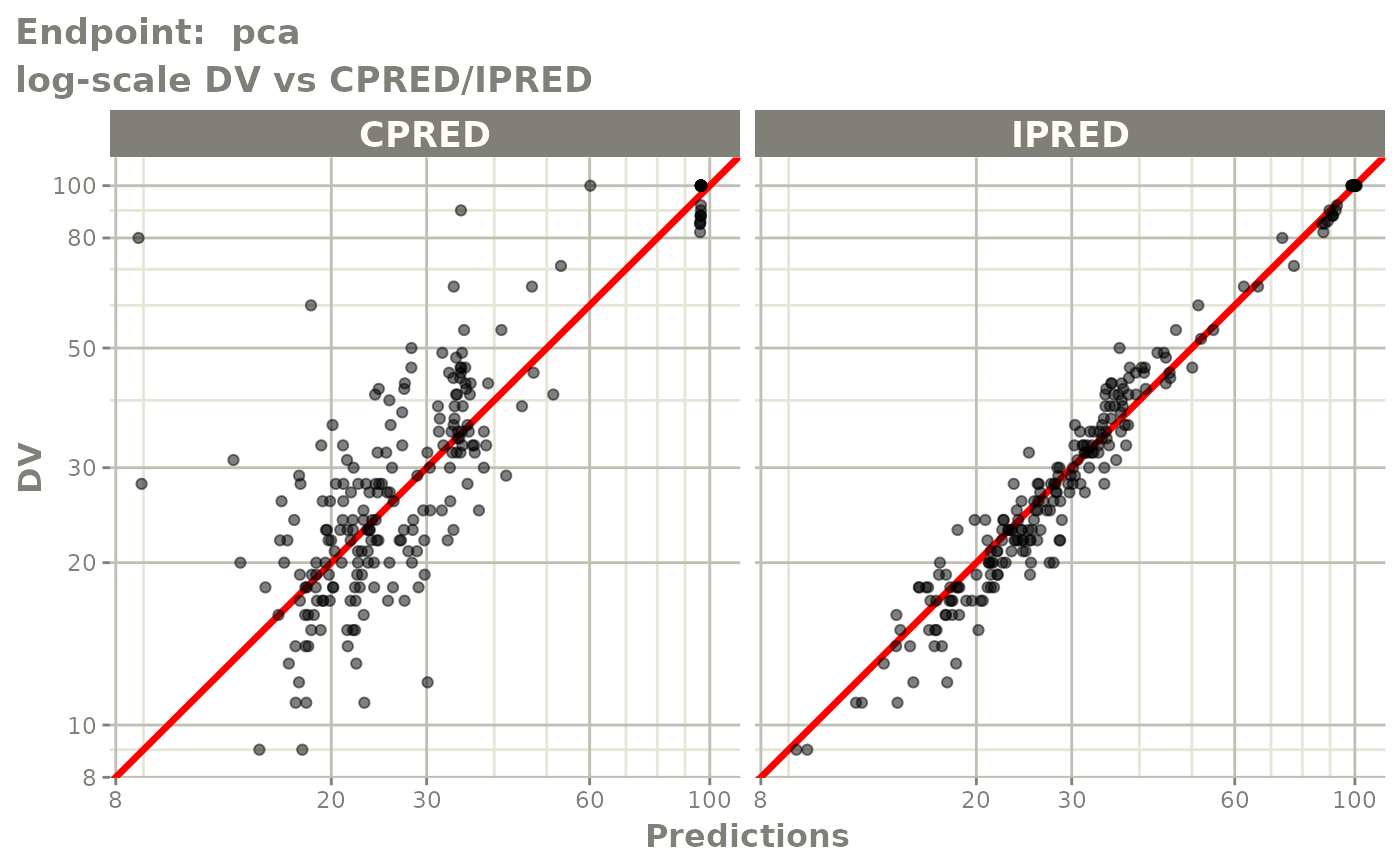
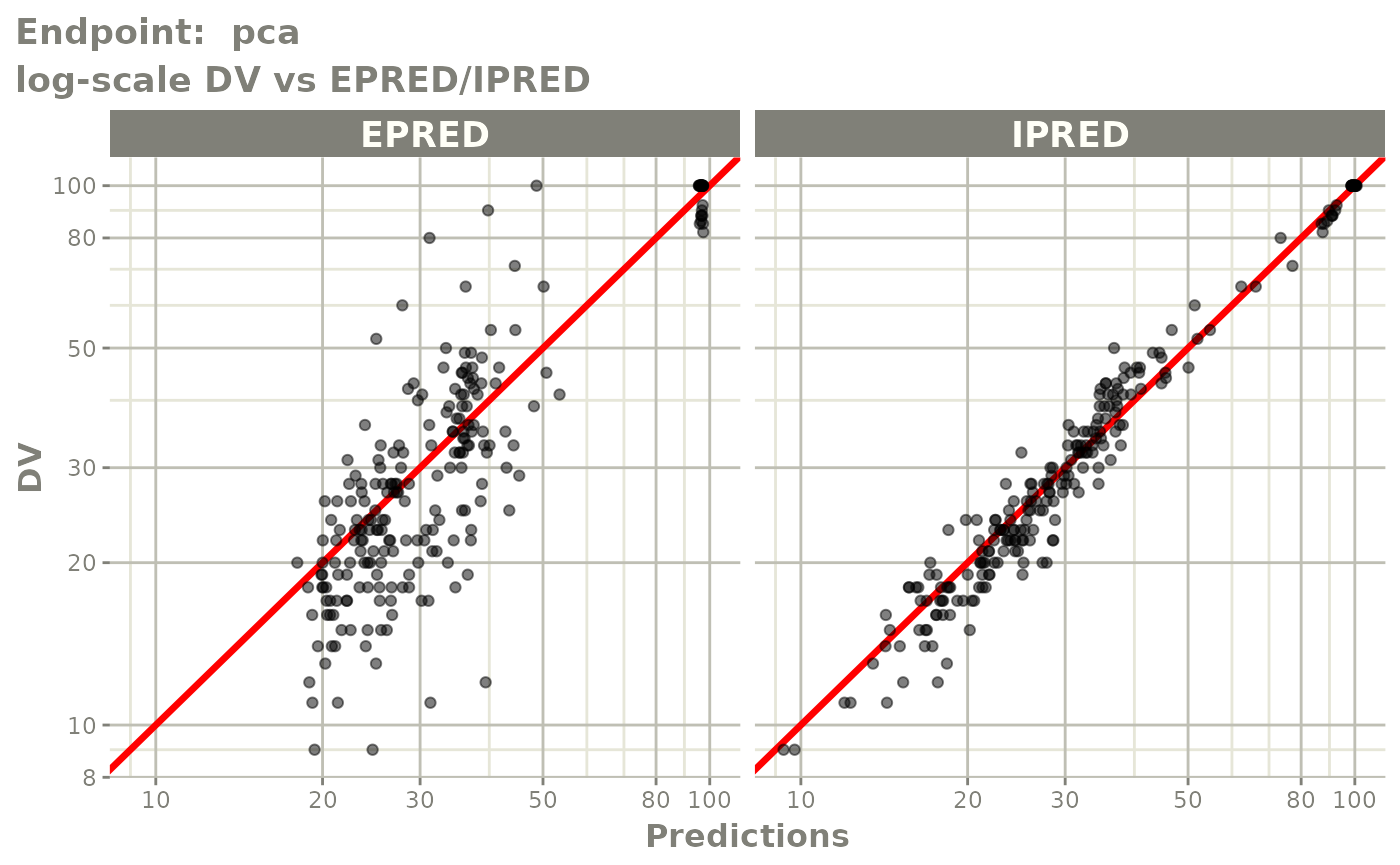
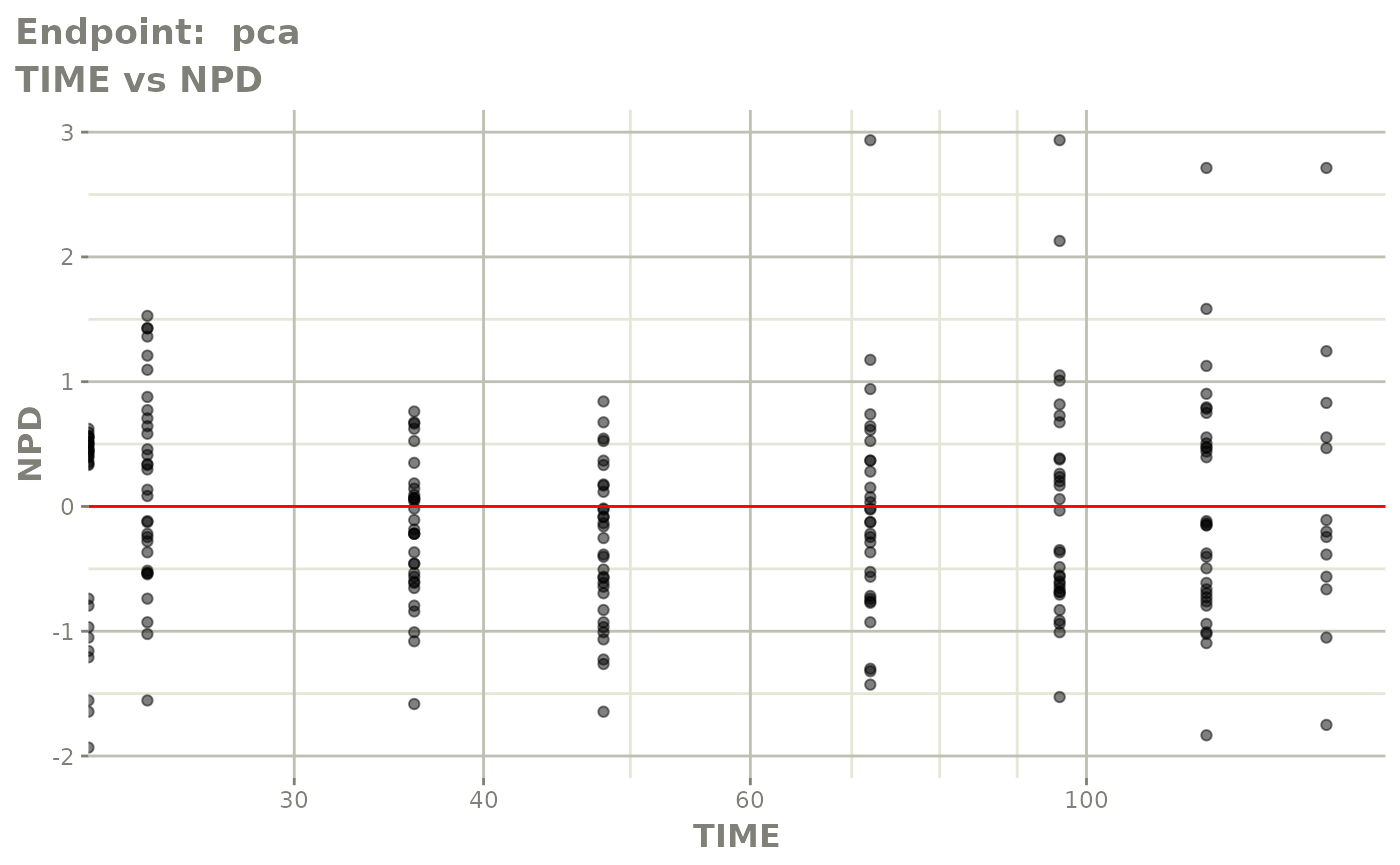
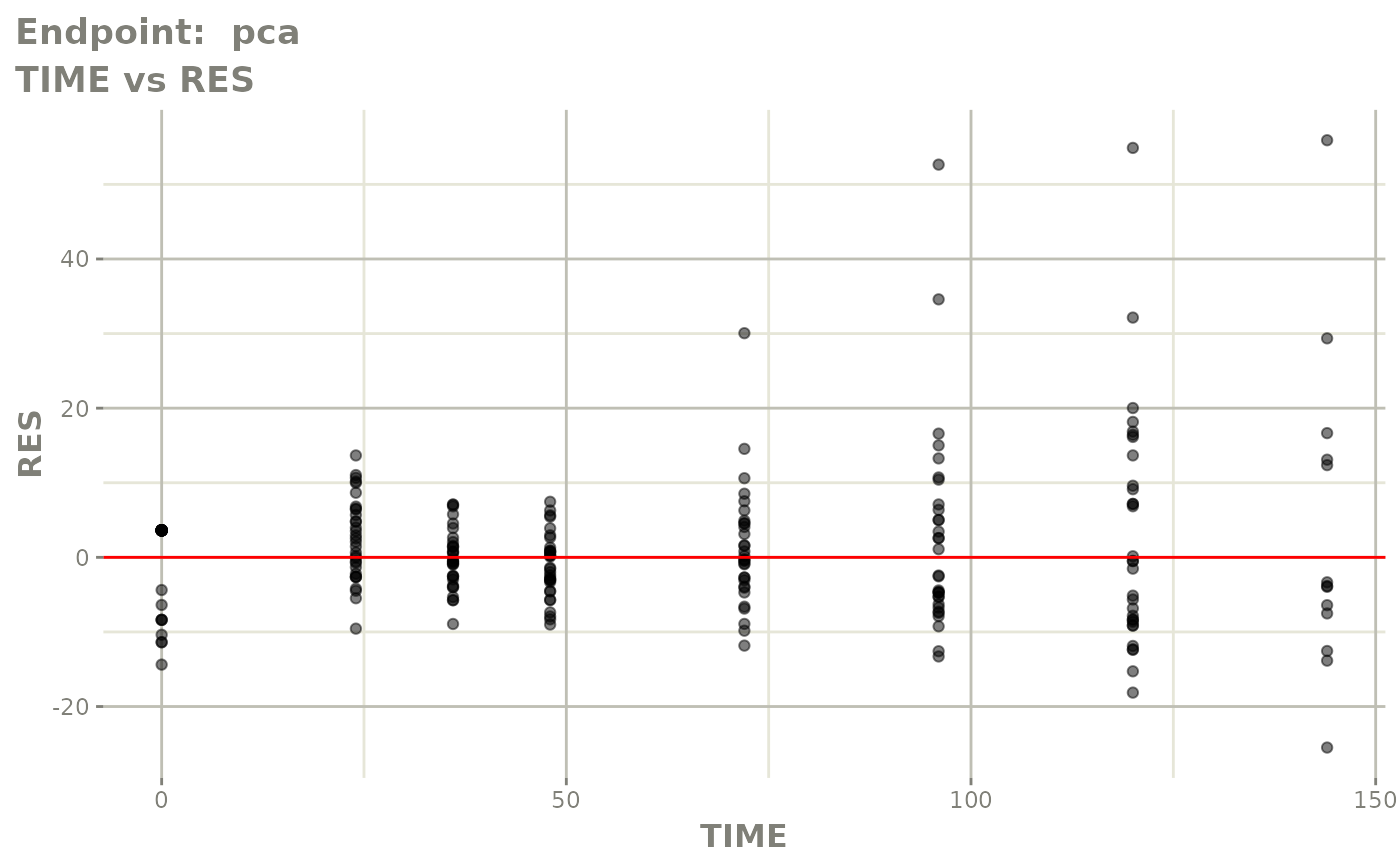
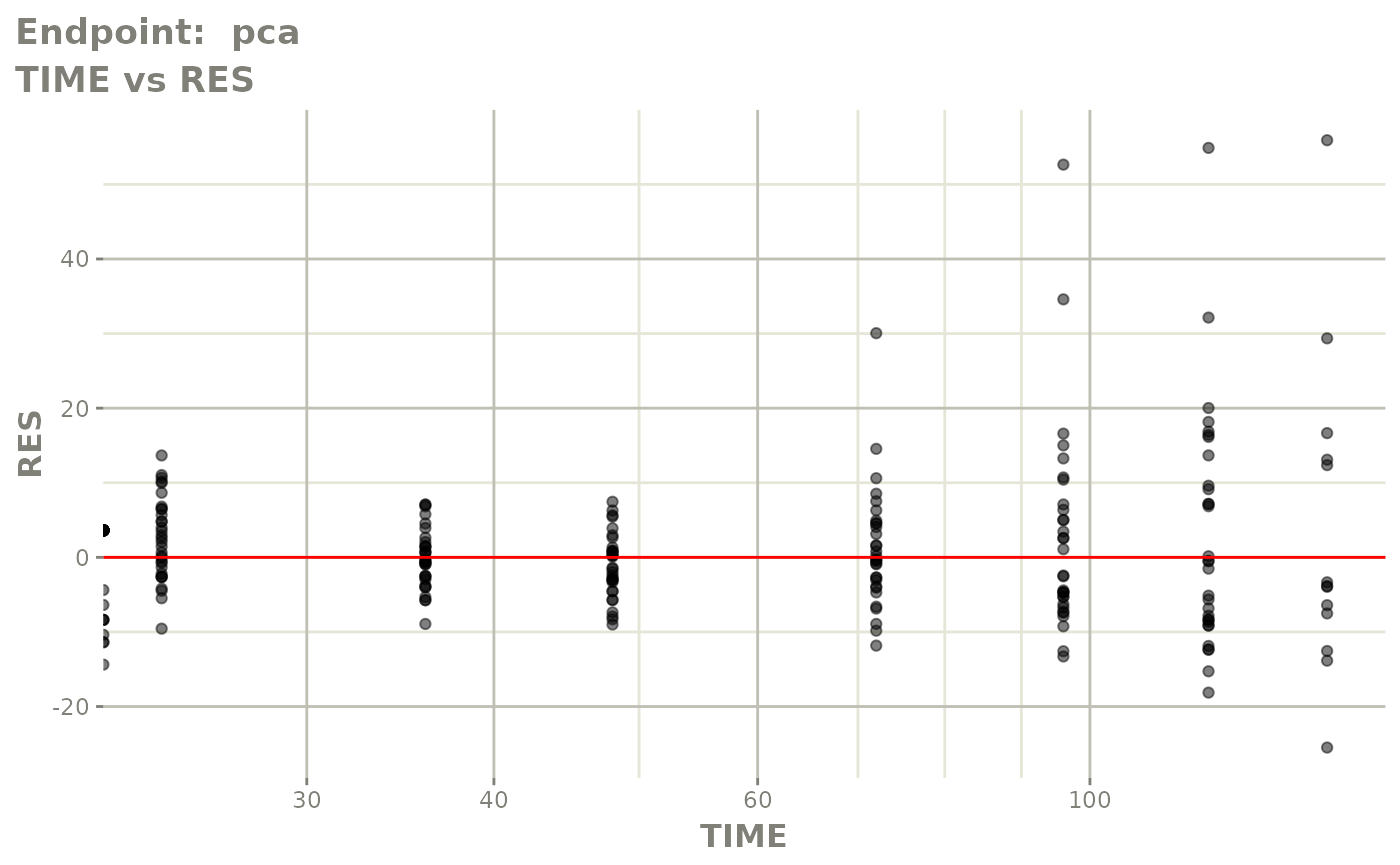
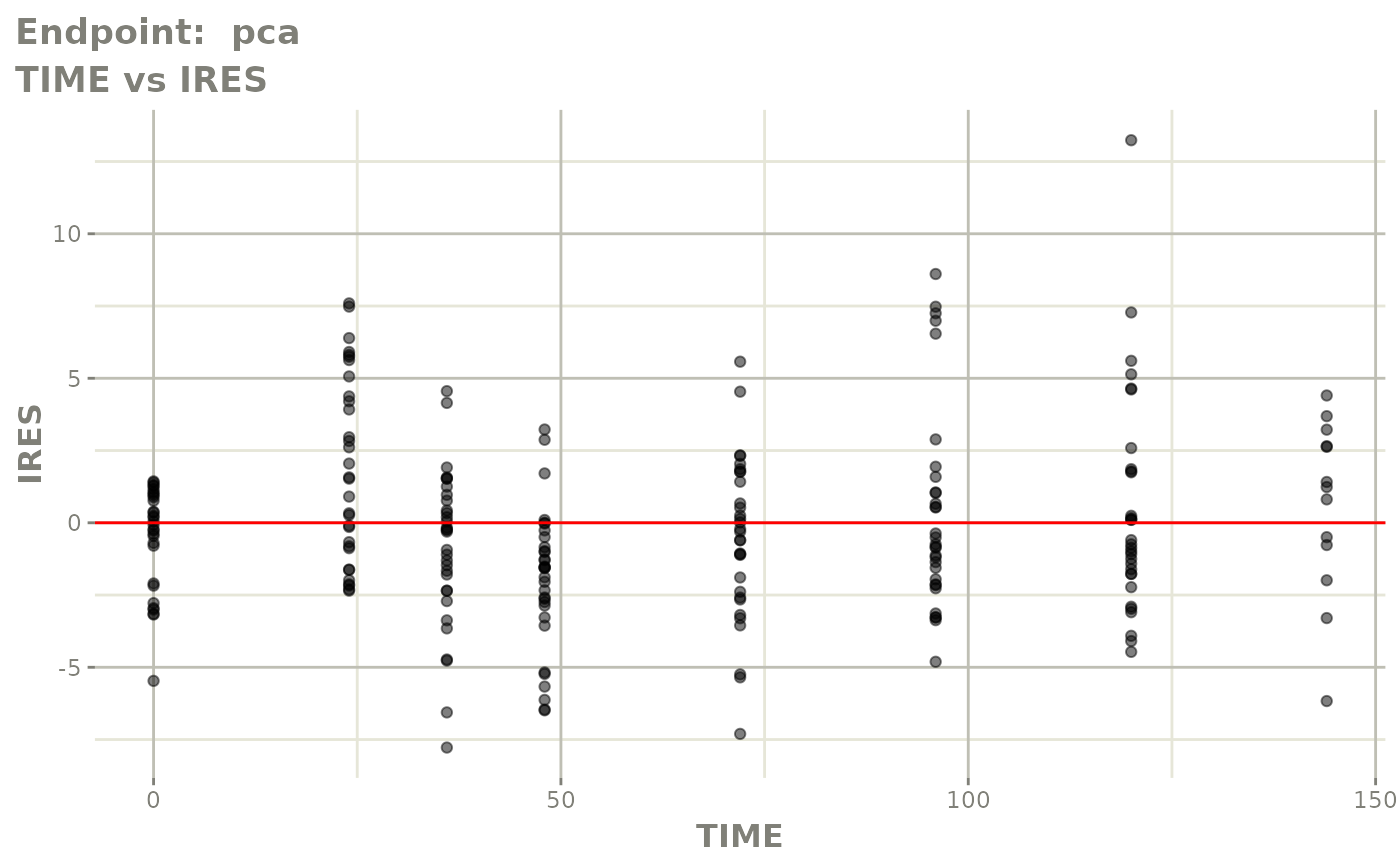
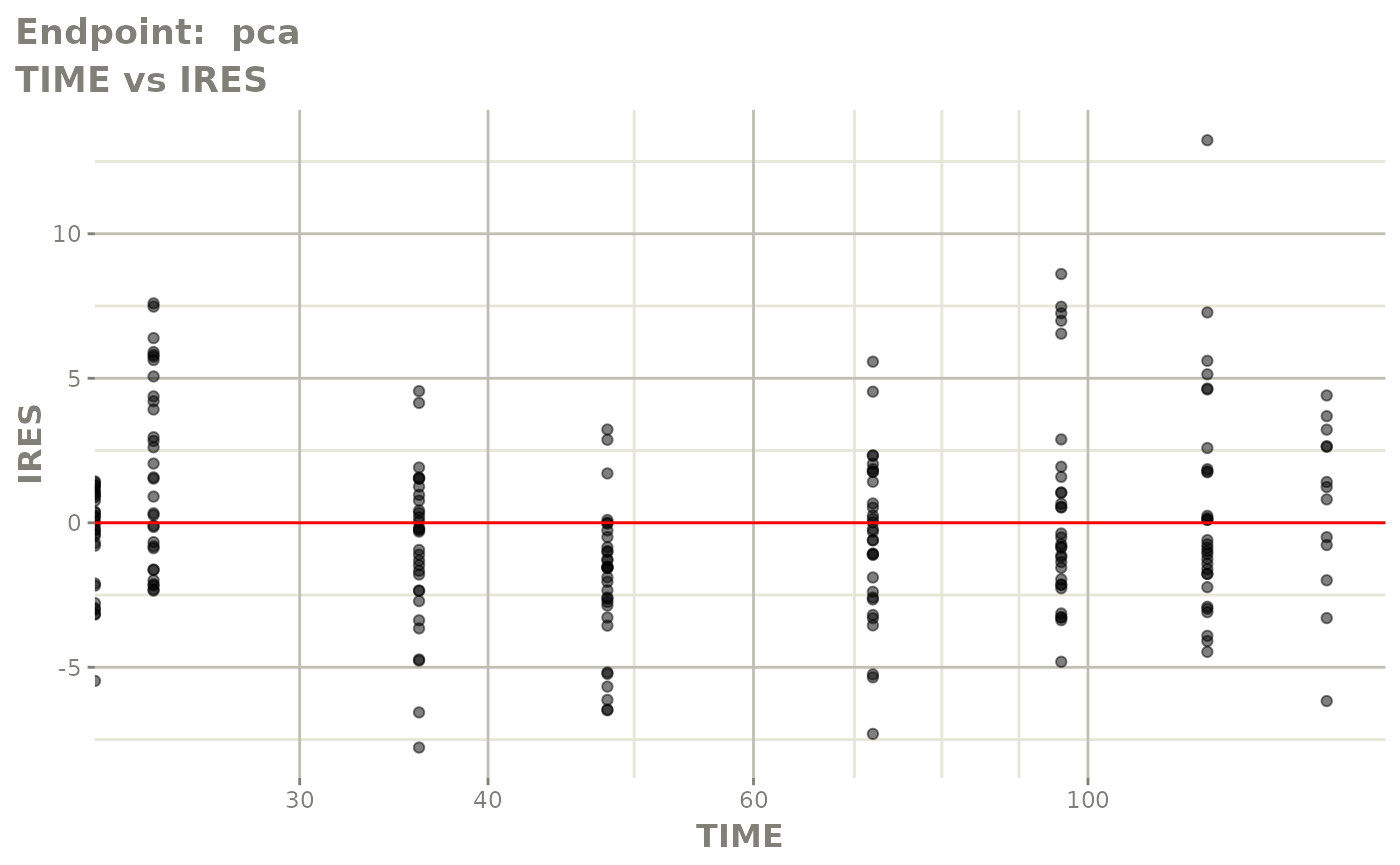
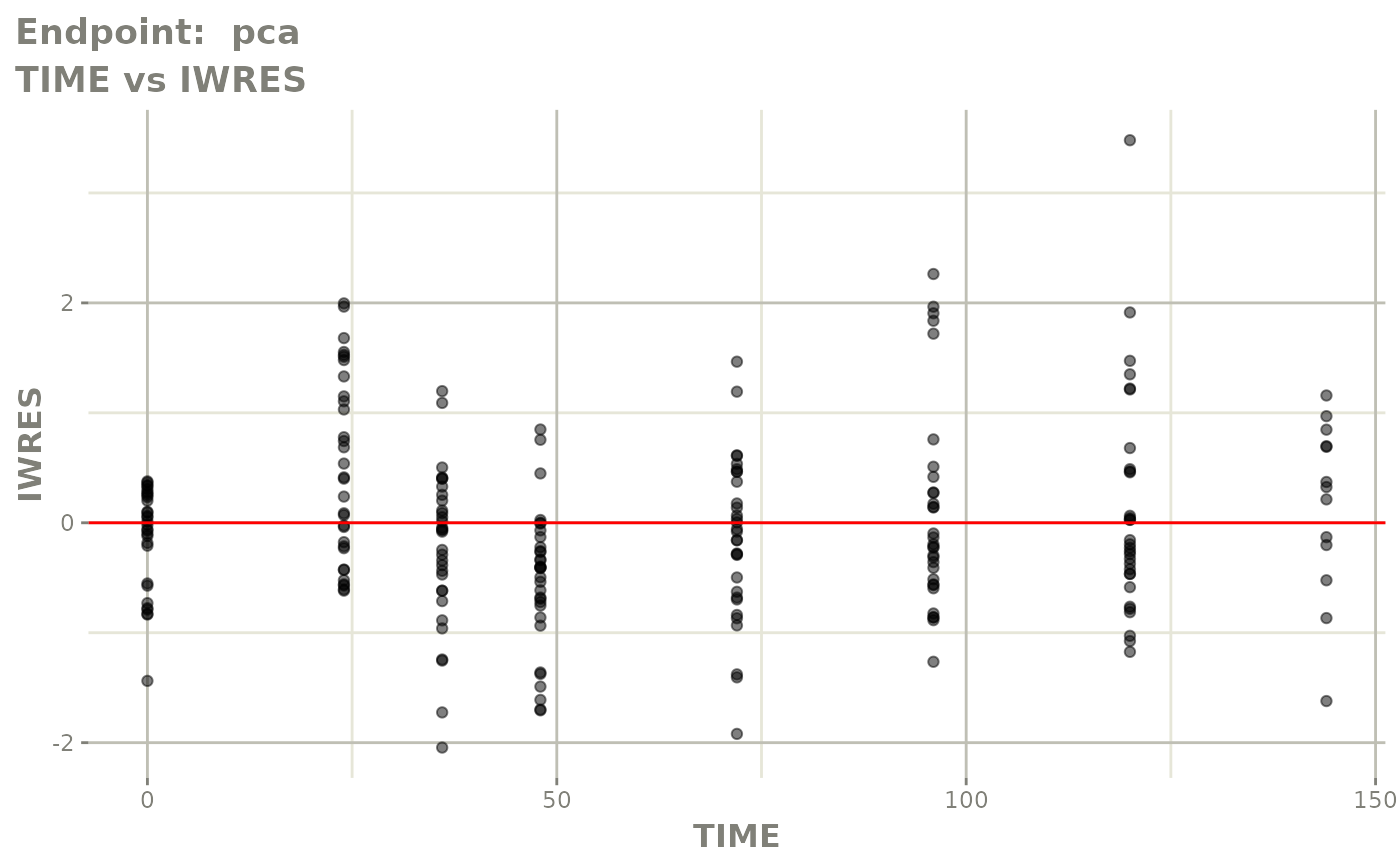
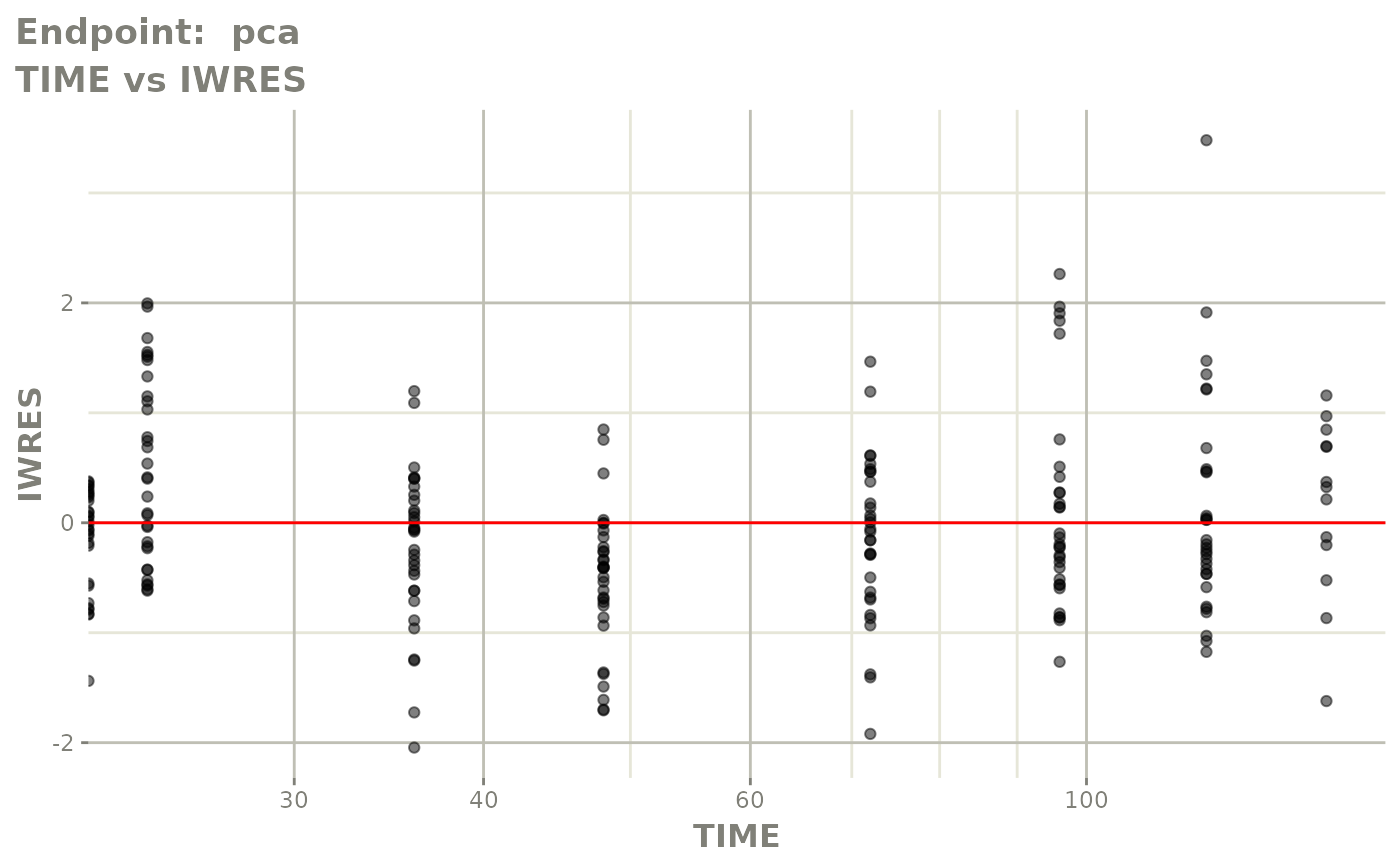
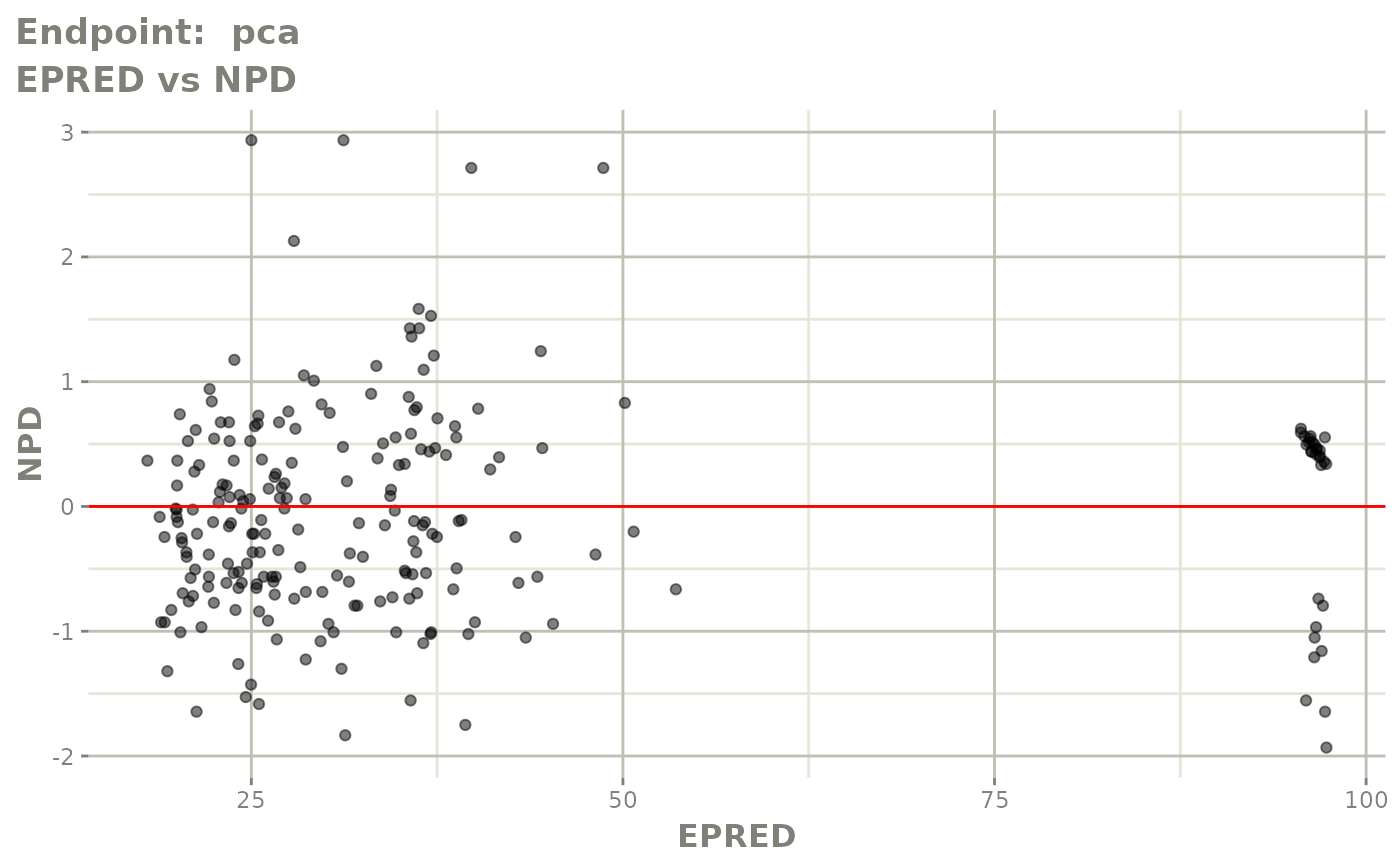
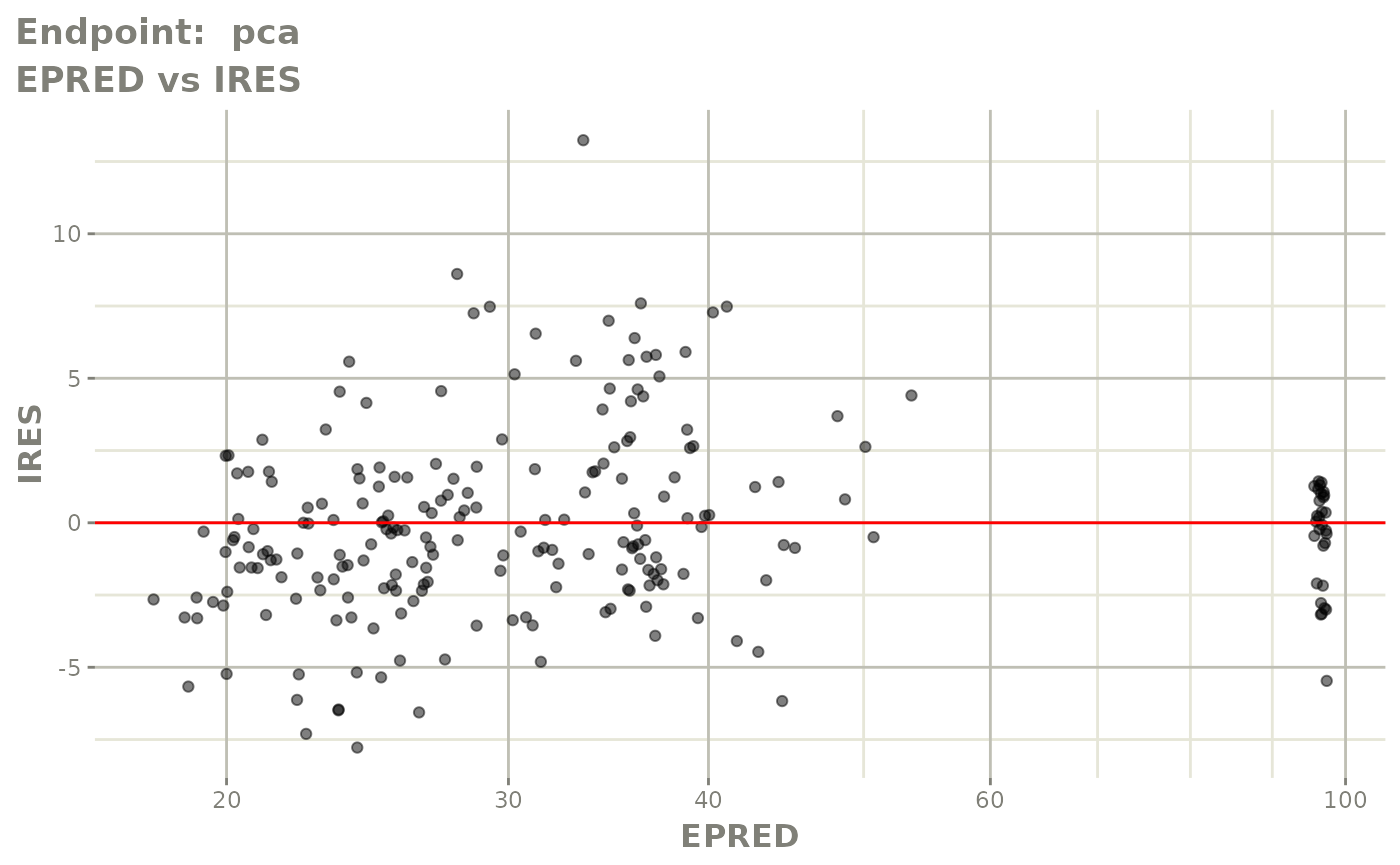
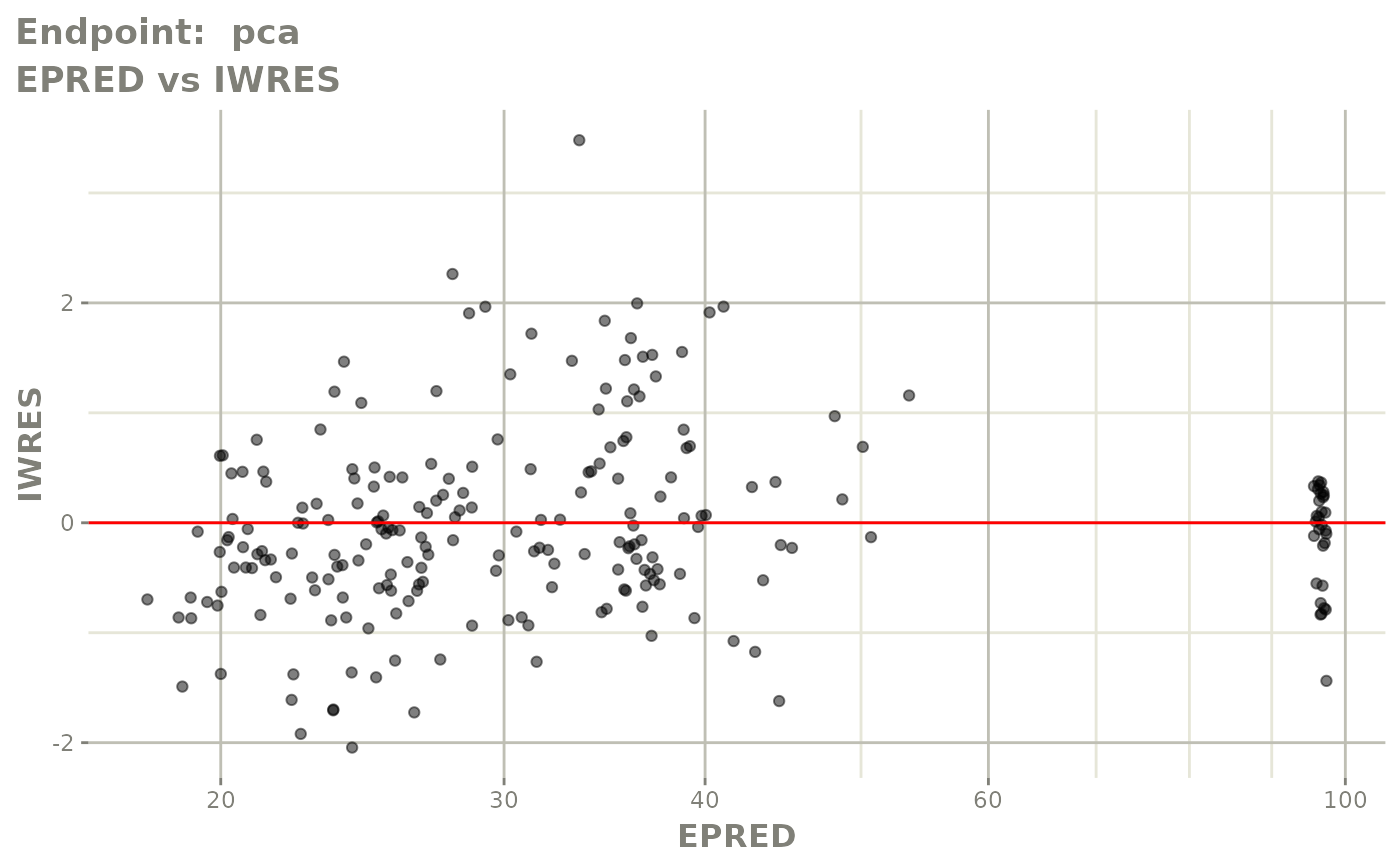
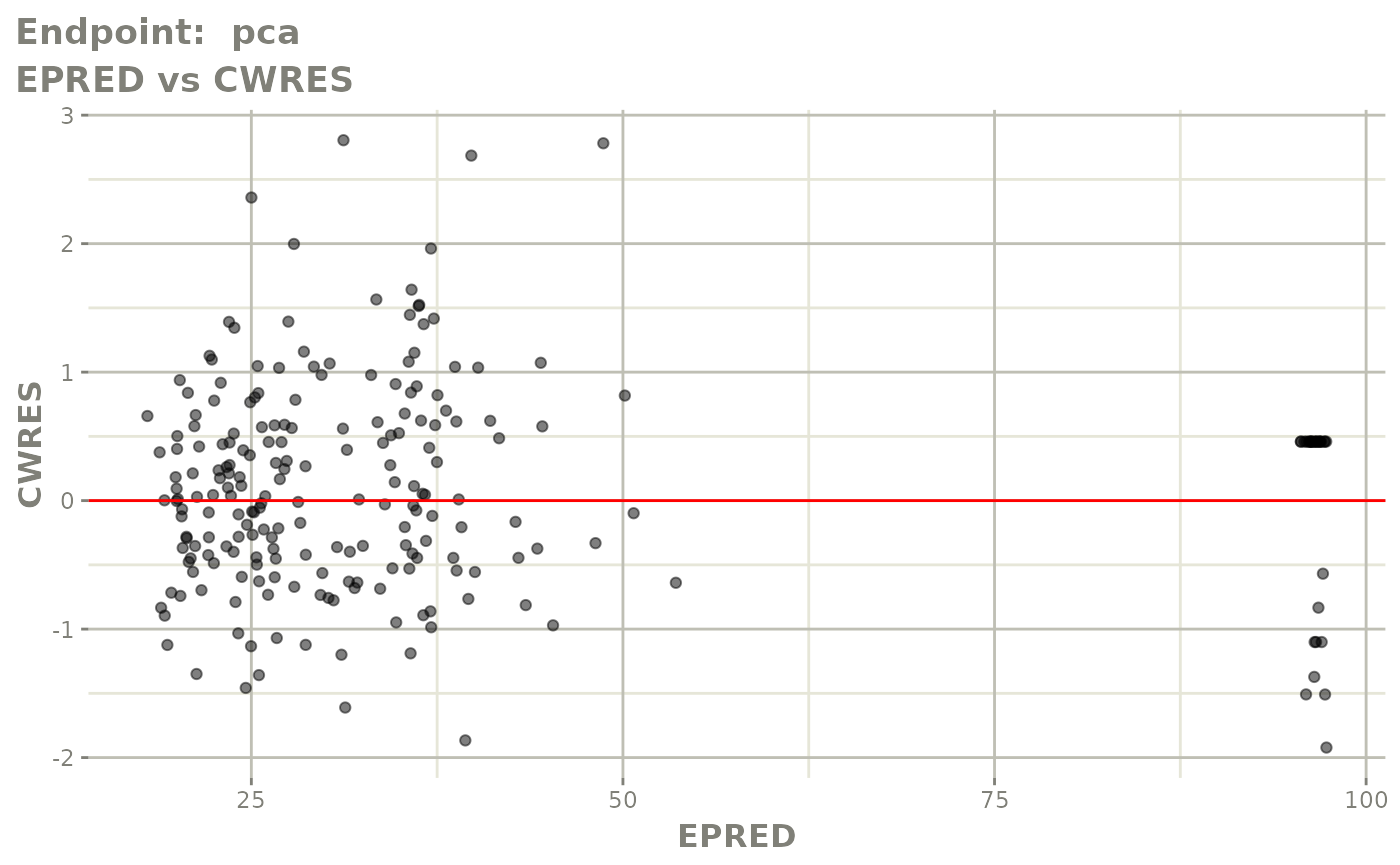
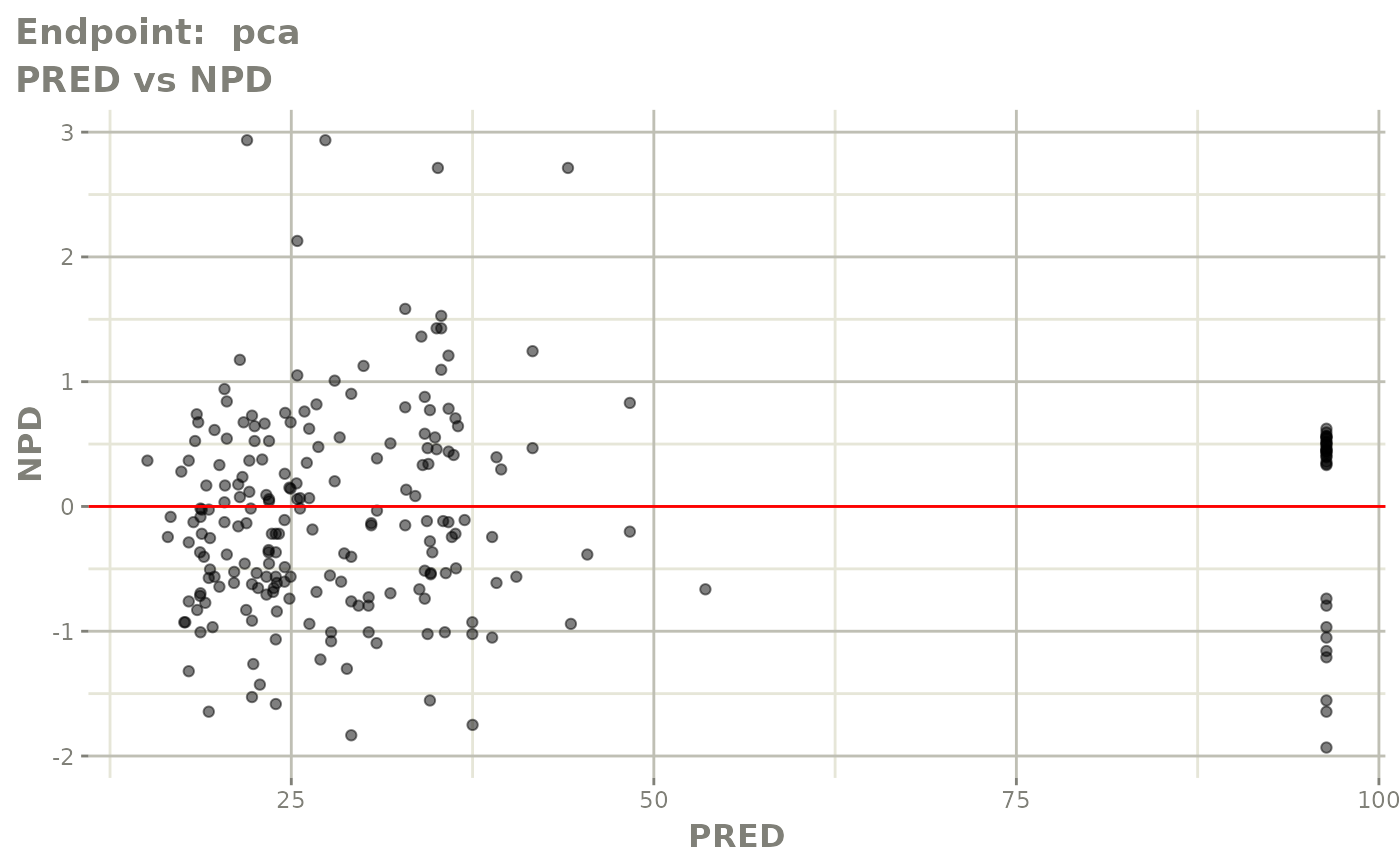
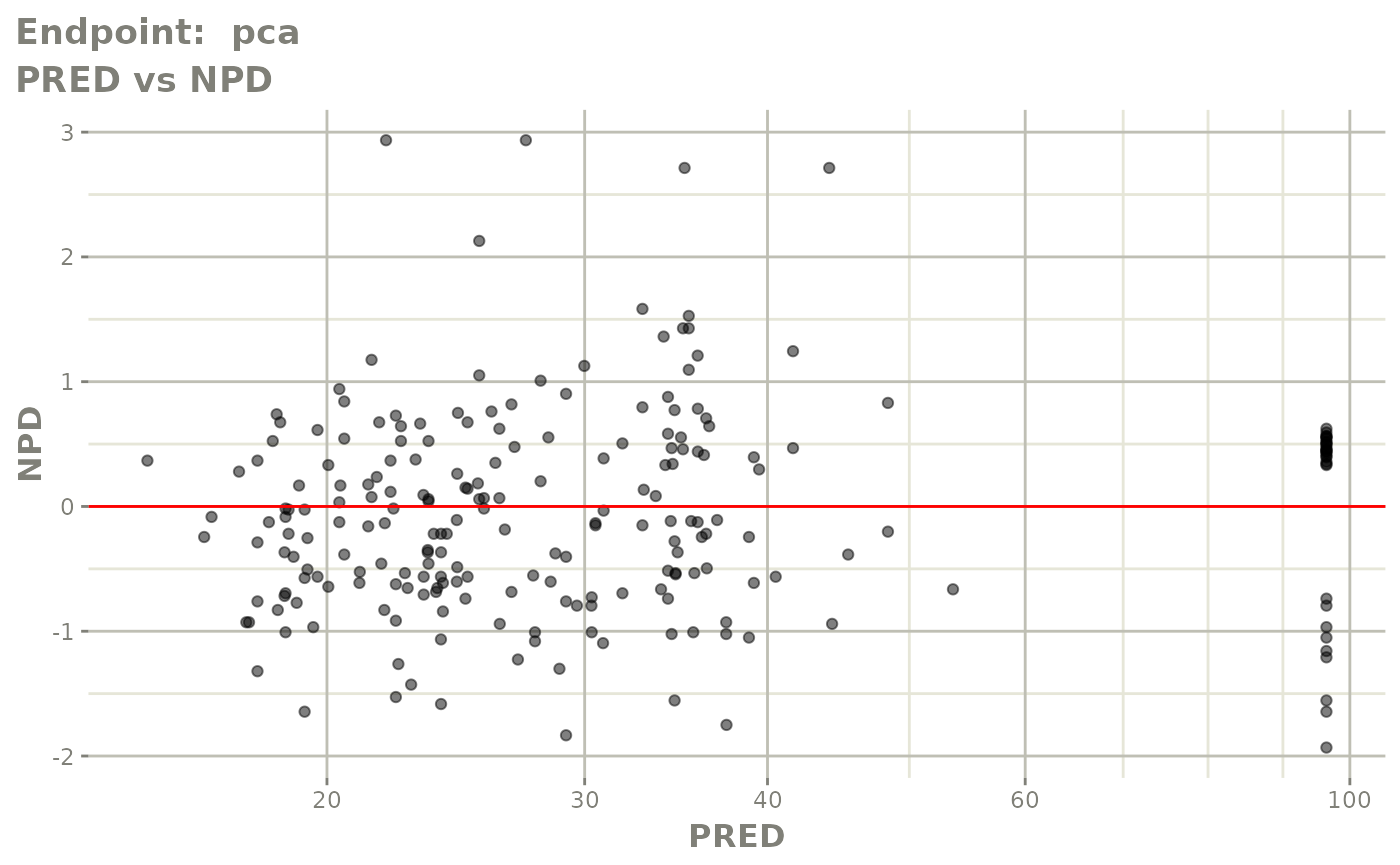
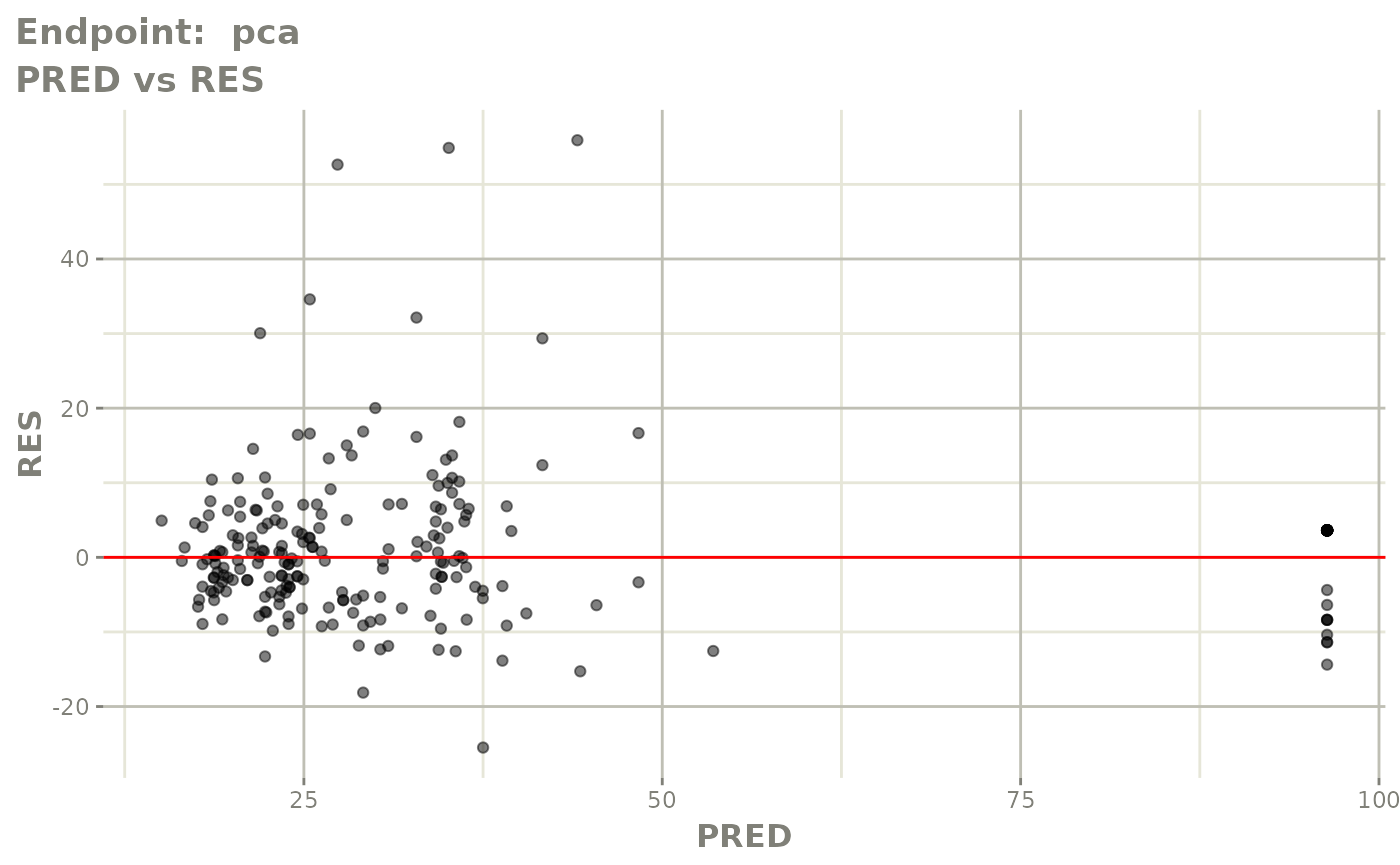
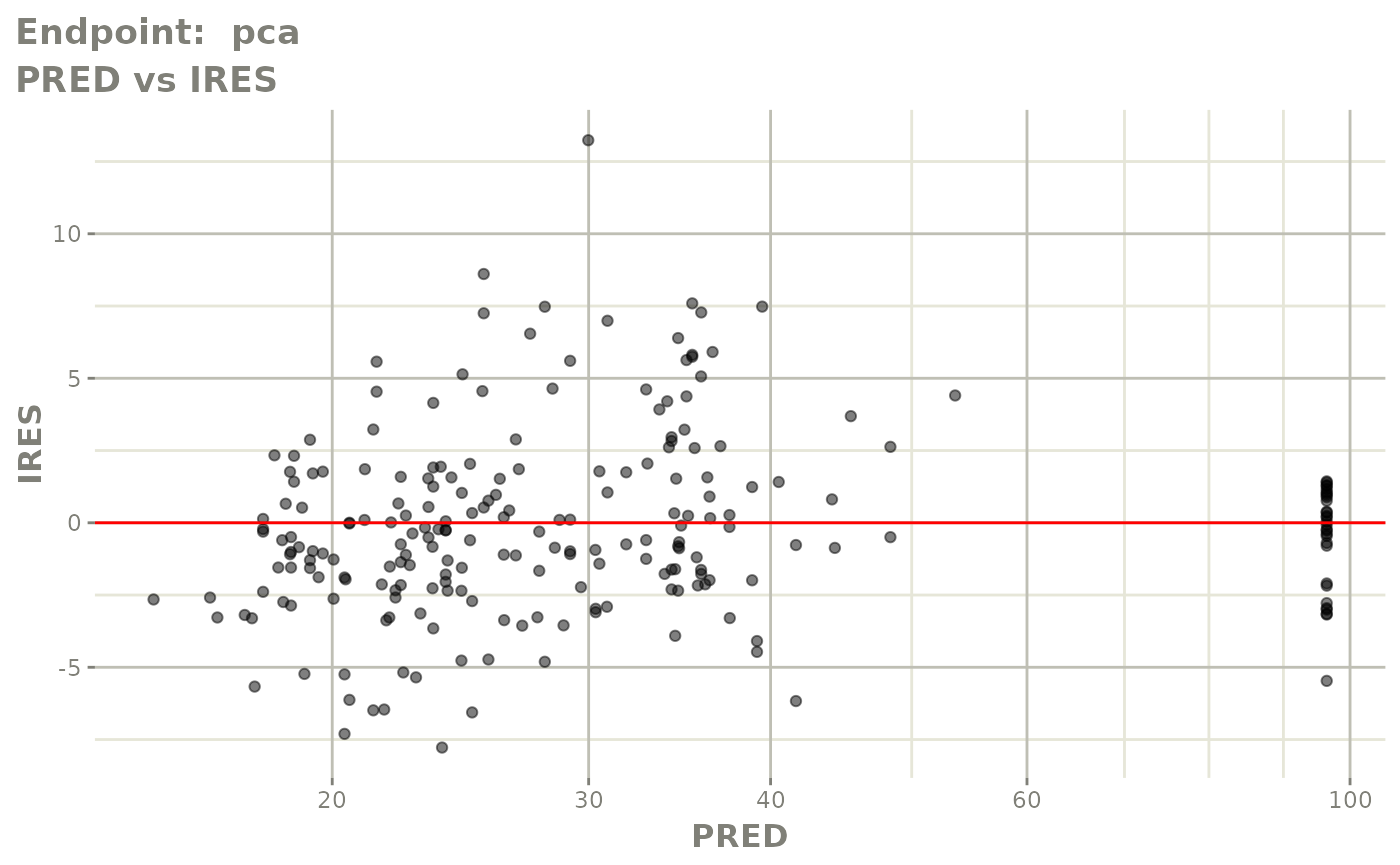
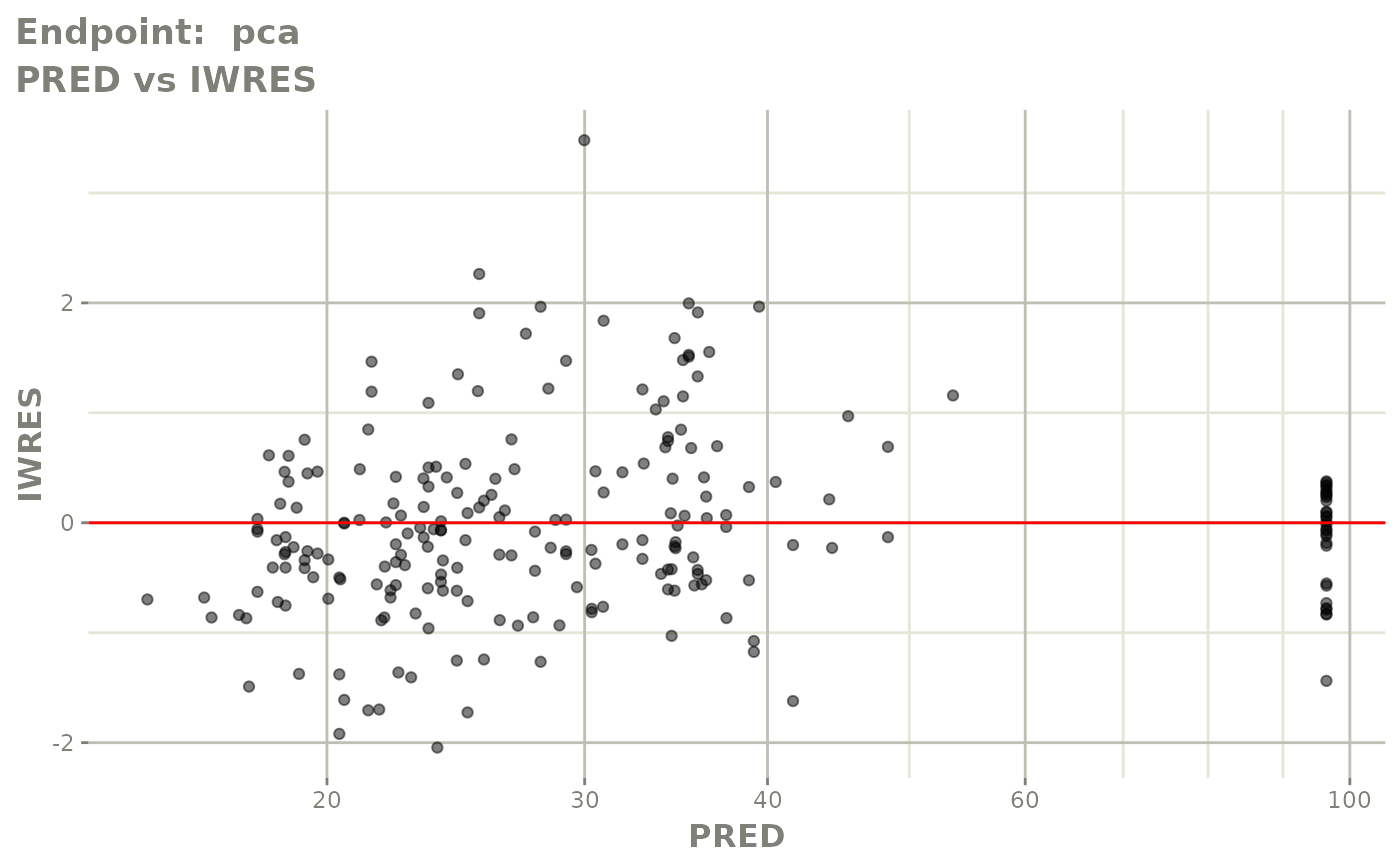
plot(fit.TOF)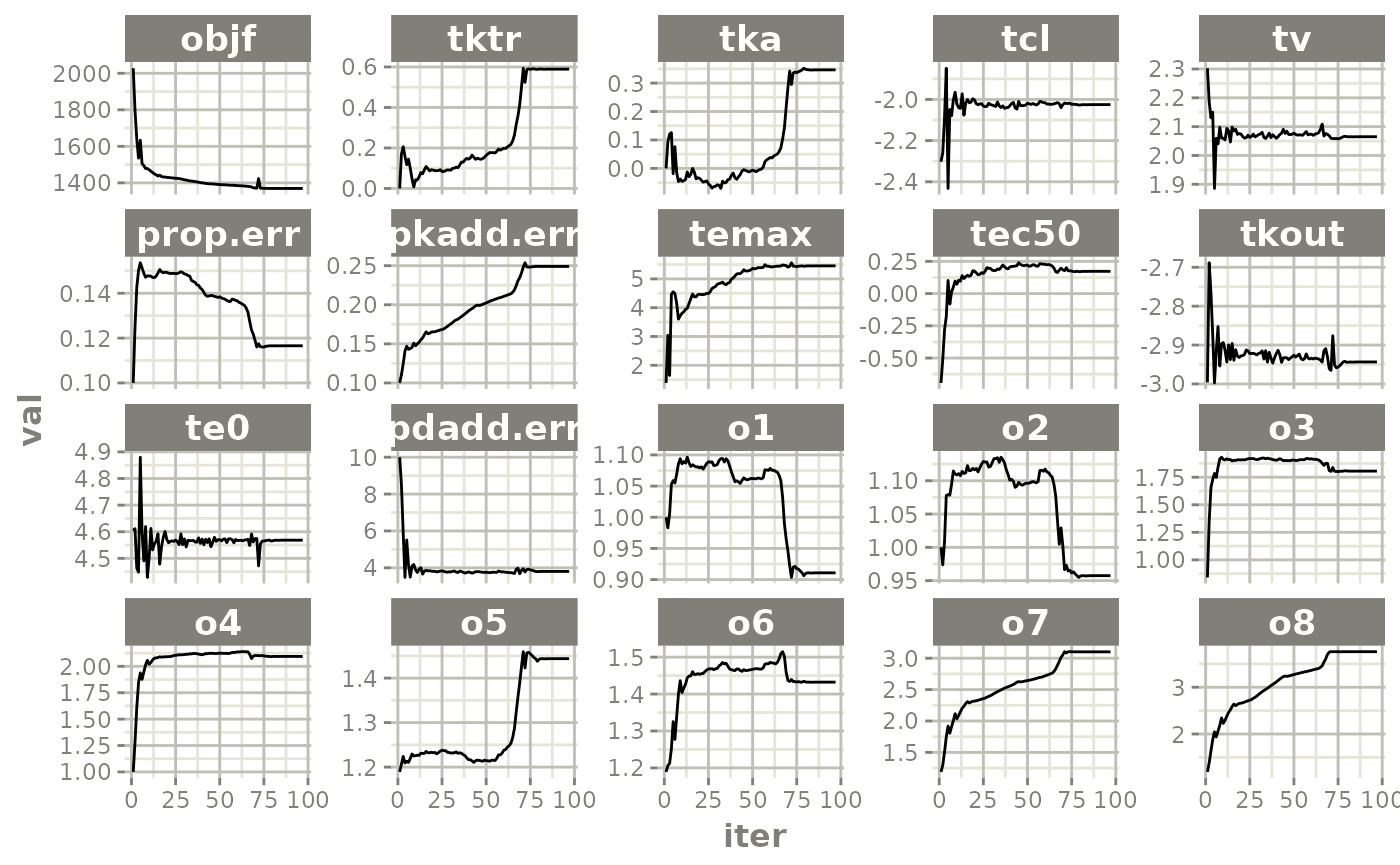






































v1f <- vpcPlot(fit.TOF, show=list(obs_dv=TRUE), scales="free_y") +
  ylab("Warfarin Cp [mg/L] or PCA") +
  xlab("Time [h]")

v2f <- vpcPlot(fit.TOF, show=list(obs_dv=TRUE), pred_corr = TRUE) +
  ylab("Prediction Corrected Warfarin Cp [mg/L] or PCA") +
  xlab("Time [h]")

v1f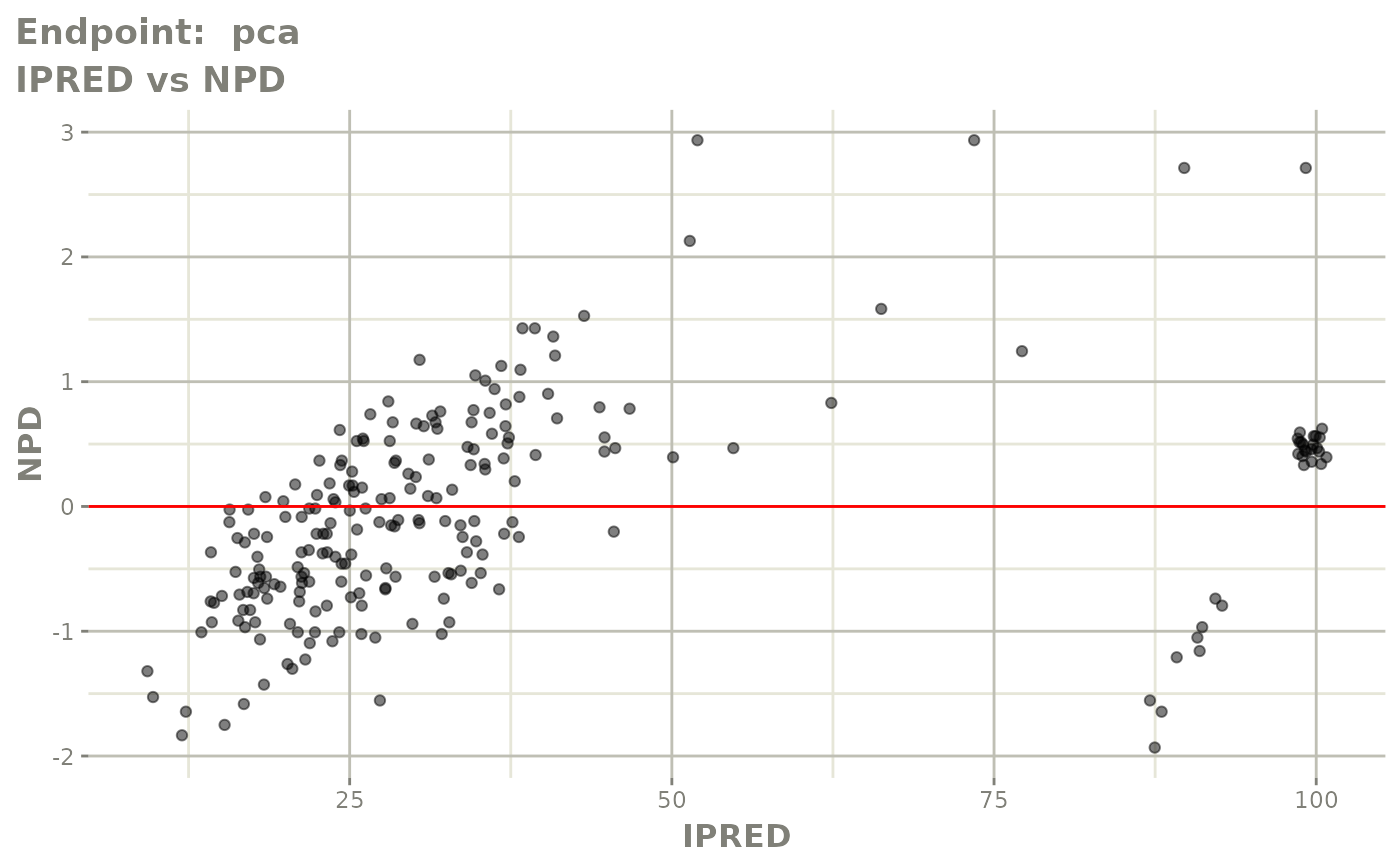
v2f